> This is part 1 of 7 of the full documentation (pages 1–100 of 655).
> The content is paginated: fetch every part to see all of it.
> Next part: https://computationaldocs.zeblok.com/info/llms-full.txt/1
> Page index: https://computationaldocs.zeblok.com/info/llms.txt

# About Zeblok Computational

The Zeblok Ai-WorkStation provides a single unified pre-configured environment for data scientists to access datasets, GPU-powered AI/ML frameworks, languages, and tools, with AI algorithms available from our Intelligence Marketplace. The Ai-WorkStation includes one GPU, one vCPU and 64 GB of storage, but scales easily as required. For more demanding workloads, the Zeblok Ai-HPC-WorkStation adds Slurm-as-a-Service and parallel processing, using worker nodes, by enabling the deployment of 4 or more GPUs.

The Zeblok Ai-WorkStation is built upon a Jupyter notebook, an interactive coding environment that lets you combine code with equations, visualisations, rich text, and other media. We make it easy to explore data and coding concepts and collaborate with other people on data science projects.


# Core Concepts

### Ai-MicroCloud™

Ai-MicroCloud™ provides a single, cohesive, turnkey, cloud native AI environment for development, testing, training and deployment of an end-to-end AI/ML solution to production from Core to Edge.

It saves 12-18 months of engineering effort to integrate the multitude of technologies, countless hours of business effort to establish a compatible and collaborative AI ecosystem, and reduces GTM for ISVs by 8-12 months.

[Learn More...](https://www.computational.zeblok.com/ai-microcloud)

### JupyterLab: Jupyter’s Next-Generation Notebook Interface

JupyterLab is a web-based interactive development environment for Jupyter notebooks, code, and data. JupyterLab is flexible: configure and arrange the user interface to support a wide range of workflows in data science, scientific computing, and machine learning. JupyterLab is extensible and modular: write plugins that add new components and integrate with existing ones.

### The Jupyter Notebook

The Jupyter Notebook is an open-source web application that allows you to create and share documents that contain live code, equations, visualizations and narrative text. Uses include: data cleaning and transformation, numerical simulation, statistical modeling, data visualization, machine learning, and much more.

### Ai- WorkStation

The Zeblok Ai-WorkStation provides a single unified environment, which seamlessly orchestrates infrastructure, open source AI/ML frameworks and proven, original AI algorithms. An intuitive and simple user interface enables a data scientist, data engineer, or AI engineer to access petaFLOPS of computing power, efficiently develop and train new AI models and take them to production in a runtime environment on the same platform, with consummate ease.

[Learn More...](https://www.computational.zeblok.com/aiworkstation)

### Intelligence Marketplace

Zeblok’s Intelligence Marketplace provides easy access to a growing library of proven, original AI algorithms. Quality is ensured by our curation process, including closed loop validation, providing algorithm creators with a means of commercialization not previously available. We ensure that algorithms are easy to read, easy to use and easy to share. These include:

* Ai-Rover™ Notebook: Data Comprehension/Visualization Tool
* Ai-Rover™ Notebook For Time Series Data: Automated Predictive Model Builder&#x20;

[Learn More...](https://computationaldocs.zeblok.com/zeblok-computational-1/marketplace/intelligence-marketplace)

### Ai-HPC-WorkStation

Zeblok enables you to seamlessly scale to high-performance computing (HPC). Access HPC resources via a Jupyter Notebook.

One-click scalability for AI workloads.

### Ai-Data Lake

A data lake is a centralized repository that allows you to store all your structured and unstructured data at any scale. Zeblok Ai-Data Lake is a high-performance data-store that allows you to import, filter, and instantly analyze objects. Our solution is designed for performance, scales up with your data, and can provide industry-grade SSL security and data-redundancy for high availability of data at SSD speeds.

[Learn More...](https://computationaldocs.zeblok.com/zeblok-computational-1/data-and-metrics/datalake)

### Ai-APIᵀᴹ

Getting machine learning models into production is hard. Data scientists are not experts in building production services and DevOps best practices. The trained models produced by a data science team are hard to test and hard to deploy. This often leads to a time consuming and error-prone workflow, where a pickled model or weights file is handed over to a software engineering team.

Zeblok’s Ai-API™ Engine resides within Zeblok’s Ai-MicroCloud™ to facilitate deploying trained machine learning models anywhere. It bridges the gap between data science and DevOps, enabling teams to deliver AI inferences in a fast, repeatable and scalable way.&#x20;

[Learn More...](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/introduction)

### Ai-MicroCloudᵀᴹ Manager

Ai-MicroCloud™ Manager is the centralized management utility for Ai-MicroCloud™ and is used to manage and orchestrate all dependent components for Ai-WorkStation, Ai-HPC-WorkStation, Ai-Data Lake, Intelligence Maketplace and the Ai-API™ Engine.&#x20;

The Ai-MicroCloud™ Manager enables the enterprise administrator to define role-based access control, infrastructure plans (vCPUs, GPUs, memory, storage), define Namespaces and add accessible data centers, and provides metering information for resource utilization monitoring, billing or charge back purposes.<br>


# Create an Account


# Individual User

Individual User Signup Process

Click on this link <https://app.zbl-aws.zeblok.com/signup> to create an account with Zeblok Computational. You will be redirected to the Zeblok Computational Individual Signup page.

![Individual Signup Page](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FNEoiRHTPaONZj2m7rACu%2Fimage.png?alt=media\&token=41e19c7b-2525-4e15-934b-e0e97d9ad817)

Enter the required details and follow the further instructions which will be sent to your e-mail after signup details' validity processing.

After entering all the credentials as shown below . click on signup button and you will see this notification on the top . **Welcome to the Zeblok Computational AI Platform. Please check your email for an account activation link to complete your registration.**

![Fill all the Credentials](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FOjf7Fofa91GGR6lU3fTg%2Fimage.png?alt=media\&token=5a201daf-b8d2-47ee-9e61-440edb069734)

After that go to the registered email id used while signing up and click on the link which is send to your registered email id

![Click on Link button ](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfHr2Wk9ohN_vRYxzNb%2F-MfJ-mPvPmphl7ADv3z6%2Fimage.png?alt=media\&token=d6aa58f9-5a7e-4ccc-aa64-a237b655af11)

After Clicking on the **Link** button  you will be redirected to a page as shown below and then again click on login button as per the instructions on the page.

![](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfHr2Wk9ohN_vRYxzNb%2F-MfJ0wYp8xz-w2Q8cQ7l%2Fimage.png?alt=media\&token=9caa3151-1314-4893-8268-2460336ee5a2)

After clicking on the login button as shown above you will be redirected to a page where you will have to enter your login credentials those credentials should match the ones which you entered while registering yourself.

![Click on Sign In after filling the detail](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2Fz4ZgbpRdRPK3SKbqNbD6%2Fimage.png?alt=media\&token=57a33889-6d49-4324-8325-4d2a04341333)

After you Sign In  successfully you will be redirected to the dashboard.

![](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FbLqpzdGXVOvedOYzX2k5%2Fimage.png?alt=media\&token=2cf49d34-aa4e-45bb-adb5-d98662e089d8)


# Sign In

Create free account here

Click on this link <https://app.zbl-aws.zeblok.com/> to Sign In  with your **Zeblok** Computational account.

![Sign In page ](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FTe4STSs1y48FUyilRcSp%2Fimage.png?alt=media\&token=ba1c41b6-fd8e-496d-b8ed-48f23940aae8)

Enter the required details and you will be redirected to the **Zeblok** dashboard page.


# Spawn Ai-WorkStation

Step By Step Guide for Spawning an Ai-WorkStation

### Overview&#x20;

Once you logged into the Zeblok Computational Application, you will get an option for **Spawn Ai-Workstation** as shown in the screenshot below.

![Figure 1: Dashboard](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FjvPks8MgPZfYT2MYvmlg%2Fimage.png?alt=media\&token=09d0a8c2-c0b2-43b3-a3c0-5c26c4311064)

#### **Step 1**

Click on "Spawn Ai-Workstation", you will be redirected to a page as shown below.

![Figure 2: Spawn Ai-WorkStation](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FWyWf5i1anKdvloHJ3HA4%2Fimage.png?alt=media\&token=3b6c9049-f7d3-4f78-bb2d-7fd1bae1af3e)

#### &#x20;**Step 2**

Select the Notebook which you want to use, whether it can be an Ai-WorkStations, Intelligence Marketplace, or Ai-HPC-WorkStations as shown below.

![Figure 3: 3 Types of Notebooks](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FWyWf5i1anKdvloHJ3HA4%2Fimage.png?alt=media\&token=3b6c9049-f7d3-4f78-bb2d-7fd1bae1af3e)

#### **Step 3**

Depending on whether you are a beta user or not, all the plans will be unlocked for you and ready to use if you are a Beta User. Currently, everyone is given **BETA Access**.

#### **Step 4 (Beta User)**

Select the Plan which fulfills your requirements in terms of resources provided by clicking on the **Select Plan** button.&#x20;

![Figure 4: Select Plan for Beta User](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F3rn8tINRI32y9JHteFZX%2Fimage.png?alt=media\&token=5a173163-6682-4ff7-9c4b-6093e3cff2a0)

#### Step 5

Select the namespace in which you would like to deploy your Ai-WorkStation.

{% hint style="info" %}
**Note:** You have to be a member of a namespace to get the option to select a namespace.

Contact your OrgAdmin to add you in a namespace or, if you are an OrgAdmin, you can go to the namespace section and add the desired person as a member to a namespace.
{% endhint %}

![Figure 5: Select a Namespace](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FW7qva6JWULSQqR8h7kPn%2Fimage.png?alt=media\&token=8a2a3040-5127-4128-9c25-588411f42e7d)

#### Step 6

Choose whether you want to mount your S3 bucket from our Ai-DataLake or not.

If yes, then select your bucketname from the dropdown.

![Fig. 6: Mount your S3 Bucket](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FV8vfDgesrzfFMiZywtLa%2Fimage.png?alt=media\&token=874a833a-4bd4-4b58-83fc-a4e6aa7041ef)

#### **Step 7**

Enter the Notebook Name and finally spawn it as shown below. After successful creation, you will get your Notebook.

![Fig. 7: Name of Ai-WorkStation](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2Fhmd2Ct5DI6qfXbGVwexT%2Fimage.png?alt=media\&token=68296df0-ec18-49f8-836c-8a4d7d074be5)


# Spawn MicroService

Step By Step Guide for Spawning a MicroService

### Overview&#x20;

Once you logged into the Zeblok Computational Application, you will get an option for **Spawn MicroService** as shown in the screenshot below.

![Figure 1: Dashboard](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FjvPks8MgPZfYT2MYvmlg%2Fimage.png?alt=media\&token=09d0a8c2-c0b2-43b3-a3c0-5c26c4311064)

#### **Step 1**

Click on "Spawn MicroService", you will be redirected to a page as shown below.

![Figure 2: Spawn MicroService](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F5QyHjCeZaAAKF61MUQdi%2Fimage.png?alt=media\&token=1cdf8245-4aab-4b19-8be6-60fb234ed7ac)

#### &#x20;**Step 2**

Select the MicroService which you want to use, as shown below.

![Figure 3: MicroServices](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F5QyHjCeZaAAKF61MUQdi%2Fimage.png?alt=media\&token=1cdf8245-4aab-4b19-8be6-60fb234ed7ac)

#### **Step 3**

Select the datacenter where you want to deploy it.

![Figure 4: Select DataCenter](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2Fh0IuyQK844tRH5SN39GI%2Fimage.png?alt=media\&token=fa8fde50-7ead-40c0-b2af-f48c2250b65a)

#### **Step 4**&#x20;

If you selected an Edge Datacenter in the previous step, you have an additional step where you are given an option to choose whether you want your deployment to be created on the **HUB** or any **SATELLITE** Node.

![Figure 5: Select HUB or SATELLITE NODE](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FE5q4tF1ozqKBhDGkbz3j%2Fimage.png?alt=media\&token=708b4eda-8390-4b74-a229-4618381696af)

Select a Plan for your deployment. This step is common for both kinds of datacenters (EDGE and ENTERPRISE).

![Figure 6: Select Plan](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F3h0zkG8winPcMVLLSaNT%2Fimage.png?alt=media\&token=3454a80c-b2ea-43e4-bfc5-398b99ec0a38)

#### Step 5

Select the namespace in which you would like to deploy your Ai-WorkStation.

{% hint style="info" %}
**Note:** You have to be a member of a namespace to get the option to select a namespace.

Contact your OrgAdmin to add you in a namespace or, if you are an OrgAdmin, you can go to the namespace section and add the desired person as a member to a namespace.
{% endhint %}

![Figure 7: Select a Namespace](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F2pFULj35sk0Jd8wuTLFW%2Fimage.png?alt=media\&token=e39ac32b-b703-42ff-9a5f-3c0af602f9a4)

#### Step 6

This is a step given to you for configuring your microservice as you like.

**Ports:** The list of ports to be opened.

**Environment Variables:** Environment variables to be passed to the microservice container while starting.

**Arguments:** Arguments to be passed for the command parameter.

**Command:** Command to be passed to the microservice container.

![Figure 8: Configure your MicroService](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FEXWSfVHsjJmwhhbqH4tS%2Fimage.png?alt=media\&token=34025451-4a12-4c59-bec6-7bd524239081)

#### **Step 7**

Enter the MicroService Name and finally spawn it as shown below. After successful creation, you will be redirected to the Ai-WorkSpace and with your Spawned MicroService.

![Figure 9: Name your MicroService](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FENoRp05tM3cTXviMxheD%2Fimage.png?alt=media\&token=91b36a90-95d0-43d1-b8e0-959c16eb723a)


# FAQS


# Introduction

Introduction to Ai-APIᵀᴹ

### Overview

Ai-API™ makes moving trained ML models to production easy:

* Package models trained with ML framework and then containerize the model server for production deployment&#x20;
* Deploy anywhere for online API serving endpoints or offline batch inference jobs
* High-Performance API model server with adaptive micro-batching support
* Ai-API™ server is able to handle high-volume without crashing, supports multi-model inference, API server Dockerization, Built-in Prometheus metric endpoint, Swagger/Open API endpoint for API Client library generation, serverless endpoint deployment etc.
* Central hub for managing models and deployment process via web UI and APIs
* Supports various ML frameworks including:

Scikit-Learn, PyTorch, TensorFlow 2.0, Keras, FastAI v1 & v2, XGBoost, H2O, ONNX, Gluon and more

* Supports API input data types including:&#x20;

DataframeInput, JsonInput, TfTensorflowInput, ImageInput, FileInput, MultifileInput, StringInput, AnnotatedImageInput and more

* Supports API output Adapters including:&#x20;

BaseOutputAdapter, DefaultOutput, DataframeOutput, TfTensorOutput and JsonOutput

### Easy steps to Ai-AP&#x49;**™** Deployment

1. [Select your notebook](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/notebooks)
2. [Build Model](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/build-models)
3. [Deploy](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/deploy)

###


# Notebooks

Ai-APIᵀᴹ Engine: Notebooks

### Selecting a Notebook

Here, as an example, we are selecting the BentoML Notebook. You can find it using the search field on the Spawn Ai-WorkStation Page.

{% hint style="info" %}
**Note:**

The full walkthrough of spawning an Ai-WorkStation has been given at our [Spawn WorkStation Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation) for your convenience.
{% endhint %}

![Figure 1: BentoML Notebook](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F2rQwsgD6qaGSGZLgXdjh%2Fimage.png?alt=media\&token=e0bbeb9e-2447-452b-9b35-3cdb60f07fe8)

Taking BentoML as the Notebook and following all the steps from the Spawn Workstation Guide will give you an Ai-WorkStation ready to open.

{% hint style="info" %}
**Note:**

The final result of this example will get us a notebook which can identify the breed of an animal upon uploading the image of an animal.
{% endhint %}

Next Step is to start and open the notebook and run all cells to get a newly trained model.

![Figure 2: Run all Cells](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfWJkAY6--OCBhIWwMo%2F-MfWL7bZ56GLDV7o7FtO%2Fimage.png?alt=media\&token=5d1c2dc2-3c93-4987-a921-2bd31f738b21)

![Figure 3: Name of newly Trained Model](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfWJkAY6--OCBhIWwMo%2F-MfWLbRCL4dkT67aBOM5%2Fimage.png?alt=media\&token=b7f6fee3-c62f-41f9-9c7d-e5d768ce2589)


# Build Models

Ai-APIᵀᴹ Engine: Build Models

### Building Models Guide

Before starting to read this guide, it is recommended for you to read the[ Notebook Section](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/notebooks) of the Ai-API Concept.

After creating a newly trained model, comes the building stage.

For building process, the steps are as following:

* Open the integrated terminal that comes along with the notebook.

![Figure 1: Click on New Launcher](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfWJkAY6--OCBhIWwMo%2F-MfWMGJAB325Cp64dc16%2Fimage.png?alt=media\&token=8b581b45-fc37-4e31-97f4-f6210fe1ce50)

![Figure 2: Integrated Terminal](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfWJkAY6--OCBhIWwMo%2F-MfWMZgjoHm-MK3k6l_r%2Fimage.png?alt=media\&token=18e3014b-a872-4846-80fa-3864b45701bd)

* Update the Cli ( Command Line Interface) for smooth process running.

```
npm i -g zbl-cli
```

![Figure 3: CLI Update](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfWJkAY6--OCBhIWwMo%2F-MfWRjMuXXpNpBhkSEpF%2Fimage.png?alt=media\&token=79762d16-a058-4342-9a30-992e9579cca3)

* Configure your zeblok cli

```
zeblok configure
```

![Figure: Zeblok Configure](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MgQZg7pk_bmiC79qcok%2F-MgQa2o3D-4_8bAj5I-9%2Fimage.png?alt=media\&token=d01e3a1f-4395-4162-b4f6-7691aae1b7d9)

* Run the command **zeblok auth** and enter your username and password&#x20;

```
zeblok auth
```

![Figure 4: Authentication Command](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfWJkAY6--OCBhIWwMo%2F-MfWN3xODmMbP72Yqyjb%2Fimage.png?alt=media\&token=324626a5-5347-4246-9218-ddb29749ee0d)

* After successful authentication, run the command **zeblok runtime** which fetch the latest created by you and give a list of the models from which you can select the model you would like to deploy.

```
zeblok runtime
```

* Select the model and hit enter. The terminal will package your model and upload it to the database. This might take a minute or two.

![Figure 5: Model Selection (Runtime Command)](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfWJkAY6--OCBhIWwMo%2F-MfWPdAiplA8X05Olsf-%2Fimage.png?alt=media\&token=63376050-3bac-4e8b-90eb-f3f09e9723f2)


# Deploy

Ai-APIᵀᴹ Engine: Deploy

### Deploying Models Guide

Before starting to read this guide, it is recommended for you to read the[ ](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/notebooks)[Build Models Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/build-models) of the Ai-APIᵀᴹ Concept.

After building a newly trained model, comes the deploying stage.

Now this is the part where our Ai-APIᵀᴹ Engine comes into play. The sidebar at the left side of your screen has a menu button of Ai-APIᵀᴹ which will lead you to our Ai-APIᵀᴹ Engine.

![Figure 1: Ai - Apiᵀᴹ Engine](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F5CEYQXvYRDUUTg8aLwRU%2Fimage.png?alt=media\&token=2a277e72-e724-4cce-8699-4253fc39d0fb)

{% hint style="info" %}
**Note:**

The Ai-APIᵀᴹ Engine, on clicking, shows all the previous deployments you have done, or your organization has done (if you are an Organization Admin) after selecting a specific namespace of the deployments.
{% endhint %}

### For deploying process, the steps are as following:

* Click on Create Ai-APIᵀᴹ and then select the model. Here we are selecting the model which we just created in the previous Guide.

![Figure 2: Create Ai-Apiᵀᴹ](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F3Dc7UNh0RRjvx4XPzFZz%2Fimage.png?alt=media\&token=49e92291-18a2-4f23-ae87-069e5a6c278a)

![Figure 3: Select Trained Model](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F1u3q8oEOTLetA2ImjN8Y%2Fimage.png?alt=media\&token=0937874d-7914-48d4-bcb2-b30c2dc352d5)

* Then comes the selection of namespace (only if you are a member of one).

![Figure 4: Namespace Selection](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FLdZ7WaM5ZYAuQbGZ2Aq8%2Fimage.png?alt=media\&token=7b1cf6c3-9e47-4195-9ccb-ad631eec9016)

* Third step is to select the location where you want to deploy it.

![Figure 5: Select DataCenter](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F9JArJh4wN6X9DYa0f64z%2Fimage.png?alt=media\&token=7382d3e6-5e18-4c95-8a5d-f987595ed9c6)

* If you selected an Edge Datacenter in the previous step, you have an additional step where you are given an option to choose whether you want your deployment to be created on the **HUB** or any **SATELLITE** Node.&#x20;

![Select HUB or SATELLITE NODE](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F91xIq8C4D8S1AwaeH5vv%2Fimage.png?alt=media\&token=a3a53eed-ca2a-4765-80ef-2dc73976d90c)

* Name your Deployment and click on Create.

![Figure 6: Name of Deployment](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FydM3Nnhbu6if9e1H3n2b%2Fimage.png?alt=media\&token=7388d103-d8ab-4e21-9115-b6ad0a78ceb0)

You will be redirected to our Ai-APIᵀᴹ Engine while the deployment is being done in the background. On successful deployment, the status of the deployment will change to **DEPLOYED.**&#x20;

{% hint style="info" %}
**Note:** On successful deployment, when the status is deployed, you are now given an option to monitor various performance metrics as highlighted in the images below.
{% endhint %}

![Figure 7: Deployment Successful](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FMzGjVAnqRXd97Dgingfc%2Fimage.png?alt=media\&token=60fb53db-a378-4ec8-8792-0cf7cb628cce)

![Performance Monitoring](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F4tvA5ca80cnEt3P5yEtR%2Fimage.png?alt=media\&token=9f1b9824-3003-47dd-a8db-723ef6aae849)


# DataLake

Enabling Accelerated Data Management, Data Engineering and AI Pipelines

### Overview

A data lake is a centralized repository that allows you to store all your structured and unstructured data at any scale. Zeblok Ai-Data Lake is a high-performance data-store that allows you to import, filter, and instantly analyze objects. Our solution is designed for performance, scales up with your data, and can provide industry-grade SSL security and data-redundancy for high availability of data at SSD speeds.

### Seamless accessibility from almost anywhere

Zeblok Ai-Data Lake handles the tasks of data pipe-lining, analysis, and propagation so that you can focus on what matters most. Whether you are ingesting images, video data files coming from IoT sensors at Edge locations through 4G/5G low latency network or uploading large CSV files, Zeblok Ai-Data Lake has you covered, with unprecedented data acceptance, performance and compatibility.

Easily automate your imports, with large files using various methods such as: Browser-based portal, Zeblok Magic Commands, S3 REST API, Data Lake drag-and-drop native Windows App, and HTTP importing.

&#x20;

![](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MedbRycXUwQNSQpAIjA%2F-MedgZ_XS_wODxcJ85EN%2Fimage.png?alt=media\&token=5a259cbc-e946-45d9-814a-6d1dfc7c7454)

### Data Browser Portal:

Zeblok Ai-Data Lake provides secure high-availability of your files and objects across a cluster of servers. Authorized users can access and manage all their data in one place through the convenience of the Data Browser Portal. The Browser Portal can securely allow a user to set permissions and upload/download/edit data of various file types and sizes. Users can see a map of files in their bucket without touching a command line.

![](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MedbRycXUwQNSQpAIjA%2F-Medggtaeaot_NGGq0bj%2Fimage.png?alt=media\&token=bdec26a4-9fcd-48a5-ad14-5c39fb12f5e6)

### Zeblok Magic Commands:

Zeblok's Magic Commands are ubiquitously available in every Zeblok notebook instance to allow users easy access to a reliable object storage solution. With Magic Commands, users have an array of options that allows for quick and easy way to add blazing fast storage to virtually any network. Magic Commands are intuitive, especially for those familiar with the common  Linux/Unix file system. The command line offers users the ability to create new files, delete old ones, create new folders, share access, and more.

![](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MedbRycXUwQNSQpAIjA%2F-MedgpexY-e3U4UnaGbJ%2Fimage.png?alt=media\&token=79b8cd95-6045-4425-97f3-e1c05605fdd9)

### REST API:

Inspired by the S3 protocol originally from AWS, Zeblok's Ai-Data Lake provides a secure endpoint that enables users to programmatically upload and manage files using a REST API. The generic S3 REST API offers a unified interface for interacting with any object and provides high-performance uploads and file transfers that can be scheduled or automated between Zeblok notebook instances or external hosts (such as via cron jobs).

![](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MedbRycXUwQNSQpAIjA%2F-Medh3mrEanKqoUxz5xj%2Fimage.png?alt=media\&token=64d2089f-e714-4506-ac9b-9d99b63c24c3)

### HTTP Source:

Zeblok Ai-Data Lake also allows users to upload and download files from various HTTP sources without re-downloading files on the local machine. This space-saving method enables users to skip steps between upload and download cycles as desired.

### Use the Ai-Data Lake within the Ai-WorkStation Notebook:

Access your data files residing in the Ai-Data Lake within the Ai-WorkStation notebook using BlazingSQL engine that runs on GPUs

### Blazingly fast queries with big data\*:

Run big data analytics across Zeblok Ai-Data Lake using our query-in-place GPU enhanced services. Perform blazing fast queries (up to 8x faster\*) with SQL expressions and use our Zeblok AI algorithms to analyze data that is stored across your private Ai-Data Lake account across various notebooks. Export queries back to Ai-Data Lake or generate customization visual reports with ease.​&#x20;

### Data Lake Security:

The Zeblok Ai-Data Lake platform is designed to be scalable and easy to use with a granular access control system where each user only has access to their own files. The platform features implementations for data encryption both in-transit and at-rest. With recommended SSL certificates installed, the platform offers standard bank-level encryption which is 256-bit AES, the standard for advanced cryptography. The encryption standards available in the Data Lake platform protects your data from being intercepted by third parties. Furthermore, the REST API endpoints are hardened to only operate on pre-provisioned key/secret pairs.


# Tutorials

Ai- DataLake Tutorials and Commands

### Overview

Zeblok Datalake is a high-performance data-store, compatible with the S3 protocol, intended for secure high speed data transfer. As an object store, Zeblok Datalake allows users to read and write large amounts of unstructured data such as photos, videos, log files, spreadsheets, CSV files, etc. Datalake is cloud native and supports GPU-optimized queries through the addition of BlazingDB.

With a robust and simple online interface, API CRUD access, in-built Zeblok CLI magic commands, and Python integrations, users can instantly run complex AI related queries for a variety of datasets, visualize the results, and share/revoke reports with clients.

### Zeblok CLI

#### Get the Latest Version Zeblok CLI using Below Command

{% tabs %}
{% tab title="Code" %}

```
npm i -g  zbl-cli
```

{% endtab %}

{% tab title="Output" %}

```
ERROR! Session/line number was not unique in database. History logging moved to new session 6
/opt/conda/bin/zeblok -> /opt/conda/lib/node_modules/zbl-cli/index.jserial remove 10yan/.npm/_lock
+ zbl-cli@1.1.9
updated 1 package in 4.359s
```

{% endtab %}
{% endtabs %}

**Configure the Zeblok CLI**

![Figure: CLI Configure](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MkalQi9QJZZK0RYN2SQ%2F-Mkanv76DhZhBkwk_srU%2Fimage.png?alt=media\&token=84bb43b8-fc52-4fb6-b65b-c2afbe555f1d)

#### Set DatalakeUrl

```
zeblok setUrl http://18.189.16.253:9000
```

#### Login using Zeblok CLI

To login using Zeblok CLI open terminal from Jupyterlab environment and type the below command.

{% hint style="info" %}
**Note:**

SecretKey and Username are avaialable on Zeblok Computational Dashboard "Manage your Zeblok Accounts" Page
{% endhint %}

{% tabs %}
{% tab title="Code" %}

```
zeblok login <username> <secret key>
```

{% endtab %}

{% tab title="Output" %}

```
  _____         _       _           _        ____            _             _           _           
 |__  /   ___  | |__   | |   ___   | | __   |  _ \    __ _  | |_    __ _  | |   __ _  | | __   ___ 
   / /   / _ \ | '_ \  | |  / _ \  | |/ /   | | | |  / _` | | __|  / _` | | |  / _` | | |/ /  / _ \
  / /_  |  __/ | |_) | | | | (_) | |   <    | |_| | | (_| | | |_  | (_| | | | | (_| | |   <  |  __/
 /____|  \___| |_.__/  |_|  \___/  |_|\_\   |____/   \__,_|  \__|  \__,_| |_|  \__,_| |_|\_\  \___|


Added `zb` successfully.
```

{% endtab %}
{% endtabs %}

#### List all the Files and Directory on Datalake

{% tabs %}
{% tab title="Code" %}

```
zbl tree -f zb/datalake/<username>/
```

{% endtab %}

{% tab title="Output" %}

```
zb/datalake/akash/
├─ FL_insurance_sample.csv
├─ ZeblokReadme.ipynb
├─ algebra.log
├─ main.go
├─ sales.csv
├─ sample_taxi.csv
└─ docs
   ├─ MAINTAINERS.md
   ├─ minio-admin-complete-guide.md
   ├─ minio-client-complete-guide.md
   ├─ minio-client-configuration-files.md
   └─ zh_CN
      ├─ CONTRIBUTING.md
      ├─ minio-client-complete-guide.md
      └─ minio-client-configuration-files.md
```

{% endtab %}
{% endtabs %}

#### Copy file from DataLake to local Notebook Directory

```
zbl cp zb/datalake/<username>/<filepathOnDatalake> <filepathOnNotebookStorage>
```

Example is given below:

{% tabs %}
{% tab title="Code" %}

```
zbl cp zb/datalake/akash/main.go main.go
```

{% endtab %}

{% tab title="Output" %}

```
...h/main.go:  979 B / 979 B ┃▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓┃ 29.49 KiB/s 0s
```

{% endtab %}
{% endtabs %}

#### Copy file from Local Notebook Directory to Datalake

```
zbl cp <localfilePath> zb/datalake/<username>/<datalakeFilePath>
```

Example:

{% tabs %}
{% tab title="Code" %}

```
zbl cp ZeblokReadme.ipynb zb/datalake/akash/
```

{% endtab %}

{% tab title="Output" %}

```
...dme.ipynb:  54.33 KiB / 54.33 KiB ┃▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓┃ 1.29 MiB/s 0s
```

{% endtab %}
{% endtabs %}


# Monitoring

Centralized Orchestration Manager

### Overview

Ai-MicroCloud™ Manager is the centralized management utility for Ai-MicroCloud™ and is used to manage and Orchestrate all dependent components for Ai-WorkStation, Ai-Data Lake, Intelligence Marketplace and Ai-API™ engine.

The Ai-MicroCloud™ Manager enables the Enterprise Administrator to define role-based access control, infrastructure plans (vCPUs, GPUs, memory, storage), define Namespaces and add accessible data centers, and provides metering information for resource utilization for billing or charge back purposes.

### System Monitoring:

#### Dashboard:

View notebooks and analytics, including a graph of notebooks previously spawned and usage statistics, followed by all the notebooks available within the organization.

![Figure 1: Dashboard](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2Fvr59afIGAmJUywUSqA0b%2Fimage.png?alt=media\&token=d4c6c9f0-20a6-41ad-8bdb-f6c7c92f39c0)

By clicking on **View Analytics Button,** you will be redirected to the activities monitoring page, where if you are an Organisation Admin, you can view the activities and statistics for resource usage and everything related of all Organisation users.

![Figure 2: Activities Monitoring Page](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-Mfqas4wgeL6s5X8Kjiv%2F-MfqcgFJ50M7NesFpPnw%2Fimage.png?alt=media\&token=b1844312-4c90-4cd3-85f2-8e3f6a7fce8c)

### <br>


# Intelligence Marketplace

Carefully Selected ∙ Rigorously Tested ∙ Enterprise-Ready Proven, original algorithms – easy to read, use and share

### Overview

Zeblok’s Intelligence Marketplace provides easy access to a growing library of proven, original third-party AI algorithms. Quality is ensured by our curation process, including closed loop validation, providing algorithm creators with a means of commercialization not previously available. We ensure that algorithms are easy to read, easy to use and easy to share. These include:

{% file src="/files/-MedfSC1IZsWkFTMW-eX" %}
Intelligence Marketplace
{% endfile %}

### **Ai-Rover™ – Explainable AI Notebook**

#### **Multi-variate, high dimensional data comprehension**

AI systems tend to operate in the darkness of black boxes. Input data is transformed into decisions without much human-readable justification. The journey from data to insights requires a crucial data comprehension stage, so the direction of an AI/ML model is fully explainable. Omitting this stage may produce a result that is not actionable, causing the AI project to dead-end.

Ai-Rover™ is the full implementation of an explainable AI algorithm on a virtualized notebook, in concert with Zeblok's GPU-powered data lake, Edge connectivity and other components.  Ai-Rover™ discovers and visually explains patterns in complex datasets as well as the causal relationships underlying those patterns, supporting data analysts in the construction of trust-able decision-making AI models. Domain agnostic Ai-Rover™ is particularly useful for large, multi-variate, high dimensional data analysis. Ai-Rover™ enables the crucial data comprehension phase to properly target the direction of an AI project.

Say goodbye to tedious data exploration and instead gain quick access to the hidden information in your data with a simple visual interface that enables users to intuitively derive subpopulations of data attributes, leading to better predictive insights.

[Learn More...](https://854a0df5-7a21-4391-b1e4-c279d3cc5b86.filesusr.com/ugd/dc718d_dc7309f63872419395abe25463fce115.pdf)                                                                                                       [Use Cases](https://www.computational.zeblok.com/biotech-and-pharma)            &#x20;

### Ai-Rover™ Notebook For Time Series Data

#### Time series data forecasting & anomaly detection

Ai-Rover™ Notebook For Time Series Data is a value framework to automate predictive model building that creates human-readable models from historical time series data.

These models provide users with high-quality explainable forecasts and anomaly detections, creating business value in use cases across industries, containerized for easy incorporation into your AI/ML model.

The framework is built on a field of mathematics called information geometry, an interdisciplinary field that uses differential geometry techniques to study probability theory and statistics. It enables model building which includes business focus, aggregates, and key performance indicators (KPIs). It can help you identify the value of the predictive analytics business use cases that you want to implement.

Typical use cases and business applications:

* Demand/capacity prediction
* Predictive asset management
* Fraud/anomaly detection
* Marketing/social analysis
* Pricing optimization

[Learn more](https://www.computational.zeblok.com/airoverfortimeseries).

### Ai Video-Analytics-as-a-Service

#### Near real-time Ai Video-Analytics

A robust framework that enables development and implementation of AI-powered video analytics solutions. It accommodates video feeds in a variety of formats & resolutions, ranging from a few cameras to thousands of cameras; best in class annotation tools to generate unlimited number of datasets with precise guidelines and complex ontologies to significantly reduce labeling time and an inference engine to integrate your production output into your enterprise application from Core to Edge using RESTful API.

Offer Video-Surveillance-as-a-Service by developing bespoke AI models to a variety of clients responsible for monitoring facilities, such as schools, highways and public spaces to identify vandalism and other suspicious behavior, monitor and analyze traffic patterns, identify traffic violations to providing Quality audits for manufacturing processes in automobile industries.

Enterprise applications include:&#x20;

* Intrusion Detection
* Suspicious Activity
* Traffic & Parking Management
* Smoke & Fire Detection
* Crowd Counting
* Vehicle Identification
* Non-Invasive Body Temperature Monitoring
* Dwell Time
* Safety gear monitoring – Hardhats, safety goggles, masks

[Learn more](https://www.computational.zeblok.com/videoanalytics).  [Solution Brief](https://854a0df5-7a21-4391-b1e4-c279d3cc5b86.filesusr.com/ugd/dc718d_cc067581312d4bfb9afb2c666e4ce12c.pdf).

### Quantum Entropy-as-a-Service

#### Quantum entropy for a connected world

Zeblok provides quantum-safe security via container, with both high throughout and high entropy density, using QNu's Qosmos™ quantum random number generator , which uses device-generated random numbers, wherein the randomness is guaranteed by the laws of quantum mechanics. Zeblok's Quantum Entropy-as-a-Service (QEaaS) provides truly random numbers, delivered via container on Ai-MicroCloud™ to the network security layer, operating systems, embedded systems or at the network edge, providing a seamless upgrade from computational security posture to information provable security.

The high throughput, low cost of upgradation and ease of integration makes this a very cost-effective and simple-to-deploy solution over companies' existing infrastructure.

The architecture is scalable, provides load balancing, and has active failover.

[Learn more](https://www.computational.zeblok.com/quantumsecurity).   [Solution Brief](https://854a0df5-7a21-4391-b1e4-c279d3cc5b86.filesusr.com/ugd/dc718d_522ca639890e431e8fe444f426c71253.pdf).

​


# Manage Account

Account Security Mechanisms

This article will guide you through our [Resetting Password Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/more/manage-account/forgotpassword) and [2 Factor Authentication Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/more/manage-account/2-factor-auth).

{% hint style="info" %}
**Note:**

Enabling 2 Factor Authentication is an optional security measure you can avail, however we recommend you to enable this for better security of your account.
{% endhint %}


# Forgot Password

Guide for resetting password

If you are not able to login to your account, because you forgot your password, don't worry as this guide will take you through the process of resetting your password step by step.

![Figure 1: Forgot Password](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FoZ4KKG38KBOzzXv6nsb7%2Fimage.png?alt=media\&token=81647c04-954a-4a2d-9b99-9180e9506486)

1. Click on the Forgot Password link above the Sign In Button, and you will be redirected to our [Forgot Password Page](https://app.zbl-aws.zeblok.com/forgotpassword).

![Figure 2: Enter Valid Email Id](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FHwwHurvxupbzL3pTidtU%2Fimage.png?alt=media\&token=4dbbf21b-3e3f-41bf-89af-6b275406930e)

You will then receive an **Email** on your **Email-id** you entered in the forgot password link as shown in above image.

{% hint style="info" %}
**Note:**

To receive a password reset link in your registered email id, you must have your account registered first with our Zeblok Computational Platform first.
{% endhint %}

![Figure 3: Email sent to your Email-id](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FWsNNiiiyq0HDxzkbKP1Y%2Fimage.png?alt=media\&token=8e28aa0d-bbe0-4bc4-a5e5-1b890f596367)

2\. Click on the Link option sent in your email and you will be redirected to a page and to enter New Password and after that click on the **Reset Password** button.

![Figure 4: RESET PASSWORD](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F0l2TuB2UIm5Iu8qSsadu%2Fimage.png?alt=media\&token=9abda470-5e7c-4859-bc5b-e15473557e30)

After that you will see this notification **Password updated successfully please login to continue.**

Then You can Login with the New Passwor&#x64;**.**


# 2 Factor Authentication

2 Factor Authentication Guide

### Toggle 2 Factor Authentication

Enter the login credentials in the [Sign In](https://app.zbl-aws.zeblok.com/), page then you will be redirected to dashboard page.

![Figure 1: Dashboard Page](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F1vk0IeNzMHyd3qcMnEZe%2Fimage.png?alt=media\&token=af5b367e-5c97-4ee3-85ee-d71b46863922)

At the rightmost top-corne&#x72;***,*** click on three dots and you will see a dropdown menu then at the bottom click on ***2-fa and your 2 factor Authentication will be enabled.***

![Figure 2: Toggle 2 Factor Authentication](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FIlk71zsifARJSnXrragX%2Fimage.png?alt=media\&token=7fbbe206-4fb8-49db-b716-c682b4b9a541)

{% hint style="info" %}
**Note:**

Enabling 2 Factor Authentication will have an effect on the sign in process starting the next time anyone tries to sign in to your account.
{% endhint %}

### Sign In using 2 Factor Authentication

#### Step 1:

Enter your credentials and click on sign in button.

![Figure 3: Sign In](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2Fli0w81hU3oCk2JITIfAG%2Fimage.png?alt=media\&token=92298dc4-5e6a-4c3d-b2b3-6e3c3dc8bbc9)

#### Step 2:

As you can see, an OTP will be sent to your registered E Mail Id which you will have to enter to successfully login to your account.

![Figure 4: 2 Factor OTP](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FOneSrUpHKPxaDBmag2NI%2Fimage.png?alt=media\&token=ab64066d-09b7-4c05-a03a-87e374818371)

![Figure 5: OTP Email](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FHv1OzfX4rt7KJkGqTVps%2Fimage.png?alt=media\&token=381c6491-db2f-40e0-a3c7-d0d5ae86cea5)

{% hint style="info" %}
**Note:**

As mentioned above in the images, the validity of OTP is only 5 minutes. You will have only 4 attempts to enter a valid OTP, after which your account will be banned for signing in and you will have to contact the Zeblok Administrator for unblocking your account.
{% endhint %}


# IAM

IDENTITY ACCESS MANAGEMENT

### Overview

IAM is a user entity which we create in **Zeblok Computational Platform** to represent a person that uses it with limited access to resources.

![Figure 1: IAM (Identity Access Management)](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-legacy-files/o/assets%2F-MecgpHyRD3Y801omxL9%2F-MfmmWYc1aOeU23dvBAH%2F-Mfmp_1qWzqWS0EBilV3%2Fimage.png?alt=media\&token=fae04101-ae26-4599-ba80-3167921c76f7)

As you can see, we have 4 sections for defining user permissions and recourse management in the IAM page.

* [Roles](https://computationaldocs.zeblok.com/zeblok-computational-1/more/iam/roles)
* [Usergroups](https://computationaldocs.zeblok.com/zeblok-computational-1/more/iam/usergroup)
* [Menu](https://computationaldocs.zeblok.com/zeblok-computational-1/more/iam/menu)
* [Resources](https://computationaldocs.zeblok.com/zeblok-computational-1/more/iam/resources)

{% hint style="info" %}
**Note:**

Only the user who has an admin access, gets access to IAM Tab in the Sidebar.
{% endhint %}


# Roles

IAM: Roles

### Overview

Every user has their own role in Zeblok Computational Platform which is assigned while the user signs up in the platform.

Here are few pre-defined roles available in the platform:

**Superadmin**: The Superadmin has all the rights. An Admin can do anything and everything on the platform such as creating more Organisation Admins, inviting more users and also removing them, changing the permissions for a certain role in the platform.

**User**: A user role is assigned when a user signs up using individual sign up page.&#x20;

{% hint style="info" %}
**Note:**

To know more about the sign up process for the user role and access, follow our [Create An Account Guide for Individual User](https://computationaldocs.zeblok.com/zeblok-computational-1/create-an-account/individual-user).
{% endhint %}

**Organisation Admin**: An organisation admin role is assigned when a user signs up using Enterprise organisation sign up page. The organisation admin has the rights to view all the activities of all the members in the organisation who have signed up using the invite sent by organisation admin.

**Organisation User**: An organisation user role is assigned when a user signs up using the invite mail sent to him/ her by the organisation admin who has already signed up in the platform.

{% hint style="info" %}
**Note:**

To know more about the sign up process for the organisation admin/ user role and access, follow our [Create An Account Guide for Enterprise User](https://computationaldocs.zeblok.com/zeblok-computational-1/create-an-account/enterprise-user).
{% endhint %}

**Business Partner**: A business partner role is assigned when a user signs up using business partner sign up page.

{% hint style="info" %}
**Note:**

To know more about the sign up process for the business partner role and access, follow our [Create An Account Guide for Business User](https://computationaldocs.zeblok.com/zeblok-computational-1/create-an-account/business-user).
{% endhint %}


# Usergroup

IAM: USERGROUP

### Overview

A usergroup is a set of users who have the same permissions as the policies/ permissions are assigned to a usergroup in which the users get assigned.

When the [resources](https://computationaldocs.zeblok.com/zeblok-computational-1/more/iam/resources) are created, they are given access to certain usergroups in the platform and all the members of these usergroups get access to the resources collectively.


# Menu

IAM: MENU

### Overview

The menu tab gives options for the superadmin to decide which kind of resources and menu will be available to a certain role in the platform.

It lies on the Admin whether a certain tab will appear in the side bar menu for a certain role/ user or not.


# Resources

IAM: RESOURCES

### Overview

Every accessible entity in the platform (Example: Plans, Notebooks, etc.) is recognised as a resource.&#x20;


# Admin Guide

Admin Manual for mastering Zeblok Ai-MicroCloud


# Menu

The first view of the SideNav Menu after logging in via the Admin account gives the feeling of a wide range of options and authority over the Ai-MiroCloud.

This guide is made for you to understand all the features and control that an Admin has, and also how to own the Ai-MircoCloud.

![Fig 1: Zeblok Ai-MicroCloud Landing Page](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FlIWBOva20oP2spuOLrOu%2Fimage.png?alt=media\&token=3e94c499-1855-42c4-b8e8-f26d68edbd84)

[Dashboard](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/dashboard)

[Workstations](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/workstations)

[IAM](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/iam-identity-access-management)

[Organizations](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/organizations)

[Plans](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/plans)

[Namespace](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/namespaces)

[Data Center](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/datacenters)

[MicroServices](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/microservices)

[Ai-API Engine](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/introduction)

You can click on any of the names above to know more in details about the specific section.

Also, you can refer to IAM page under Mode Section of this documentation to get a better idea about all the roles and their accessibility and limitations.


# Dashboard

An Intelligent visual view of your data

The OrgAdmin Dashboard only shows the metrics generated by their organization whereas SuperAdmin Dashboard will show you the metrics generated by all organization in one place alongwith an option to see only the metrics generated by a specific organization.

To see a glimpse of the Dashboard, you can visit the **Monitoring page** under Data and Metrics Section of this documentation.


# WorkStations

Enabling Zero Learning Curve, Open-Source, Virtualized Notebooks, Curated Algorithm Notebooks, Model Zoo Notebooks

To get a deep insight and understanding of our Ai-WorkStation, refer to our [website](https://www.computational.zeblok.com/aiworkstation).

![Fig. 1: Public WorkStations](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FTEN5Ulhe19aGlowe9lGn%2Fimage.png?alt=media\&token=c0c88c8f-f2b8-49c6-baf2-b7fec7805d7d)

This section shows a list of **containers** which have already been brought to the Ai-MicroCloud and are ready to be spawned by the user using the steps mentioned in **Spawn Ai-WorkStation Guide** under our Quick Start Section of the documentation.

**Create WorkStation**

![Fig. 2: Create WorkStation](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FdFoqTuKW7DdemxFnhjt8%2Fimage.png?alt=media\&token=582f0cd6-f182-4eb8-80d5-76d39cac08c1)

In Fig 1. You can see the Create New WorkStation Button which opens a dialog box shown in Fig. 2.

Note: This Is the screenshot of adding a container from a private Repository too by providing the required fields as shown.

The following are the definitions for the fields shown in the Create WorkStation form.

**Resource Name** => The name of the WorkStation you would like to give.

**Image Tag** => The Image Name along with tag of the docker container.

**Image Run Command** => The default RUN Command you want to execute at the start of the workstation (OPTIONAL).

**Private Repository Toggle** => Enable it if the container resides in a private repository and also provide the 4 field values which are only to be filled when the container is in a private repository.

**Select Compatible Plan** => This is a multi-select dropdown of the available plans and you have to select the ones suitable for this container.

**Select Default Plan** => This is a dropdown among all the plans chosen in the previous field to chose one of them as the default plan.

**Public Access to WorkStation** => Disabling it will only let the superadmin view this container for spawning.

**Description Box** => Provide a suitable description for this WorkStation for the users to understand the capabilities of this workstation.

**Video Link** => You can provide a video link for this container too, if available.

**Upload Image** => Upload an image for this container as a thumbnail.

**Type of workstation** => Select one of the three categories we have here at Ai-MicroCloud right now for the user’s convenience and understanding as it will be categorized accordingly.

**Stripe Product Id** => All the products have a stripe Id for the billing and metrics purposes.

**GitHub URL** => Url to clone after the initialization of workstation

**GitHub branch name** => Branch name for the github url

&#x20;

Note: All the fields are required and leaving an empty value won’t let you add the WorkStation. It is advised to write N/A if you do not have a value for a text field


# IAM (Identity Access Management)

IDENTITY ACCESS MANAGEMENT

As the name suggests, IAM (Identity Access Management) is the gateway checking the authorization of the requests coming from a user and won’t permit if any request seems unauthorized.

To know more in details about the underlying sections in our IAM system, refer to our [**IAM directory of the documentation under MORE Section**](/info/1.2.0/more/iam).


# Organizations

This section shows a list of organizations using the Ai-MicroCloud as a member.

![Fig. 1: List of Organizations](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FGmkIYFUc16A6VAp4fSq1%2Fimage.png?alt=media\&token=335f1a47-7944-4158-8345-8996799ab05c)

**Create New Organization**

![Fig. 2: Create Organization](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F00amdZf7OTsX45MpPAcj%2Fimage.png?alt=media\&token=7834c4be-3976-415b-9d09-de06758a794d)

The following are the definitions of the fields in the Create New Organization Form:

Organization Name => Name of the Organization

Select Admin => Dropdown list of all the users in the Ai MicroCloud from which you can make the appropriate person the admin of the organization.

Country => Dropdown list of countries which specifies the HQ location of the organization.

**Note:** Creating an organization automatically creates 2 new namespaces for this organization by default: **public** and **private**. For more information, refer to our **NameSpace Guide** under this Section.


# Plans

Resource Aggregation

This section shows a list of plans which specify the resources to be allocated and get attached to a WorkStation or a Microservice and come as a [**fourth step In the Spawning Ai- WorkStation Workflow**](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation#step-4-beta-user)**.**

![Fig. 1: List of Plans](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FHFGwanebO3JgLL4FgsRm%2Fimage.png?alt=media\&token=1a9e40f7-df46-40c0-986c-5a352700599a)

**Create New Plan**

![Fig. 2: Create New Plan](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FMMxIQqoGmLRXm65CwMCn%2Fimage.png?alt=media\&token=4669e860-abbe-4bf4-af7d-cd3e52c8966f)

The following are the definitions of the fields in the Create New Plan Form:

**Name** => Name of the plan

**vCPU** => Number of vCPUs to be allotted by this plan.

**GPU** => Number of GPUs to be allotted by this plan.

**Worker Nodes** => Number of worker nodes (Used for High Performance Computing).

**Public Access to the Plan** => Toggle to make it available to the public or not.

**Slurm – enabled** => Toggle to make this plan available for HPC (High Performance Computing).

**Memory (GBs)** => RAM to be made available by this plan.

**Storage (GBs)** => Storage to be made available by this plan.

**Stripe Product Id** => All the products have a stripe Id for the billing and metrics purposes.

**Select Plan Type** => There are 3 categories available right now:

\-          Ai- WorkStation

\-          MicroService

\-          Ai-API

**Data Center** => Dropdown list of datacenters available in the Ai-MicroCloud where the resources can be allotted by this plan.


# NameSpaces

Resource Segregated Spaces

As the name suggests, these are segregated spaces for organization’s activities where the superadmin decides or even the organization admin decides the members of the namespace under which those users can spawn an Ai-WorkStation, MicroService or an Ai-API.

![Fig. 1: List of NameSpaces](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2Fros0PorTHA0JFuoH3xUD%2Fimage.png?alt=media\&token=3a59315c-c5c4-45ea-b2a6-200a95591128)

**Create NameSpace**

![Fig.2 : Create NameSpace](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FH9kFNtjyaH7CIk8HOT8n%2Fimage.png?alt=media\&token=171f0b73-7e1a-464e-b227-692fd00a86a5)

Two new namespaces with suffix **private** and **public** are created whenever a new organization is created for the users. Also, the users have to be added by the superAdmin or an OrgAdmin for the users to be able to spawn their resources.


# DataCenters

Dedicated space for workload deployments and development

This section lists the datacenters added in the Ai-MicroCloud which ultimately come as an option attached with the plan as shown in our [**Step 4 in Spawn an Ai-WorkStation Guide**](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation#step-4-beta-user).

![Fig. 1: List of DataCenters](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2Fhu05Ou0QdKXlRjUAON1g%2Fimage.png?alt=media\&token=5dcfcaf0-491a-46d7-8acb-8bb735063b2c)

**Add new DataCenter**

Adding a new Datacenter is a two-step process:

·         Filling up the form as shown in the below mentioned image.

![Fig. 2: Form for Adding DataCenter](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FxrsFlisz1cVr8A1BqTMI%2Fimage.png?alt=media\&token=190e131d-9483-4804-a167-0d852dbc6434)

• Approval of the datacenter by the superAdmin.


# MicroServices

Standalone containers and interconnected ecosystem of containers

This section shows a list of **microservices** which have already been brought to the Ai-MicroCloud and are ready to be spawned by the user using the steps mentioned in [**Spawn a MicroService Guide**](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-microservice) under our Quick Start Section of the documentation.

![Fig.1: List of MicroServices ](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2FTUpxa14j2dXP5nb5BvHR%2Fimage.png?alt=media\&token=5be0a657-76a7-468b-8743-d39fba43eb65)

**Add MicroService**

![Fig. 2: Add MicroService](https://4027508532-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MecgpHyRD3Y801omxL9-1019324243%2Fuploads%2F780W6E2ew6ToupRyYTqj%2Fimage.png?alt=media\&token=0f0b67d3-4d95-4750-88d9-db31c1b8ee72)

The following are the definitions for the fields shown in the **Create MicroService** form.

**Resource Name** => The name of the WorkStation you would like to give.

**Image Tag** => The Image Name along with tag of the docker container.

**Select Compatible Plan** => This is a multi-select dropdown of the available plans and you have to select the ones suitable for this container.

**Select Default Plan** => This is a dropdown among all the plans chosen in the previous field to choose one of them as the default plan/ recommendation.

**Public Access to MicroService** => Disabling it will only let the superadmin view this container for spawning.

**Description Box** => Provide a suitable description for this WorkStation for the users to understand the capabilities of this microservice.

**Internal Ports** => List of port numbers with their protocol which are required for this microservice to work.

**Upload Image** => Upload an image for this container as a thumbnail.


# Customised Workstations

Containerization of the Third Party Algorithm

### Objective

Containerizing third party algorithms and using Zeblok's Ai-MicroCloud™ to provide access to more audiences.

### **Steps to follow**

Zeblok offers a basic minimal notebook with pre-installed CUDA Libraries and the associated Docker Hub URL and Dockerfile Urls are given below.

<https://hub.docker.com/u/zeblok> (Docker hub) <https://github.com/zeblok/dockerImagesFiles> (Dockerfiles on github)

* Developers can use one of the Zeblok’s ready to use Docker Images as a base Image in his/her Dockerfile.
* Developers can write the instructions to install dependencies that are required by the Algorithm. (For Instance, if a user’s Algorithm requires BlazingSQL and Rapids AI as dependency, the user can take the Minimal notebook as base and install the dependencies on top of that base in a new Dockerfile as shown below).

```
ARG BASE_CONTAINER=zeblok/minimal-notebook:v0.0.7
FROM $BASE_CONTAINER
USER $NB_UID
RUN pip install -q --pre bentoml
RUN pip install 'scikit-learn>=0.23.2' 'pandas>=1.1.1'
USER $NB_UID
```

* After writing the Instructions for installing the dependencies, the developer needs to build the Image from the Dockerfile using the command \`**docker build -t ‘ALGO\_NAME:VERSION**’ .
* After Building the image user can push the image to dockerHub using the command&#x20;

  \`**docker push dockerUsername/ALGO\_NAME:VERSION**\`.
* After successfully pushing the Docker Image developer will share the docker image Tag, short description, and an Image (400x220px) to <akash.sengar@zeblok.com>.

  <br>


# Release notes

ZEBLOK COMPUTATIONAL AI-MICROCLOUD RELEASE ROADMAP

**Version 1.2.0 (JUNE 2022)**

{% tabs %}
{% tab title="SaaS Updates" %}
Zeblok Python SDK now has the feature to **deploy simultaneous multi-datacenter Ai-Pipelines** with also the ability to integrate the Ai-Runs output with open source tools.
{% endtab %}

{% tab title="PaaS Updates" %}

* Dashboard now has the ability of **one click export users’ data** table as CSV for super admin and admins.
* Every user will now get a **weekly mail** regarding his/ her usage details over the week.
* **Private Docker Image repository support** has been enabled for both Ai-WorkStations as well as MicroServices, giving users the privilege to pull images from their private repositories.
* Users can now **select from multiple versions** of an Ai-WorkStation or MicroService while spawning (latest or a previous version).
* **Single click social media sign in** has been enabled via google.
* Google Authenticator Process has been enabled for a strong **multi layered security process**.
* MicroService spawning and Ai-API spawning process now have a configuration of plans attached which will  also be reflected in the monitoring graphs of the same.
* MicroServices are now flexible to **support multiple protocols** which can be exposed publicly or can be interconnected to other **microservices as an ecosystem**.
* Spawning process has been made more error resistant, optimized and also intelligent with zeblok **cli auto configuration** process while spawning.
* Ai-WorkStation spawning workflow now gives you a choice to **mount your S3 bucket** from our Ai-DataLake.
* A **new MLOps Workflow** has been introduced for simultaneous multi-datacenter **Ai-Pipeline, Runs and experiments** with seamless integration with open source tools, which can be initiated using the zeblok cli.
  {% endtab %}

{% tab title="IaaS Updates" %}

* **Zeblok Private Image Repository** is the newest member in our Zeblok Infrastructure Ecosystem for real time security scans of the images as well as providing the security scan logs along with the severity of risks.  This increases overall security as well as the image pull limit becomes a thing of the past.
* Zeblok Containerization Service has been upgraded for **containerizing the Ai-Pipelines** images as well as for the auto deployment of the same.
  {% endtab %}
  {% endtabs %}

**Version 1.1.0 (MARCH 2022)**

{% tabs %}
{% tab title="SaaS Updates" %}

* Openvino Model Serving capabilities are now supported in the Ai-API Engine.&#x20;
* Openvino toolkit distribution has been upgraded to version 2022.4.1&#x20;
* Ai-WorkStations have been upgraded with Nvidia Cuda Version 11.4&#x20;
* JupyterLab has been upgraded to the latest version along with Python v3.9.
  {% endtab %}

{% tab title="PaaS Updates" %}

* New IAM (Identity Access Management) has been developed giving users and admins access to modify roles and permissions in a dynamic way giving more flexibility and ownership to the authorized users.&#x20;
* Username of the authorized user has been mapped to jupyterlab notebook spawning process giving more insight to security and tracking of activities.&#x20;
* Zbl Cli has been upgraded for the openvino packaging process of the IR models generated by Openvino notebook giving users more freedom on the Model Serving process.&#x20;
* Zbl Cli now has a new option/ feature for automating the Ai-API Deployment process using which users can predetermine their choices/ parameters for their deployment.&#x20;
* A new cross cloud service has been established where the packaged models from the cli are uploaded and image building and pushing to hub steps have been undertaken by the cross cloud service. A mail is sent to the users after the models become ready for deployment via Ai-API Engine.&#x20;
* Ai-API deployment now supports GRPC protocol where, on using a suitable GRPC client, users can interact with the trained models in a deployed state.&#x20;
* Zeblok Ai-DataLake has been upgraded and a one click auto account setup system has been introduced for the users along with RBAC security policies.&#x20;
* Resource Manager has been re-introduced now extending its capabilities for an organization admin too, where the administrator now has full control and insight over the resource consumption and Spawned Resource activities of the members of the Organizational Unit.&#x20;
* Auto backup of the MongoDB is enabled every 6 hours in all the environments.&#x20;
* Seamless Database seeding is enabled for quickly restoring the database from the backup.
  {% endtab %}
  {% endtabs %}

**Version 1.0.0 (DECEMBER 2021)**

{% tabs %}
{% tab title="IaaS Updates" %}

* Zeblok Ai-MicroCloud is now available at Azure Cloud Environment with all the latest features and power giving the same experience of Zeblok AI-MicroCloud on the Azure Platform.&#x20;
* Zeblok has established Ai-MicroClouds for two private baremetal turned cloud environments: Advantech Labs and Intel Dev Cloud.
  {% endtab %}

{% tab title="PaaS Updates" %}

* Notebook creation workflow has a new field added now for specifying run commands as a post workstation creation lifecycle which comes as a configuration flexibility for the Notebooks’ running.&#x20;
* DataCenter (only edge categories) have now an option for adding kiosks to them which can be selected for deploying your microservices and Ai-API on a specific kiosk.&#x20;
* Ai-API workflow has a new step added now for the selection of kiosks while selecting an On-Premise DataCenter.&#x20;
* Microservices also have a new step added now for the selection of kiosks while selecting an On-Premise DataCenter.&#x20;
* A new section in the menu has been added for Virtual Machines where you can get the shell access to a kiosk which is available as a node on the on-premise DataCenter.&#x20;
* Datacenter Monitoring page has been added for getting a status of the performance of all the nodes in the datacenter cluster along with a provision to view the monitoring logs and graphs of a specific node too.&#x20;
* A button to view the Ai-WorkStation or the MicroService pod logs has been given to view logs while the spawned resource is in running mode.&#x20;
* Session monitoring of all aiws,microservices and aiapi has been enabled for all the users so that the users can monitor the workloads and resources being consumed by their spawned resources and also decide if they need to upgrade to another plan.&#x20;
* A brand New user interface has been released giving a rich and smoother experience of the whole Ai-MicroCloud.
  {% endtab %}
  {% endtabs %}

**Version 0.0.9 (SEPTEMBER 2021)**

**PaaS Updates:**

* Admin analytics dashboard has been updated with more precise and accurate data along with bug fixes providing a more precise idea of the usage by the users.&#x20;
* Zeblok Authentication MicroService has been updated with more secure tokens and authorization logics while making the user’s authentication and signup process easier than before.&#x20;
* Zeblok Ai-MicroCloud introduces a brand new workflow for microservices where you can run pre-uploaded and modified images in an isolated and an independent environment in just a few clicks like MongoDB, Intel DLWorkBench, etc.&#x20;
* Session page now also handles metrics for spawned microservices along with Ai-WorkStations.&#x20;
* User’s profile has two new tabs for Spawned MicroServices and one for their total runtime consumptions, both of which can be accessed by the SuperAdmin and the Organization’s Admin.&#x20;
* Periodic Backup in every 6 hours has been established in aws s3 buckets as a disaster management measure.&#x20;
* Superadmin now gets a new tab in their menu called “Resource Manager” where you can have a look at all and every kind of resource in the Ai-MicroCloud like Ai-WorkStation, MicroServices and Ai-API and also control them if required.

**Version 0.0.8 (JUNE 2021)**

Infrastructure Re-Architecture is done for better performance.

* Jupyterhub is taken out and Kuberntetes APIs are Introduced for Orchestration giving a more stable infrastructure and debugging system.&#x20;
* This new Architecture allows more control over resources and gives a faster experience so that the users don’t have to wait for the spawning process for too long.&#x20;
* Dynamic Plans can be introduced now giving full access to the power of the infrastructure.&#x20;
* Istio Mesh Networking is introduced for Load Balancing and Networking among the pods for better connectivity along with a better security.

**PaaS Updates:**

* Login and Signup pages have a new UI now which is also mobile responsive.&#x20;
* Update has been rolled out for the new Admin analytics dashboard with more analytical metrics for viewing the activities of specific users in an organization.&#x20;
* Session page has more attributes added for more in depth metering and analysis.&#x20;
* User’s profile has a new tab for durations of the Ai-WorkStations now.&#x20;
* The Organizations table has a new View button for viewing the users and their duration of work in the Ai-Workstations.&#x20;
* Server Side pagination is implemented for reducing the bandwidth usage for users.&#x20;
* We now introduce a new workflow in our Ai-MicroCloud called Ai-API Engine which can be accessed by going to the Ai-Api section in the menu and clicking on the Create Ai-API button. For more information, you can visit <https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/introduction&#x20>;
* A new separate Zeblok Authentication microservice has been added exclusively for enhanced Authentication Processes and validation and also giving users the ability to secure their account using 2 factor authentication.&#x20;
* The Login Method has been improved with the addition of Refresh Tokens and JWT Token for a better and new level of security.

**Version 0.0.7 (MARCH 2021)**

{% tabs %}
{% tab title="IaaS Updates" %}
**All the Zeblok benefits, now in AWS:**

Automated/scripted the deployment of the Zeblok platform within AWS, which will help us serve our customers better. How?

* They don’t have to move their data across datacenter or platforms, reducing a large amount of effort and billing, as they don’t have to engineer the data movement in and out of AWS, which also impacts data security. Less movement of data in and out of AWS saves bandwidth cost.
* Usage can be customized as per individual organization needs. Doesn’t matter if the requirement is of 1 GPU or 10 or 100, the system can easily be scaled as and when required. Increasing impact or ROI and decreasing un-utilized cost.

To learn more about our AWS Deployment. Visit [here](https://docs.google.com/document/d/1UPAoEAeZ0rn3w8mWLCyAFludqEGdMNajoGlYmMfKo4c/edit?usp=sharing).
{% endtab %}

{% tab title="PaaS Updates" %}

* Admin can now view stats such as how many users per day, per week have onboarded.&#x20;
* Admin can sort by Each organization and view how many notebooks and users.&#x20;
* New menu called Activity Monitor is added. All data aggregation happens here.&#x20;
* Which user has access to what type of notebooks&#x20;
* Activity Report is now available.&#x20;
* Usage statistics are now available - by organization, user group, plan&#x20;
* Updated Menu Hierarchy and rearranged icons for enhanced user experience&#x20;
* Successfully implemented and deployed PaaS Foundational components and AI data lake in the AWS environmen&#x74;**.**
  {% endtab %}

{% tab title="SaaS Updates" %}

* Documentation for AI-Rover is now available.&#x20;
* Recently collaborated and acquired new video analytics algorithms for edge IoT applications&#x20;
* Custom AI-rover development workstations are available for the fintech use-cases
* Data Scientists and ML developers can now containerize and deploy their own algorithm workstations in the Zeblok Intelligence Marketplace. The user guide for containerizing of algorithms is available [here](https://drive.google.com/file/d/1ZsuIa5D41h4KStbW7s3dayhrJZdkliQu/view?usp=sharing).
  {% endtab %}
  {% endtabs %}

**Version 0.0.6 (DECEMBER 2020)**

{% tabs %}
{% tab title="ZEBLOK SUPERADMIN" %}

* A new button of DATA LAKE is added besides the create workstation button where users can experience object storage provided via zeblok for storing their necessary files for their Ai-WorkStation.
* Session Icon (Time Watch) is added to the listed spawned workstation (Active) on the landing page , where you can see your sessions.
* **Activity Logs**
  1. A new tab is added in the profile section where you can see all your activities and the resources which you have visited.
* **DashBoard**

  1. All users display more information like Allowed Notebook , Last Active etc are visible.
  2. A new Section in View Button of Users is added to Activity Logs , where Super Admin can monitor users activities.
  3. A quick summary of users is displayed and a “View More analytics” button is added for further resources monitoring page.
  4. Users Section - In the users information display , on clicking “View” for a particular user , 2 new tabs of activities and spawnedImages are created to show its activities log and spawned Workstation by use&#x72;**.**

  **Resources Monitoring**
* Super Admin can see following data
  * Total number of resources created like Workstations ,User Groups,Roles, Organizations,Plans etc.&#x20;
  * Further re-distribution pie charts of various different sub categories of resource like -&#x20;
    * Workstations : Data Science , Algorithms , Hyperconvergence .&#x20;
    * Plans : CPU , GPU , Both&#x20;
    * Data Center : Public , Private&#x20;
  * A User Statistics Bar graph showing all new Users , all new Beta Users , all new Non Beta Users created along with that all active users , all active Beta users , all active non Beta users.&#x20;
  * A Stacked Graph of users created each day is shown with categories of Beta and Non Beta User.&#x20;
  * A pie chart showing Spawned Images data of users along with a table of further different categories of data.&#x20;
  * Stacked Bar Graphs showing Workstations Created Day wise ,Workstation which are currently running as Day wise ,Number of CPU/GPU spawned with the notebooks on the respective date.&#x20;
  * A stacked Bar graph showing the count of All Notebooks spawned with different plans.&#x20;
  * For more detailed information , please refer to <https://docs.google.com/document/d/1sv0aMzLhc63X5HKsAPfSufRn8kz8mH4eXnkTHMcPBEU/edit?usp=sharing&#x20>;
  * All the data can be filtered out between any time intervals. While the data which is related to any organization then it will be updated as per the organization.&#x20;
  * Admin can use filters for both categories like Search by Organization , Search by Duration or Both.
* **Workstation**
  * In the workstation table , a new column of licence is added to put licenses in algorithms and hpc’s.
* **IAM Menu**
  * A new menu of IAM introduced which consists of all access management menus like roles , resources , menu and user groups from where superadmin can give or modify access for a specific role in the Ai-MicroCloud.
  * This helps to customize the side navigation menu also.
    {% endtab %}

{% tab title="Enterprise Admin" %}

* **Landing Page**
  * &#x20;A new button of DATA LAKE is added besides the create workstation button.
* **Session Icon (Time Watch)** is added to listed spawned Images (Active) on the landing page , where you can see your sessions.
* **Activity Logs**
  * A new tab is added in the profile section where you can see all your activities and the resources which you have visited.
* **DashBoard**
  * All users display more information like Allowed Notebook , Last Active etc are visible.
  * A new Section in View Button of Users is added to Activity Logs, where Super Admin can monitor users activities.
  * A quick summary of users is displayed and a “View More analytics” button is added for further resources monitoring page
  * **Users Section**
    * In the users information display , on clicking “View” for a particular user , 2 new tabs of activities and spawnedImages are created to show its activities log and spawned images by user.
* **Resources Monitoring**
  * A User Statistics Bar graph showing all new Users , all new Beta Users , all new Non Beta Users created along with that all active users , all active Beta users , all active non Beta users.
  * A Stacked Graph of users onboarded each day is shown with categories of Beta and Non Beta User.
  * A pie chart showing Spawned Images data of users along with a table of further different categories of data.
  * Stacked Bar Graphs showing Workstations Created Day wise ,Workstation which are currently running as Day wise ,Number of CPU/GPU spawned with the notebooks on the respective date.
  * A stacked Bar graph showing the count of All Notebooks spawned with different plans.
  * For more detailed information , please refer to [**https://docs.google.com/document/d/1sv0aMzLhc63X5HKsAPfSufRn8kz8mH4eXnkTHMcPBEU/edit?usp=sharing**](https://docs.google.com/document/d/1sv0aMzLhc63X5HKsAPfSufRn8kz8mH4eXnkTHMcPBEU/edit?usp=sharing) (Organization Admin section)
  * All the data can be filtered out between any time intervals. By default , data of the last 6 months is displayed.
    {% endtab %}

{% tab title="Enterprise User" %}

* **Activity Logs**
  * A new tab is added in the profile section where you can see all your activities and the resources which you have visited.
* **Landing Page**
  * A new button of DATA LAKE is added besides the create workstation button.
* **Session Icon (Time Watch)** is added to listed spawned Images (Active) on the landing page , where you can see your sessions.
  {% endtab %}

{% tab title="Individual Users" %}

* **Activity Logs**
  * A new tab is added in the profile section where you can see all your activities and the resources which you have visited.
* **Landing Page**
  * A new button of DATA LAKE is added besides the create workstation button.
* **Session Icon (Time Watch)** is added to listed spawned Images (Active) on the landing page, where you can see your sessions.
  {% endtab %}
  {% endtabs %}

**Version 0.0.5 (SEPTEMBER 2020)**

* An AlgoStore is now made available for the users to go and get detailed information about all the containers giving knowledge and also making the selection easier according to the needs.
* Read More button on each algorithm provides information on capabilities, a youtube video link and links to other sources for more information.
* Join Slack option provided for all users to join our dedicated Slack channel for any kind of clarification, bug posting and discussion with our team.
* Documentation link is provided at the navbar to read and understand the design and workflows of the Ai-MicroCloud for a non ambiguous experience.

{% tabs %}
{% tab title="ZEBLOK SUPERADMIN" %}

* **Dashboard**&#x20;
  1. Can view all the users present on the platform segregated according to their roles, organizations for getting a view of the whole microcloud users.&#x20;
  2. Each user is categorized into a beta and non-beta user. Admin can update the user as beta or non-beta. Beta users have many more features unlocked for them than a non beta user.&#x20;
  3. Each user has a no. of allowed notebooks assigned to him. The user can only spawn that many number of notebooks if he is a beta user which depends on his subscriptions and resource management rules.
  4. Beta users are the ones who are already present in the computational-beta environment. For these users they do not have to buy plans. Their billing would continue as it was happening before. They can spawn a limited number of notebooks as given access by the Zeblok Admin.
* **Workstations**
  1. All notebook containers are displayed here as a list in a table where the superadmin can perform CRUD operations on the notebooks.&#x20;
  2. Superadmin can edit the notebook image, name, description, restrict public access, add video hyperlink and other sources, and can add the stripe product ID for charging this workstation.&#x20;
  3. Superadmin can set the related plan and default plan for the container.
* **Spawned Images**
  1. Workstations spawned by the users are shown in Ai-WorkSpace along with the current status of their workstations and corresponding sessions.&#x20;
  2. All the activities of each workstation can be listed by clicking on their respective sessions icon giving a full in-depth overview of the activities done on the Ai-WorkStation.
* **Roles**
  1. Orgadmin role added giving full access to the organizational unit which consists of an orgadmin and all org users.&#x20;
  2. Orguser Role added as the role given to the users who are invited to the Ai-MicroCloud via an invite sent out by the OrgAdmin from the dashboard.
* **Plans**
  1. Plans can now be edited and deleted by the zeblok superadmin giving a more dynamic resource allocation system for the Ai-WorkStations.
* **Data Center**
  1. Data center requests can be seen here (Requests are by default given a Pending status).&#x20;
  2. It is the responsibility of zeblok admin to check and approve those data center requests and make them active.&#x20;
  3. Once approved these data centers would be visible to the users while creating workstations. (shown on the world map)
     {% endtab %}

{% tab title="Enterprise Admin" %}

* **Dashboard**
  1. Enterprise Admin can invite users to be a part of his enterprise. He/She will be able to send out the mail to the users he wants to invite.&#x20;
  2. Can view all the users of his enterprise and according to their roles and beta users.
* **Other accessibility**
  1. The enterprise admin can use the zeblok platform the same way a normal user (spawning workstations, use data lake etc.)
     {% endtab %}

{% tab title="Enterprise User" %}

* **SignUp**
  1. Enterprise users are invited by enterprise admins to join the zeblok platform under the enterprise.&#x20;
  2. Once invited, enterprise users will receive a mail to signup to zeblok platform under their respective enterprise.
     {% endtab %}

{% tab title="Individual Users" %}

* **Create Workstation**
  1. **Select Your Plan**

     * Available Plans now show all data center locations on map.
     * Plan details (vCPU, GPU, RAM and storage) displayed by hovering mouse over the specific plan card with Buy Plan Button if subscribed and select plan if not subscribed.

     **Reference Link :** [**https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation**](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation)
* **Computational App non-HPC**
  1. Zeblok Admin Role enhancements with permissions and access&#x20;
  2. Enterprise Admin Role enhancements with permissions and access
* **Computational App HPC**
  1. Slurm Workers support for Conda&#x20;
  2. Slurm Workers support for MPI
* **Computational Algo Store**
  1. HPC Notebook showing Distributed Tensor flow (CPU only)
* **Infrastructure**
  1. Full featured TEST environment&#x20;
  2. HPC file system with LUSTER.&#x20;
  3. Storage Virtualization re-architecture with CEPH block store
* **Encryption in Transit**
  1. VPN based for kube traffic
     {% endtab %}
     {% endtabs %}

**Version 0.0.4 (JUNE 2020)**

* Each Notebook has some predefined plans by the admin, and among them is a default plan which is recommended by us for the selected workstation to run without any resource limitations.&#x20;
* Organization Admin Role Added for better handling of access control within the organization so that the onboarded users can make the microcloud their own.&#x20;
* Organization Admin has been given the access to view/edit/update/delete all the users under his organization.

**Version 0.0.3 (MARCH 2020)**

* The better, fresh and responsive user interface is now available.
* Jupyterlab and Notebooks are updated to their latest Versions.
* Each user will now have access to a dedicated GPU and from 4GB to 8GB of memory.&#x20;
* Each user will be able to spawn one server at a time.
* Cull feature is now introduced. If a workstation is not utilized by users for two hours then it is automatically culled and resources released, if the browser session is killed. JupyterHub will run the culling process every ten minutes and will cull any user pods that have been inactive for more than one hour.&#x20;
* A license agreement is now required on signUp which is stored in the Database.&#x20;
* Zeblok Readme Notebook is now available in the environment showing tutorial instructions on retrieving compute, datalake and other platform features.&#x20;
* Nvidia Rapids example Notebooks are available on spawning the server using Nvidia Rapids Image.&#x20;
* Now the infrastructure has been moved within a VPN, making it more secure and easy to expand the infrastructure.&#x20;
* Slack community is added.

**Version 0.0.2 (DECEMBER 2019)**

* A wide range of Ai-ML and DataScience Notebooks is added now as a library of notebooks giving users multiple options to spawn in JupyterHub like PySpark, TensorFlow and many more.
* Ai-AppStore now includes trademarked notebooks and available for use upon agreeing the license agreement for Terms and usage. For example: Explainable AI by Akai Kaeru.
* Notebooks have been CUDA optimized for the NVIDIA GPU with SLI support.

**Version 0.0.1 (SEPTEMBER 2019)**

* Users are now able to spawn JupyterHub based notebooks as Ai-Workstation within CEWIT (Center of Excellence in Wireless and Information Technology) Datacenter cluster.
* Users are now allowed to spawn basic minimal notebooks with cuda optimization for NVIDIA GPU cards (RTX6000) saving enormous time for users.
* JWT Authentication layer is now available on top of our JupyterHub that authenticates only the valid users to spawn in a secure manner.


# Known Issues


# Common Errors


# About Zeblok Computational

The Zeblok Ai-WorkStation provides a single unified pre-configured environment for data scientists to access datasets, GPU-powered AI/ML frameworks, languages, and tools, with AI algorithms available from our Intelligence Marketplace. The Ai-WorkStation includes one GPU, one vCPU and 64 GB of storage, but scales easily as required. For more demanding workloads, the Zeblok Ai-HPC-WorkStation adds Slurm-as-a-Service and parallel processing, using worker nodes, by enabling the deployment of 4 or more GPUs.

The Zeblok Ai-WorkStation is built upon a Jupyter notebook, an interactive coding environment that lets you combine code with equations, visualisations, rich text, and other media. We make it easy to explore data and coding concepts and collaborate with other people on data science projects.


# Core Concepts

### Ai-MicroCloud™

Ai-MicroCloud™ provides a single, cohesive, turnkey, cloud native AI environment for development, testing, training and deployment of an end-to-end AI/ML solution to production from Core to Edge.

It saves 12-18 months of engineering effort to integrate the multitude of technologies, countless hours of business effort to establish a compatible and collaborative AI ecosystem, and reduces GTM for ISVs by 8-12 months.

[Learn More...](https://www.computational.zeblok.com/ai-microcloud)

### JupyterLab: Jupyter’s Next-Generation Notebook Interface

JupyterLab is a web-based interactive development environment for Jupyter notebooks, code, and data. JupyterLab is flexible: configure and arrange the user interface to support a wide range of workflows in data science, scientific computing, and machine learning. JupyterLab is extensible and modular: write plugins that add new components and integrate with existing ones.

### The Jupyter Notebook

The Jupyter Notebook is an open-source web application that allows you to create and share documents that contain live code, equations, visualizations and narrative text. Uses include: data cleaning and transformation, numerical simulation, statistical modeling, data visualization, machine learning, and much more.

### Ai- WorkStation

The Zeblok Ai-WorkStation provides a single unified environment, which seamlessly orchestrates infrastructure, open source AI/ML frameworks and proven, original AI algorithms. An intuitive and simple user interface enables a data scientist, data engineer, or AI engineer to access petaFLOPS of computing power, efficiently develop and train new AI models and take them to production in a runtime environment on the same platform, with consummate ease.

[Learn More...](https://www.computational.zeblok.com/aiworkstation)

### Intelligence Marketplace

Zeblok’s Intelligence Marketplace provides easy access to a growing library of proven, original AI algorithms. Quality is ensured by our curation process, including closed loop validation, providing algorithm creators with a means of commercialization not previously available. We ensure that algorithms are easy to read, easy to use and easy to share. These include:

* Ai-Rover™ Notebook: Data Comprehension/Visualization Tool
* Ai-Rover™ Notebook For Time Series Data: Automated Predictive Model Builder&#x20;

[Learn More...](https://computationaldocs.zeblok.com/zeblok-computational-1/marketplace/intelligence-marketplace)

### Ai-HPC-WorkStation

Zeblok enables you to seamlessly scale to high-performance computing (HPC). Access HPC resources via a Jupyter Notebook.

One-click scalability for AI workloads.

### Ai-Data Lake

A data lake is a centralized repository that allows you to store all your structured and unstructured data at any scale. Zeblok Ai-Data Lake is a high-performance data-store that allows you to import, filter, and instantly analyze objects. Our solution is designed for performance, scales up with your data, and can provide industry-grade SSL security and data-redundancy for high availability of data at SSD speeds.

[Learn More...](https://computationaldocs.zeblok.com/zeblok-computational-1/data-and-metrics/datalake)

### Ai-APIᵀᴹ

Getting machine learning models into production is hard. Data scientists are not experts in building production services and DevOps best practices. The trained models produced by a data science team are hard to test and hard to deploy. This often leads to a time consuming and error-prone workflow, where a pickled model or weights file is handed over to a software engineering team.

Zeblok’s Ai-API™ Engine resides within Zeblok’s Ai-MicroCloud™ to facilitate deploying trained machine learning models anywhere. It bridges the gap between data science and DevOps, enabling teams to deliver AI inferences in a fast, repeatable and scalable way.&#x20;

[Learn More...](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/introduction)

### Ai-MicroCloudᵀᴹ Manager

Ai-MicroCloud™ Manager is the centralized management utility for Ai-MicroCloud™ and is used to manage and orchestrate all dependent components for Ai-WorkStation, Ai-HPC-WorkStation, Ai-Data Lake, Intelligence Maketplace and the Ai-API™ Engine.&#x20;

The Ai-MicroCloud™ Manager enables the enterprise administrator to define role-based access control, infrastructure plans (vCPUs, GPUs, memory, storage), define Namespaces and add accessible data centers, and provides metering information for resource utilization monitoring, billing or charge back purposes.<br>


# Create an Account


# Individual User

Individual User Signup Process

Click on this link <https://app.zbl-aws.zeblok.com/signup> to create an account with Zeblok Computational. You will be redirected to the Zeblok Computational Individual Signup page.

![Individual Signup Page](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/nscFNJ5cjQKe80TTF3YQ/image.png)

Enter the required details and follow the further instructions which will be sent to your e-mail after signup details' validity processing.

After entering all the credentials as shown below . click on signup button and you will see this notification on the top . **Welcome to the Zeblok Computational AI Platform. Please check your email for an account activation link to complete your registration.**

![Fill all the Credentials](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/mkOxkhS9Nqm56c7vjKQs/image.png)

After that go to the registered email id used while signing up and click on the link which is send to your registered email id

![Click on Link button ](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/zxsIwZ01El6hnjevnfzl/image.png)

After Clicking on the **Link** button  you will be redirected to a page as shown below and then again click on login button as per the instructions on the page.

![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/RykBsDlOMgLSo8Fj4UEy/image.png)

After clicking on the login button as shown above you will be redirected to a page where you will have to enter your login credentials those credentials should match the ones which you entered while registering yourself.

![Click on Sign In after filling the detail](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/vG1ca2X4WrPozHSqQVD9/image.png)

After you Sign In  successfully you will be redirected to the dashboard.

![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/W1NQrkegCG0M2wHIeNty/image.png)


# Sign In

Create free account here

Click on this link <https://app.zbl-aws.zeblok.com/> to Sign In  with your **Zeblok** Computational account.

![Sign In page ](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/mQzd4tgDFNfG729sHBxg/image.png)

Enter the required details and you will be redirected to the **Zeblok** dashboard page.


# Spawn Ai-WorkStation

Step By Step Guide for Spawning an Ai-WorkStation

### Overview&#x20;

Once you logged into the Zeblok Computational Application, you will get an option for **Spawn Ai-Workstation** as shown in the screenshot below.

![Figure 1: Dashboard](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/vN74OzI6E1mqC2tI1SKP/image.png)

#### **Step 1**

Click on "Spawn Ai-Workstation", you will be redirected to a page as shown below.

![Figure 2: Spawn Ai-WorkStation](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/hocuXCdhXpBSsmlSlVwr/image.png)

#### &#x20;**Step 2**

Select the Notebook which you want to use, whether it can be an Ai-WorkStations, Intelligence Marketplace, or Ai-HPC-WorkStations as shown below.

![Figure 3: 3 Types of Notebooks](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/hocuXCdhXpBSsmlSlVwr/image.png)

#### **Step 3**

Depending on whether you are a beta user or not, all the plans will be unlocked for you and ready to use if you are a Beta User. Currently, everyone is given **BETA Access**.

#### **Step 4 (Beta User)**

Select the Plan which fulfills your requirements in terms of resources provided by clicking on the **Select Plan** button.&#x20;

![Figure 4: Select Plan for Beta User](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/Bi3bWLrsLU5UbWVXTg5Q/image.png)

#### Step 5

Select the namespace in which you would like to deploy your Ai-WorkStation.

{% hint style="info" %}
**Note:** You have to be a member of a namespace to get the option to select a namespace.

Contact your OrgAdmin to add you in a namespace or, if you are an OrgAdmin, you can go to the namespace section and add the desired person as a member to a namespace.
{% endhint %}

![Figure 5: Select a Namespace](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/lKriSERpqxkbMZvDwRlH/image.png)

#### Step 6

Choose whether you want to mount your S3 bucket from our Ai-DataLake or not.

If yes, then select your bucketname from the dropdown.

![Fig. 6: Mount your S3 Bucket](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/WZdiSMrR9O3m2dFR5MrK/image.png)

#### **Step 7**

Enter the Notebook Name and finally spawn it as shown below. After successful creation, you will get your Notebook.

![Fig. 7: Name of Ai-WorkStation](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/T62LrEPNfx0DyaSFl5tm/image.png)


# Spawn MicroService

Step By Step Guide for Spawning a MicroService

### Overview&#x20;

Once you logged into the Zeblok Computational Application, you will get an option for **Spawn MicroService** as shown in the screenshot below.

![Figure 1: Dashboard](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/vN74OzI6E1mqC2tI1SKP/image.png)

#### **Step 1**

Click on "Spawn MicroService", you will be redirected to a page as shown below.

![Figure 2: Spawn MicroService](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/KOQCynGwhs9hULZACkYV/image.png)

#### &#x20;**Step 2**

Select the MicroService which you want to use, as shown below.

![Figure 3: MicroServices](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/KOQCynGwhs9hULZACkYV/image.png)

#### **Step 3**

Select the datacenter where you want to deploy it.

![Figure 4: Select DataCenter](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/yRBulBaecvNguR6f0d2Q/image.png)

#### **Step 4**&#x20;

If you selected an Edge Datacenter in the previous step, you have an additional step where you are given an option to choose whether you want your deployment to be created on the **HUB** or any **SATELLITE** Node.

![Figure 5: Select HUB or SATELLITE NODE](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/SHyc616ZFFP1grSlxx5N/image.png)

Select a Plan for your deployment. This step is common for both kinds of datacenters (EDGE and ENTERPRISE).

![Figure 6: Select Plan](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/Z68I4TQEXbRXF1gT8Qwm/image.png)

#### Step 5

Select the namespace in which you would like to deploy your Ai-WorkStation.

{% hint style="info" %}
**Note:** You have to be a member of a namespace to get the option to select a namespace.

Contact your OrgAdmin to add you in a namespace or, if you are an OrgAdmin, you can go to the namespace section and add the desired person as a member to a namespace.
{% endhint %}

![Figure 7: Select a Namespace](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/Oea2psscrRjH04RBR08a/image.png)

#### Step 6

This is a step given to you for configuring your microservice as you like.

**Ports:** The list of ports to be opened.

**Environment Variables:** Environment variables to be passed to the microservice container while starting.

**Arguments:** Arguments to be passed for the command parameter.

**Command:** Command to be passed to the microservice container.

![Figure 8: Configure your MicroService](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/0dr8U8Q0iDuQp9j0rSWx/image.png)

#### **Step 7**

Enter the MicroService Name and finally spawn it as shown below. After successful creation, you will be redirected to the Ai-WorkSpace and with your Spawned MicroService.

![Figure 9: Name your MicroService](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/aG1KwFHtgxyGutbMyrgY/image.png)

{% hint style="info" %}
To create you own micro-service and deploy it inside the AI-Microcloud please refer to the [Onboarding Microservice](/info/1.2.6/video-tutorial) tutorial.
{% endhint %}


# Spawn Orchestration Add-on

This service of the AI-Microcloud enables the user to spawn a Ray cluster which can be utilised for high performance computation using auto scaling.

Below are the steps required for the spawning of a RAY cluster inside a AI-Microcloud:

**STEP 1:**

For spawning an orchestration addon service first we have to got to the orchestration tab on the left hand menu

<div align="left"><figure><img src="https://lh7-us.googleusercontent.com/wR3BhlAFr-LawfCg118vT79Ee1ICPvS27bhr2Zt0r6gEvnaWCSaEE3OyMOW8Y2UGNE8vCBMDEl2nDS6q_a0PE65NnbQ0N9copHRyQPQiZHJPTmL9GMocMVs_GKQ83yiTUV6xJGe_DMxRNHZ2fdV01zo" alt="" width="188"><figcaption></figcaption></figure></div>

**STEP 2:**

Click on the “create orchestration addon” button on the right top corner as shown in the picture

<figure><img src="https://lh7-us.googleusercontent.com/7RKmR19PH1rInv713OLB8WHVnYGXtr9PD1Skrq7QVO19o7Nff71SiNsL8q7WkE3O6_mamDEdAobdJDNh9sdHahzoDtXJUuX3utn9m_De1WEM991gsiqIaCLBjHgDPxicyglTF11roQWJapZ0dFhsiP8" alt=""><figcaption></figcaption></figure>

**STEP 3:**

Fill in the form as required and click on the “add orchestration addon” button to create your own service

**STEP 4:**

After your service is created you will be able to see it in the list on your current tab. Next step is to go to the workspace by clicking the “workspace button” as shown in the picture below.

<figure><img src="https://lh7-us.googleusercontent.com/ZyD37nHm99FuFzB8V2ikY6KfNOoxXELxRTlekLwmSdVLuMraSgzf6jCv4DckSN0sAL7w5cU-txoLrDAeTKq0fc9KVJSr3nN_uXZw3w17kYZmhaiiusBzXRGMaTTtsX_6-2kqvfTzXf7l8kgTEVm6YrI" alt=""><figcaption></figcaption></figure>

**STEP 5:**

Click on the “spawn orchestration addon” button

<figure><img src="https://lh7-us.googleusercontent.com/SeLxm0m5yq8_Lbyl5ER68LOYi5UVViPHH08qSbOm_qVyiCcEwOPp6_GKF2I4XViG2CERDe5OKuxDp746poDePRypH684Bt45-2vvz7j0Uy7rQVk-2XnrfuAOiAo5lfzkClX4OESzZJ-WdC3Hh6-rwL0" alt=""><figcaption></figcaption></figure>

**STEP 6:**

* Select your service that you recently created
* Select your Datacenter
* Select a default plan or you can select a customised plan that you attached to you service at the time of creation
* Select a namespace you want to deploy your service on
* Give the values of minimum and maximum workers for your auto scaling purpose
* Give a name to your deployment

**STEP 7:**

After completing the above steps you can see the service spawning on your workspace under “Spawned orchestration Addons”. After that we can use the URL in your python code.

<figure><img src="https://lh7-us.googleusercontent.com/RdrsX0l4kZuo-AkT9Mle7HVFtIdIjQ5zbLVz7SqXkRq3Mnd3bBiloMS4W63WTCNMGG5n6cEOYk9NOC2nl7HwWmULJ34PirbZIbtLFyFU5JAwXd25nSrbvuMWvP_X7y5_8H6ZbxCfzAyGw-cvHR31zEg" alt=""><figcaption></figcaption></figure>

<br>


# Video Tutorial

The below tutorial walks you through all the detailed steps that are required for the spawning of any workstation or microservice into our MicroCloud

{% file src="/files/E4kEBGPWHO9wsf3mNBFd" %}
How to spawn a workstation or an Microservice
{% endfile %}

{% file src="/files/yt7R5kLRxqozZxdQIFFX" %}
How to spawn a Ray orchestration add-on service
{% endfile %}

{% file src="/files/5JZqWVijb3FhyheJNlmb" %}
How to check the monitoring for your resources
{% endfile %}

{% file src="/files/uAzKSx5pMXWIMH5aMcRf" %}
How to create you costume microservice and use it on AI-Microcloud
{% endfile %}


# FAQS


# Introduction

Introduction to Ai-APIᵀᴹ

### Overview

Ai-API™ makes moving trained ML models to production easy:

* Package models trained with ML framework and then containerize the model server for production deployment&#x20;
* Deploy anywhere for online API serving endpoints or offline batch inference jobs
* High-Performance API model server with adaptive micro-batching support
* Ai-API™ server is able to handle high-volume without crashing, supports multi-model inference, API server Dockerization, Built-in Prometheus metric endpoint, Swagger/Open API endpoint for API Client library generation, serverless endpoint deployment etc.
* Central hub for managing models and deployment process via web UI and APIs
* Supports various ML frameworks including:

Scikit-Learn, PyTorch, TensorFlow 2.0, Keras, FastAI v1 & v2, XGBoost, H2O, ONNX, Gluon and more

* Supports API input data types including:&#x20;

DataframeInput, JsonInput, TfTensorflowInput, ImageInput, FileInput, MultifileInput, StringInput, AnnotatedImageInput and more

* Supports API output Adapters including:&#x20;

BaseOutputAdapter, DefaultOutput, DataframeOutput, TfTensorOutput and JsonOutput

### Easy steps to Ai-AP&#x49;**™** Deployment

1. [Select your notebook](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/notebooks)
2. [Build Model](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/build-models)
3. [Deploy](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/deploy)

###


# ZBL Command Line Interface

## Install and Configure ZBL-cli in Jupyter notebook

Spawn a [Jupyterlab notebook](/info/1.2.6/spawn-workstation) and open it in the browser

Open the Terminal and perform the below procedures that are mentioned:

{% hint style="info" %}
Zeblok cli is used in the workstation to interact with AI-Microcloud for the purpose of model serving , pipeline and snapshot
{% endhint %}

#### Configure the command line interface with Zeblok account

```
zeblok configure <platformUrl> <datalake url> <datalakeSecret> <username>
```

**Platform URL**: Please refer to the image attached ![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/bO0E4kDphpp5KiIObMXt/WhatsApp%20Image%202023-07-26%20at%2019.27.55.jpg)

**Datalake URL**: Please contact the Zeblok Admin for this information.

**Datalake Secret:** Select the Kebab menu and go to the "Manage your Zeblok Account", then Click on the "Get Secret Key" Button and you can copy the alpha-numerical key under the "Ai-DataLake Secret Key" ![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/LvGFDsUPeTbYbzEJw7Q1/WhatsApp%20Image%202023-07-26%20at%2019.41.07.jpg) ![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/XzUHZ4xEFmTKUoNGuXcq/WhatsApp%20Image%202023-07-26%20at%2019.47.09.jpg)

**Username**: You can copy your user name from the same page you got your Datalake Secret from, Please follow the below picture ![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/0vX0Q5UnaD8IoAhDF3CV/WhatsApp%20Image%202023-07-26%20at%2019.54.14.jpg)

{% hint style="info" %}
When workstation is spawned this command is pre configured into your notebook with all configurations
{% endhint %}

#### Authentication of the Microcloud with the CLI

```
zeblok auth
```

<figure><img src="https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/wPHeBpvKDnKtKo0Qd1Cg/WhatsApp%20Image%202023-07-26%20at%2020.00.41.jpg" alt=""><figcaption><p>Once you enter the above command the cli will prompt for Access Key and Secret Key</p></figcaption></figure>

You can get both the credentials from the "Manage you Zeblok Account" option. Click on the "Get API Credential" button to reveal both the keys and the you can copy paste there from there.&#x20;

![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/7A1dS5JuLRWjgUZjJq70/WhatsApp%20Image%202023-07-26%20at%2019.41.07.jpg) ![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/0WgkEXa7EEw3YZk167YR/WhatsApp%20Image%202023-07-26%20at%2020.12.42.jpg)

After you have entered both the keys into the CLI after then you can easily use the CLI to Build you own Models or to serve pre installed models using the Zeblok command line.

Run the below command to check if the ZBL-CLI working

```
zeblok
```

<figure><img src="https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/Jjj9H9LmjQSRV6qPjeJr/Screenshot%202023-07-26%20205038.jpg" alt=""><figcaption></figcaption></figure>

> Once the initiation of any services like model serving is initiated try not to regenerate the access key and secret key again in profile tab to avoid failure in updates to app .


# How to use the CLI

This document will guide you through the usage of Zeblok cli

## CLI Usability and commands.

### Show-URL <a href="#showurl" id="showurl"></a>

This command just outputs the `APP URL` and `datalake Url` configured in zeblok configure command

```
zeblok showUrl
```

### Snapshot <a href="#snapshot" id="snapshot"></a>

This command is used to create snapshot of your workstation on which it creates a docker image whose tag is emailed to the user on which that tag can be used to create a new workstation with current configuration

```
zeblok snapshot
? Enter the name for docker file getting generated : <Docker Image Name>
? Select your DataLake Bucket to Deploy (Use arrow keys) <Minio Bucket Selection>
```

#### Brief <a href="#brief" id="brief"></a>

Snapshot command copy all the files from your notebook with the same structure as in current one with that it also creates requirments.txt with all the installed packages in your current notebook and installs it when you spawn the new workstation with that docker image to have same configuration as you have currently .

> requirments.txt is generated automatically with `pip list --format=freeze`
>
> Base image for workstation used is `minimal-notebook:2023.09.20`

#### Components <a href="#components.2" id="components.2"></a>

1. `Docker Image Name`- The image name you want the docker to have
2. `Minio Bucket Selection` - Select the bucket where you want to store all the data of your notebook

### Openvino <a href="#openvino" id="openvino"></a>

This command is used to serve model using openvino

```
zeblok openvino
? Enter the path for generated IR model (without / at the end): <IR_OUTPUT_PATH>
? Enter the IR output name : <IR_OUTPUT_NAME>
? Select your DataLake Bucket to Deploy : <BUCKET_NAME>
? Do you want to auto-deploy? : <AUTO_DEPLOY>
? Select your namespace: <NAMESPACE>
? Select your DataCenter: <DATACENTER>
? Select your Kiosk: <KISOK>
? Select your Plan: <PLAN>
? Name of your Deployment: <DEPLOYMENT_NAME>
```

#### Components <a href="#components.3" id="components.3"></a>

1. `IR_OUTPUT_PATH` - Folder containing the \<IR\_OUTPUT\_NAME>.xml and the \<IR\_OUTPUT\_NAME>.bin
2. `IR_OUTPUT_NAME` - IR output name which is same for both .xml and .bin file in the `IR_OUTPUT_PATH`
3. `BUCKET_NAME` - Select the bucket where you want to store the model files
4. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
5. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
9. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

#### Ideal File Structure <a href="#ideal-file-structure" id="ideal-file-structure"></a>

![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/fSWbZU8gAjaKAonOEli1/image-20231101-153215.png)

> For openvino model serving to work the output path must contain 2 files with same name with extensions \*.xml and \*.bin

### Bentoml <a href="#bentoml" id="bentoml"></a>

Bentolml model serving serves a bentoml model served built using `bentoml build` command . It fetches the model with `bentoml list  --output json` command and lists one which you want to serve .

```
zeblok bentoml
? Select your Model to Deploy: <MODEL_NAME>
? Select your DataLake Bucket to Deploy : <BUCKET_NAME>
? Do you want to auto-deploy? : <AUTO_DEPLOY>
? Select your namespace: <NAMESPACE>
? Select your DataCenter: <DATACENTER>
? Select your Kiosk: <KISOK>
? Select your Plan: <PLAN>
? Name of your Deployment: <DEPLOYMENT_NAME>
```

#### Components <a href="#components.4" id="components.4"></a>

1. `MODEL_NAME` - Select the model built using the bentoml build command `bentoml build`
2. `BUCKET_NAME` - Select the bucket where you want to store the model files
3. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
4. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
5. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

> The model serving of bentoml needs bentoml installed on your workstation
>
> If there is no model to select in first question then try running `bentoml build` in the model creation .

### Mlflow <a href="#mlflow" id="mlflow"></a>

Mlflow model serving uses two process to serve a model first is to get model into your directory and second one is to serve that model

#### Commands <a href="#commands" id="commands"></a>

**1. Get model**

To get a model from mlflow register use command

```
zeblok mlflow
? Enter the mlflow url for model : <MLFLOW_TRACKING_URL>
? Enter the runId for model : <RUN_ID>
```

**Components**

1. `MLFLOW_TRACKING_URL` - Mlflow tracking URL where your model is stored to .
2. `RUN_ID` - Run id of the model you are willing to serve

To create a new mlflow microservice please refer to documentation of AI-Microcloud .

**2. Serve Model**

Once the command To get the model is done you will need to run modelserve command to serve model

```
zeblok modelserve
? Enter the rootPath for model in directory : <DOWNLOADED_MODEL_PATH>
? Enter the IR output name : <IR_OUTPUT_NAME>
? Select your DataLake Bucket to Deploy : <BUCKET_NAME>
? Do you want to auto-deploy? : <AUTO_DEPLOY>
? Select your namespace: <NAMESPACE>
? Select your DataCenter: <DATACENTER>
? Select your Kiosk: <KISOK>
? Select your Plan: <PLAN>
? Name of your Deployment: <DEPLOYMENT_NAME>
```

**Components**

1. `DOWNLOADED_MODEL_PATH`- Enter folder name where your model is stored .
2. `IR_OUTPUT_NAME`- Enter any name that you want to put for model .
3. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
4. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
5. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

{% hint style="info" %}
The model serving of mlflow needs mlflow installed on your workstation
{% endhint %}

### LLAMA <a href="#llama" id="llama"></a>

This command serves LLAMA model with CPP serving .

```
zeblok llamacpp
? Enter the path for generated IR model (without / at the end): <IR_OUTPUT_PATH>
? Enter the IR output name with its extention : <IR_OUTPUT_NAME>
? Select your DataLake Bucket to Deploy : <BUCKET_NAME>
? Do you want to auto-deploy? : <AUTO_DEPLOY>
? Select your namespace: <NAMESPACE>
? Select your DataCenter: <DATACENTER>
? Select your Kiosk: <KISOK>
? Select your Plan: <PLAN> 
? Name of your Deployment: <DEPLOYMENT_NAME>
```

#### Components <a href="#components.7" id="components.7"></a>

1. `IR_OUTPUT_PATH`- Enter the path where your model and `requirements.txt` file is situated .
2. `IR_OUTPUT_NAME` - Enter the model name with its extension whether its .gguml or .gguf
3. `BUCKET_NAME` - Select the bucket where you want to store the model files
4. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
5. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
9. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

> `IR_OUTPUT_PATH` must contain the model and `requirements.txt` file to work
>
> Make sure you enter `IR_OUTPUT_NAME` with its extension .
>
> Depending on the size of model it will take time around 2 to 3 hours

### VLLM <a href="#vllm" id="vllm"></a>

This command serves model with Vllm model serving .

```
zeblok vllm 
? Enter the directory name containing your model : <MODEL_DIRECTORY> 
? Select your DataLake Bucket to Deploy : <BUCKET_NAME> 
? Do you want to auto-deploy? : <AUTO_DEPLOY> 
? Select your namespace: <NAMESPACE> 
? Select your DataCenter: <DATACENTER> 
? Select your Kiosk: <KISOK> 
? Select your Plan: <PLAN> 
? Name of your Deployment: <DEPLOYMENT_NAME>
```

#### Components <a href="#components.8" id="components.8"></a>

1. `MODEL_DIRECTORY`- Enter the folder name where your model and files are situated inside the workstation .
2. `BUCKET_NAME` - Select the bucket where you want to store the model files
3. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
4. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
5. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

> Make sure `MODEL_DIRECTORY` you enter contains all the files related to model .
>
> Depending on the size of model it will take time around 1 to 2 hours


# Installing different frameworks

All the below commands will be installing the latest versions, for a particular version please follow the below syntax

#### Below Commands are also for utilization with Zeblok CLI

To Install Zeblok MLflow

```
pip install mlflow==2.5.0
```

To install Zeblok BentoML

```
pip install bentoml==1.0.25
```

To install Zeblok OpenVINO

```
pip install openvino==2023.0.0
```

#### Below command are utilized for installing frameworks on Minimal Notebook

To install any other packages

```
pip intsall {package_name}=={Specific version if any}
```

To install any Requirment.TXT

```
pip install -r $PATH/requirment.txt
```

To update any package

```
pip install -U {package_name}=={Specific version if any}
```


# Notebooks

Ai-APIᵀᴹ Engine: Notebooks

### Selecting a Notebook

Here, as an example, we are selecting the BentoML Notebook. You can find it using the search field on the Spawn Ai-WorkStation Page.

{% hint style="info" %}
**Note:**

The full walkthrough of spawning an Ai-WorkStation has been given at our [Spawn WorkStation Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation) for your convenience.
{% endhint %}

![Figure 1: BentoML Notebook](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/8rIG2xWl4ZlxszOKYRaJ/image.png)

Taking BentoML as the Notebook and following all the steps from the Spawn Workstation Guide will give you an Ai-WorkStation ready to open.

{% hint style="info" %}
**Note:**

The final result of this example will get us a notebook which can identify the breed of an animal upon uploading the image of an animal.
{% endhint %}

Next Step is to start and open the notebook and run all cells to get a newly trained model.

![Figure 2: Run all Cells](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/RGFB8BZyNvdfJFflyQpP/image.png)

![Figure 3: Name of newly Trained Model](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/MwDjo8Li2VWS2QxjVLjP/image.png)


# Build Models

Ai-APIᵀᴹ Engine: Build Models

### Building Models Guide

Before starting to read this guide, it is recommended for you to read the[ Notebook Section](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/notebooks) of the Ai-API Concept.

After creating a newly trained model, comes the building stage.

For building process, the steps are as following:

* Open the integrated terminal that comes along with the notebook.

![Figure 1: Click on New Launcher](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/yiHmfwrXdrSDS0gaRqPN/image.png)

![Figure 2: Integrated Terminal](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/QdEJZO65BFW280oRYPno/image.png)

* Update the Cli ( Command Line Interface) for smooth process running.

```
npm i -g zbl-cli
```

![Figure 3: CLI Update](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/Hxr856mWhIYFQN76t2ep/image.png)

* Configure your zeblok cli

```
zeblok configure
```

![Figure: Zeblok Configure](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/khvUsoZEovP61PMCnQO8/image.png)

* Run the command **zeblok auth** and enter your username and password&#x20;

```
zeblok auth
```

![Figure 4: Authentication Command](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/2VSULox8w8f8QreFYsEn/image.png)

* After successful authentication, run the command **zeblok runtime** which fetch the latest created by you and give a list of the models from which you can select the model you would like to deploy.

```
zeblok runtime
```

* Select the model and hit enter. The terminal will package your model and upload it to the database. This might take a minute or two.

![Figure 5: Model Selection (Runtime Command)](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/frO7I686dQ6s7YDsrX52/image.png)


# Deploy

Ai-APIᵀᴹ Engine: Deploy

### Deploying Models Guide

Before starting to read this guide, it is recommended for you to read the[ ](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/notebooks)[Build Models Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/build-models) of the Ai-APIᵀᴹ Concept.

After building a newly trained model, comes the deploying stage.

Now this is the part where our Ai-APIᵀᴹ Engine comes into play. The sidebar at the left side of your screen has a menu button of Ai-APIᵀᴹ which will lead you to our Ai-APIᵀᴹ Engine.

![Figure 1: Ai - Apiᵀᴹ Engine](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/hWtV0DsiJWiFfrDvdzCL/image.png)

{% hint style="info" %}
**Note:**

The Ai-APIᵀᴹ Engine, on clicking, shows all the previous deployments you have done, or your organization has done (if you are an Organization Admin) after selecting a specific namespace of the deployments.
{% endhint %}

### For deploying process, the steps are as following:

* Click on Create Ai-APIᵀᴹ and then select the model. Here we are selecting the model which we just created in the previous Guide.

![Figure 2: Create Ai-Apiᵀᴹ](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/tC1whhxRSLVCakKRpm6k/image.png)

![Figure 3: Select Trained Model](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/LxKOiv6UXIqxAnZEXaMI/image.png)

* Then comes the selection of namespace (only if you are a member of one).

![Figure 4: Namespace Selection](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/t2FqngRBQUrYHlQqP4ps/image.png)

* Third step is to select the location where you want to deploy it.

![Figure 5: Select DataCenter](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/Eu8PATw8IAKWLPsXdaoa/image.png)

* If you selected an Edge Datacenter in the previous step, you have an additional step where you are given an option to choose whether you want your deployment to be created on the **HUB** or any **SATELLITE** Node.&#x20;

![Select HUB or SATELLITE NODE](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/i0eYVPA5a4gwWJO8NSID/image.png)

* Name your Deployment and click on Create.

![Figure 6: Name of Deployment](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/ltbNmNxsIzGe72GfJkK3/image.png)

You will be redirected to our Ai-APIᵀᴹ Engine while the deployment is being done in the background. On successful deployment, the status of the deployment will change to **DEPLOYED.**&#x20;

{% hint style="info" %}
**Note:** On successful deployment, when the status is deployed, you are now given an option to monitor various performance metrics as highlighted in the images below.
{% endhint %}

![Figure 7: Deployment Successful](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/fdMeZjsrR7IgKn7xQNfm/image.png)

![Performance Monitoring](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/aUs012oG1rTSlM6R9B42/image.png)


# DataLake

Enabling Accelerated Data Management, Data Engineering and AI Pipelines

### Overview

A data lake is a centralized repository that allows you to store all your structured and unstructured data at any scale. Zeblok Ai-Data Lake is a high-performance data-store that allows you to import, filter, and instantly analyze objects. Our solution is designed for performance, scales up with your data, and can provide industry-grade SSL security and data-redundancy for high availability of data at SSD speeds.

### Seamless accessibility from almost anywhere

Zeblok Ai-Data Lake handles the tasks of data pipe-lining, analysis, and propagation so that you can focus on what matters most. Whether you are ingesting images, video data files coming from IoT sensors at Edge locations through 4G/5G low latency network or uploading large CSV files, Zeblok Ai-Data Lake has you covered, with unprecedented data acceptance, performance and compatibility.

Easily automate your imports, with large files using various methods such as: Browser-based portal, Zeblok Magic Commands, S3 REST API, Data Lake drag-and-drop native Windows App, and HTTP importing.

&#x20;

![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/1wkADhDEq9p1NvMrYWwo/image.png)

### Data Browser Portal:

Zeblok Ai-Data Lake provides secure high-availability of your files and objects across a cluster of servers. Authorized users can access and manage all their data in one place through the convenience of the Data Browser Portal. The Browser Portal can securely allow a user to set permissions and upload/download/edit data of various file types and sizes. Users can see a map of files in their bucket without touching a command line.

![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/8UpyJoXRaULeXsAhwJIx/image.png)

### Zeblok Magic Commands:

Zeblok's Magic Commands are ubiquitously available in every Zeblok notebook instance to allow users easy access to a reliable object storage solution. With Magic Commands, users have an array of options that allows for quick and easy way to add blazing fast storage to virtually any network. Magic Commands are intuitive, especially for those familiar with the common  Linux/Unix file system. The command line offers users the ability to create new files, delete old ones, create new folders, share access, and more.

![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/FFKxwy7gFcjEYrkFuxOB/image.png)

### REST API:

Inspired by the S3 protocol originally from AWS, Zeblok's Ai-Data Lake provides a secure endpoint that enables users to programmatically upload and manage files using a REST API. The generic S3 REST API offers a unified interface for interacting with any object and provides high-performance uploads and file transfers that can be scheduled or automated between Zeblok notebook instances or external hosts (such as via cron jobs).

![](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/f67fAAUcfJ2uLzblP9Wc/image.png)

### HTTP Source:

Zeblok Ai-Data Lake also allows users to upload and download files from various HTTP sources without re-downloading files on the local machine. This space-saving method enables users to skip steps between upload and download cycles as desired.

### Use the Ai-Data Lake within the Ai-WorkStation Notebook:

Access your data files residing in the Ai-Data Lake within the Ai-WorkStation notebook using BlazingSQL engine that runs on GPUs

### Blazingly fast queries with big data\*:

Run big data analytics across Zeblok Ai-Data Lake using our query-in-place GPU enhanced services. Perform blazing fast queries (up to 8x faster\*) with SQL expressions and use our Zeblok AI algorithms to analyze data that is stored across your private Ai-Data Lake account across various notebooks. Export queries back to Ai-Data Lake or generate customization visual reports with ease.​&#x20;

### Data Lake Security:

The Zeblok Ai-Data Lake platform is designed to be scalable and easy to use with a granular access control system where each user only has access to their own files. The platform features implementations for data encryption both in-transit and at-rest. With recommended SSL certificates installed, the platform offers standard bank-level encryption which is 256-bit AES, the standard for advanced cryptography. The encryption standards available in the Data Lake platform protects your data from being intercepted by third parties. Furthermore, the REST API endpoints are hardened to only operate on pre-provisioned key/secret pairs.


# Tutorials

Ai- DataLake Tutorials and Commands

### Overview

Zeblok Datalake is a high-performance data-store, compatible with the S3 protocol, intended for secure high speed data transfer. As an object store, Zeblok Datalake allows users to read and write large amounts of unstructured data such as photos, videos, log files, spreadsheets, CSV files, etc. Datalake is cloud native and supports GPU-optimized queries through the addition of BlazingDB.

With a robust and simple online interface, API CRUD access, in-built Zeblok CLI magic commands, and Python integrations, users can instantly run complex AI related queries for a variety of datasets, visualize the results, and share/revoke reports with clients.

### Zeblok CLI

#### Get the Latest Version Zeblok CLI using Below Command

{% tabs %}
{% tab title="Code" %}

```
npm i -g  zbl-cli
```

{% endtab %}

{% tab title="Output" %}

```
ERROR! Session/line number was not unique in database. History logging moved to new session 6
/opt/conda/bin/zeblok -> /opt/conda/lib/node_modules/zbl-cli/index.jserial remove 10yan/.npm/_lock
+ zbl-cli@1.1.9
updated 1 package in 4.359s
```

{% endtab %}
{% endtabs %}

**Configure the Zeblok CLI**

![Figure: CLI Configure](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/ZPasebcub9JuEDtQq8Va/image.png)

#### Set DatalakeUrl

```
zeblok setUrl http://18.189.16.253:9000
```

#### Login using Zeblok CLI

To login using Zeblok CLI open terminal from Jupyterlab environment and type the below command.

{% hint style="info" %}
**Note:**

SecretKey and Username are avaialable on Zeblok Computational Dashboard "Manage your Zeblok Accounts" Page
{% endhint %}

{% tabs %}
{% tab title="Code" %}

```
zeblok login <username> <secret key>
```

{% endtab %}

{% tab title="Output" %}

```
  _____         _       _           _        ____            _             _           _           
 |__  /   ___  | |__   | |   ___   | | __   |  _ \    __ _  | |_    __ _  | |   __ _  | | __   ___ 
   / /   / _ \ | '_ \  | |  / _ \  | |/ /   | | | |  / _` | | __|  / _` | | |  / _` | | |/ /  / _ \
  / /_  |  __/ | |_) | | | | (_) | |   <    | |_| | | (_| | | |_  | (_| | | | | (_| | |   <  |  __/
 /____|  \___| |_.__/  |_|  \___/  |_|\_\   |____/   \__,_|  \__|  \__,_| |_|  \__,_| |_|\_\  \___|


Added `zb` successfully.
```

{% endtab %}
{% endtabs %}

#### List all the Files and Directory on Datalake

{% tabs %}
{% tab title="Code" %}

```
zbl tree -f zb/datalake/<username>/
```

{% endtab %}

{% tab title="Output" %}

```
zb/datalake/akash/
├─ FL_insurance_sample.csv
├─ ZeblokReadme.ipynb
├─ algebra.log
├─ main.go
├─ sales.csv
├─ sample_taxi.csv
└─ docs
   ├─ MAINTAINERS.md
   ├─ minio-admin-complete-guide.md
   ├─ minio-client-complete-guide.md
   ├─ minio-client-configuration-files.md
   └─ zh_CN
      ├─ CONTRIBUTING.md
      ├─ minio-client-complete-guide.md
      └─ minio-client-configuration-files.md
```

{% endtab %}
{% endtabs %}

#### Copy file from DataLake to local Notebook Directory

```
zbl cp zb/datalake/<username>/<filepathOnDatalake> <filepathOnNotebookStorage>
```

Example is given below:

{% tabs %}
{% tab title="Code" %}

```
zbl cp zb/datalake/akash/main.go main.go
```

{% endtab %}

{% tab title="Output" %}

```
...h/main.go:  979 B / 979 B ┃▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓┃ 29.49 KiB/s 0s
```

{% endtab %}
{% endtabs %}

#### Copy file from Local Notebook Directory to Datalake

```
zbl cp <localfilePath> zb/datalake/<username>/<datalakeFilePath>
```

Example:

{% tabs %}
{% tab title="Code" %}

```
zbl cp ZeblokReadme.ipynb zb/datalake/akash/
```

{% endtab %}

{% tab title="Output" %}

```
...dme.ipynb:  54.33 KiB / 54.33 KiB ┃▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓▓┃ 1.29 MiB/s 0s
```

{% endtab %}
{% endtabs %}


# Datasets

Zeblok Object Storage

Now our users can easily onboard their data onto the platform using few simple steps that are explained below.

The below steps will allow the user to simply drag and drop their content and after the upload it can easily be used inside the workstation and microservice that are spawned.

### STEPS TO UPLOAD:

* [ ] Click "Datasets"
* [ ] Click "Create new Datasets +"
* [ ] Click the "Enter Dataset Name" field
* [ ] Type in a name
* [ ] Click the "Enter Dataset Description" field
* [ ] Type in a description
* [ ] Click "Create"
* [ ] Go to the Dataset you just created and click the "View" button
* [ ] Drag and drop data that you want to upload into your platform bucket and attach it to your workstation or microservice
* [ ] Click on the "Upload Files"

Following the above steps will allow you to populate the Object storage that the user create on the platform.&#x20;

The below video depicts the whole workflow from creation of a dataset to attaching it into a workstation, microservice or Ai-API

{% file src="/files/6Wu31SVFBXbSfUvbxCvH" %}


# Monitoring

Centralized Orchestration Manager

### Overview

Ai-MicroCloud™ Manager is the centralized management utility for Ai-MicroCloud™ and is used to manage and Orchestrate all dependent components for Ai-WorkStation, Ai-Data Lake, Intelligence Marketplace and Ai-API™ engine.

The Ai-MicroCloud™ Manager enables the Enterprise Administrator to define role-based access control, infrastructure plans (vCPUs, GPUs, memory, storage), define Namespaces and add accessible data centers, and provides metering information for resource utilization for billing or charge back purposes.

### System Monitoring:

#### Dashboard:

View notebooks and analytics, including a graph of notebooks previously spawned and usage statistics, followed by all the notebooks available within the organization.

![Figure 1: Dashboard](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/d9Vfz7yCKUVVpShGpdzf/image.png)

By clicking on **View Analytics Button,** you will be redirected to the activities monitoring page, where if you are an Organisation Admin, you can view the activities and statistics for resource usage and everything related of all Organisation users.

![Figure 2: Activities Monitoring Page](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/NAOhxUzkNraEihamDeGP/image.png)

### <br>


# Resource level monitoring

We have enhanced our monitoring system to such a level that provides a clear view of all the resources that are utilized in our platform.

Our platform portrays the graphical representation of utilization on a node and pod level, the resources that are captured are shown below:

* CPU
* Memory
* Disk

We have a detailed video of how to utilize and navigate to the monitoring part attached below, we recommend you to please have a look into this depiction for a detailed understanding of the usage

{% file src="/files/6FHhiu5KJj6Cz9qwm4ua" %}


# Intelligence Marketplace

Carefully Selected ∙ Rigorously Tested ∙ Enterprise-Ready Proven, original algorithms – easy to read, use and share

### Overview

Zeblok’s Intelligence Marketplace provides easy access to a growing library of proven, original third-party AI algorithms. Quality is ensured by our curation process, including closed loop validation, providing algorithm creators with a means of commercialization not previously available. We ensure that algorithms are easy to read, easy to use and easy to share. These include:

{% file src="/files/-MedfSC1IZsWkFTMW-eX" %}
Intelligence Marketplace
{% endfile %}

### **Ai-Rover™ – Explainable AI Notebook**

#### **Multi-variate, high dimensional data comprehension**

AI systems tend to operate in the darkness of black boxes. Input data is transformed into decisions without much human-readable justification. The journey from data to insights requires a crucial data comprehension stage, so the direction of an AI/ML model is fully explainable. Omitting this stage may produce a result that is not actionable, causing the AI project to dead-end.

Ai-Rover™ is the full implementation of an explainable AI algorithm on a virtualized notebook, in concert with Zeblok's GPU-powered data lake, Edge connectivity and other components.  Ai-Rover™ discovers and visually explains patterns in complex datasets as well as the causal relationships underlying those patterns, supporting data analysts in the construction of trust-able decision-making AI models. Domain agnostic Ai-Rover™ is particularly useful for large, multi-variate, high dimensional data analysis. Ai-Rover™ enables the crucial data comprehension phase to properly target the direction of an AI project.

Say goodbye to tedious data exploration and instead gain quick access to the hidden information in your data with a simple visual interface that enables users to intuitively derive subpopulations of data attributes, leading to better predictive insights.

[Learn More...](https://854a0df5-7a21-4391-b1e4-c279d3cc5b86.filesusr.com/ugd/dc718d_dc7309f63872419395abe25463fce115.pdf)                                                                                                       [Use Cases](https://www.computational.zeblok.com/biotech-and-pharma)            &#x20;

### Ai-Rover™ Notebook For Time Series Data

#### Time series data forecasting & anomaly detection

Ai-Rover™ Notebook For Time Series Data is a value framework to automate predictive model building that creates human-readable models from historical time series data.

These models provide users with high-quality explainable forecasts and anomaly detections, creating business value in use cases across industries, containerized for easy incorporation into your AI/ML model.

The framework is built on a field of mathematics called information geometry, an interdisciplinary field that uses differential geometry techniques to study probability theory and statistics. It enables model building which includes business focus, aggregates, and key performance indicators (KPIs). It can help you identify the value of the predictive analytics business use cases that you want to implement.

Typical use cases and business applications:

* Demand/capacity prediction
* Predictive asset management
* Fraud/anomaly detection
* Marketing/social analysis
* Pricing optimization

[Learn more](https://www.computational.zeblok.com/airoverfortimeseries).

### Ai Video-Analytics-as-a-Service

#### Near real-time Ai Video-Analytics

A robust framework that enables development and implementation of AI-powered video analytics solutions. It accommodates video feeds in a variety of formats & resolutions, ranging from a few cameras to thousands of cameras; best in class annotation tools to generate unlimited number of datasets with precise guidelines and complex ontologies to significantly reduce labeling time and an inference engine to integrate your production output into your enterprise application from Core to Edge using RESTful API.

Offer Video-Surveillance-as-a-Service by developing bespoke AI models to a variety of clients responsible for monitoring facilities, such as schools, highways and public spaces to identify vandalism and other suspicious behavior, monitor and analyze traffic patterns, identify traffic violations to providing Quality audits for manufacturing processes in automobile industries.

Enterprise applications include:&#x20;

* Intrusion Detection
* Suspicious Activity
* Traffic & Parking Management
* Smoke & Fire Detection
* Crowd Counting
* Vehicle Identification
* Non-Invasive Body Temperature Monitoring
* Dwell Time
* Safety gear monitoring – Hardhats, safety goggles, masks

[Learn more](https://www.computational.zeblok.com/videoanalytics).  [Solution Brief](https://854a0df5-7a21-4391-b1e4-c279d3cc5b86.filesusr.com/ugd/dc718d_cc067581312d4bfb9afb2c666e4ce12c.pdf).

### Quantum Entropy-as-a-Service

#### Quantum entropy for a connected world

Zeblok provides quantum-safe security via container, with both high throughout and high entropy density, using QNu's Qosmos™ quantum random number generator , which uses device-generated random numbers, wherein the randomness is guaranteed by the laws of quantum mechanics. Zeblok's Quantum Entropy-as-a-Service (QEaaS) provides truly random numbers, delivered via container on Ai-MicroCloud™ to the network security layer, operating systems, embedded systems or at the network edge, providing a seamless upgrade from computational security posture to information provable security.

The high throughput, low cost of upgradation and ease of integration makes this a very cost-effective and simple-to-deploy solution over companies' existing infrastructure.

The architecture is scalable, provides load balancing, and has active failover.

[Learn more](https://www.computational.zeblok.com/quantumsecurity).   [Solution Brief](https://854a0df5-7a21-4391-b1e4-c279d3cc5b86.filesusr.com/ugd/dc718d_522ca639890e431e8fe444f426c71253.pdf).

​


# Manage Account

Account Security Mechanisms

This article will guide you through our [Resetting Password Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/more/manage-account/forgotpassword) and [2 Factor Authentication Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/more/manage-account/2-factor-auth).

{% hint style="info" %}
**Note:**

Enabling 2 Factor Authentication is an optional security measure you can avail, however we recommend you to enable this for better security of your account.
{% endhint %}


# Forgot Password

Guide for resetting password

If you are not able to login to your account, because you forgot your password, don't worry as this guide will take you through the process of resetting your password step by step.

![Figure 1: Forgot Password](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/w4wH3q0okPoqBFrY7q75/image.png)

1. Click on the Forgot Password link above the Sign In Button, and you will be redirected to our [Forgot Password Page](https://app.zbl-aws.zeblok.com/forgotpassword).

![Figure 2: Enter Valid Email Id](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/L4FJJfL9OsVnzJDq7F57/image.png)

You will then receive an **Email** on your **Email-id** you entered in the forgot password link as shown in above image.

{% hint style="info" %}
**Note:**

To receive a password reset link in your registered email id, you must have your account registered first with our Zeblok Computational Platform first.
{% endhint %}

![Figure 3: Email sent to your Email-id](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/yrGr44HFdsW9RnzZvlG8/image.png)

2\. Click on the Link option sent in your email and you will be redirected to a page and to enter New Password and after that click on the **Reset Password** button.

![Figure 4: RESET PASSWORD](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/MfL6V1WhivkJnSB0nOKl/image.png)

After that you will see this notification **Password updated successfully please login to continue.**

Then You can Login with the New Passwor&#x64;**.**


# 2 Factor Authentication

2 Factor Authentication Guide

### Toggle 2 Factor Authentication

Enter the login credentials in the [Sign In](https://app.zbl-aws.zeblok.com/), page then you will be redirected to dashboard page.

![Figure 1: Dashboard Page](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/YkZLlmlatCsOcgG0lbW9/image.png)

At the rightmost top-corne&#x72;***,*** click on three dots and you will see a dropdown menu then at the bottom click on ***2-fa and your 2 factor Authentication will be enabled.***

![Figure 2: Toggle 2 Factor Authentication](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/NpXuvb9F3X1EjTgaZEl1/image.png)

{% hint style="info" %}
**Note:**

Enabling 2 Factor Authentication will have an effect on the sign in process starting the next time anyone tries to sign in to your account.
{% endhint %}

### Sign In using 2 Factor Authentication

#### Step 1:

Enter your credentials and click on sign in button.

![Figure 3: Sign In](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/TprejdQRaUXES79MDDZl/image.png)

#### Step 2:

As you can see, an OTP will be sent to your registered E Mail Id which you will have to enter to successfully login to your account.

![Figure 4: 2 Factor OTP](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/hEEJfKZ0j16FnW3O9Fmq/image.png)

![Figure 5: OTP Email](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/2mllPMG4atbaPakLJ8Se/image.png)

{% hint style="info" %}
**Note:**

As mentioned above in the images, the validity of OTP is only 5 minutes. You will have only 4 attempts to enter a valid OTP, after which your account will be banned for signing in and you will have to contact the Zeblok Administrator for unblocking your account.
{% endhint %}


# IAM

IDENTITY ACCESS MANAGEMENT

### Overview

IAM is a user entity which we create in **Zeblok Computational Platform** to represent a person that uses it with limited access to resources.

![Figure 1: IAM (Identity Access Management)](https://924165660-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F1uv6074cgUfxr5s1gsAU%2Fuploads%2FzTwQMPLrE3bjseTwqre1%2FMicrosoftTeams-image%20\(1\).png?alt=media\&token=c86c1431-2490-47e3-a702-d152012e1963)

As you can see, we have 3 sections for defining user permissions and recourse management in the IAM page.

* [Roles](https://computationaldocs.zeblok.com/zeblok-computational-1/more/iam/roles)
* [Usergroups](https://computationaldocs.zeblok.com/zeblok-computational-1/more/iam/usergroup)
* [Resources](https://computationaldocs.zeblok.com/zeblok-computational-1/more/iam/resources)

{% hint style="info" %}
**Note:**

Only the user who has an admin access, gets access to IAM Tab in the Sidebar.
{% endhint %}


# Roles

IAM: Roles

### Overview

The Identity and Access Management (IAM) module in AI MicroCloud is designed to provide comprehensive control over user access, utilising three key components.

*Assignment of Policies:* IAM allows the assignment of policies to users through the Roles section. These policies either grant privileges or impose restrictions on user activities, ensuring controlled access to AI MicroCloud resources.

Here are few pre-defined roles available in the platform:

**Basic Access:** Offers the most limited level of access.

**Developer Role:** Tailored for developers with specific access.

**Product Role:** Provides access related to products.

**Playground User Role:** Custom role for users accessing the playground.

{% hint style="info" %}
**Note:**

To know more about the sign up process for the user role and access, follow our [Create An Account Guide for Individual User](https://computationaldocs.zeblok.com/zeblok-computational-1/create-an-account/individual-user).
{% endhint %}

{% hint style="info" %}
*Role-based Menu Restrictions:* Developer and Product roles may have specific menu restrictions, ensuring a tailored and controlled experience for users in these roles.
{% endhint %}


# Usergroup

IAM: USERGROUP

### Overview

A usergroup is a set of users who have the same permissions as the policies/ permissions are assigned to a usergroup in which the users get assigned.

***Organised Access:*** IAM enables the organisation's admin to create User Groups, streamlining access management.

***Role Assignment:*** Admins can assign roles within User Groups, collectively defining access levels for groups of users.

***Invitation and Access Control:*** The organisation's admin can invite individuals, assign roles, and manage access collectively through User Groups.

When the [resources](https://computationaldocs.zeblok.com/zeblok-computational-1/more/iam/resources) are created, they are given access to certain usergroups in the platform and all the members of these usergroups get access to the resources collectively.


# Resources

IAM: RESOURCES

### Overview

This section encompasses key resources within AI MicroCloud, including workstations, microservices, orchestration, and add-ons.

***Role-generated Policies:*** Roles established in the IAM module generate policies specific to these resources, dictating user access and permissions.


# Admin Guide

Admin Manual for mastering Zeblok Ai-MicroCloud


# Menu

The first view of the SideNav Menu after logging in via the Admin account gives the feeling of a wide range of options and authority over the Ai-MiroCloud.

This guide is made for you to understand all the features and control that an Admin has, and also how to own the Ai-MircoCloud.

![Fig 1: Zeblok Ai-MicroCloud Landing Page](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/2NKAmGbtgDBqO4swCKGQ/image.png)

[Dashboard](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/dashboard)

[Workstations](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/workstations)

[IAM](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/iam-identity-access-management)

[Organizations](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/organizations)

[Plans](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/plans)

[Namespace](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/namespaces)

[Data Center](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/datacenters)

[MicroServices](https://computationaldocs.zeblok.com/zeblok-computational-1/more/admin-guide/microservices)

[Ai-API Engine](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/introduction)

You can click on any of the names above to know more in details about the specific section.

Also, you can refer to IAM page under Mode Section of this documentation to get a better idea about all the roles and their accessibility and limitations.


# Dashboard

An Intelligent visual view of your data

The OrgAdmin Dashboard only shows the metrics generated by their organization whereas SuperAdmin Dashboard will show you the metrics generated by all organization in one place alongwith an option to see only the metrics generated by a specific organization.

To see a glimpse of the Dashboard, you can visit the **Monitoring page** under Data and Metrics Section of this documentation.


# WorkStations

Enabling Zero Learning Curve, Open-Source, Virtualized Notebooks, Curated Algorithm Notebooks, Model Zoo Notebooks

To get a deep insight and understanding of our Ai-WorkStation, refer to our [website](https://www.computational.zeblok.com/aiworkstation).

![Fig. 1: Public WorkStations](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/vnnRZeBLIeENbgVGDbw0/image.png)

This section shows a list of **containers** which have already been brought to the Ai-MicroCloud and are ready to be spawned by the user using the steps mentioned in **Spawn Ai-WorkStation Guide** under our Quick Start Section of the documentation.

**Create WorkStation**

![Fig. 2: Create WorkStation](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/WuDjkX0z7BGDGPA1fB5J/image.png)

In Fig 1. You can see the Create New WorkStation Button which opens a dialog box shown in Fig. 2.

Note: This Is the screenshot of adding a container from a private Repository too by providing the required fields as shown.

The following are the definitions for the fields shown in the Create WorkStation form.

**Resource Name** => The name of the WorkStation you would like to give.

**Image Tag** => The Image Name along with tag of the docker container.

**Image Run Command** => The default RUN Command you want to execute at the start of the workstation (OPTIONAL).

**Private Repository Toggle** => Enable it if the container resides in a private repository and also provide the 4 field values which are only to be filled when the container is in a private repository.

**Select Compatible Plan** => This is a multi-select dropdown of the available plans and you have to select the ones suitable for this container.

**Select Default Plan** => This is a dropdown among all the plans chosen in the previous field to chose one of them as the default plan.

**Public Access to WorkStation** => Disabling it will only let the superadmin view this container for spawning.

**Description Box** => Provide a suitable description for this WorkStation for the users to understand the capabilities of this workstation.

**Video Link** => You can provide a video link for this container too, if available.

**Upload Image** => Upload an image for this container as a thumbnail.

**Type of workstation** => Select one of the three categories we have here at Ai-MicroCloud right now for the user’s convenience and understanding as it will be categorized accordingly.

**Stripe Product Id** => All the products have a stripe Id for the billing and metrics purposes.

**GitHub URL** => Url to clone after the initialization of workstation

**GitHub branch name** => Branch name for the github url

&#x20;

Note: All the fields are required and leaving an empty value won’t let you add the WorkStation. It is advised to write N/A if you do not have a value for a text field


# IAM (Identity Access Management)

IDENTITY ACCESS MANAGEMENT

As the name suggests, IAM (Identity Access Management) is the gateway checking the authorization of the requests coming from a user and won’t permit if any request seems unauthorized.

To know more in details about the underlying sections in our IAM system, refer to our [**IAM directory of the documentation under MORE Section**](/info/1.2.6/more/iam).


# Organizations

This section shows a list of organizations using the Ai-MicroCloud as a member.

![Fig. 1: List of Organizations](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/HWeuQfiImYLqYLcYYCJ4/image.png)

**Create New Organization**

![Fig. 2: Create Organization](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/VvNfdzGRWDC3NMjlRXv7/image.png)

The following are the definitions of the fields in the Create New Organization Form:

Organization Name => Name of the Organization

Select Admin => Dropdown list of all the users in the Ai MicroCloud from which you can make the appropriate person the admin of the organization.

Country => Dropdown list of countries which specifies the HQ location of the organization.

**Note:** Creating an organization automatically creates 2 new namespaces for this organization by default: **public** and **private**. For more information, refer to our **NameSpace Guide** under this Section.


# Plans

Resource Aggregation

This section shows a list of plans which specify the resources to be allocated and get attached to a WorkStation or a Microservice and come as a [**fourth step In the Spawning Ai- WorkStation Workflow**](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation#step-4-beta-user)**.**

![Fig. 1: List of Plans](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/eZRsdNswfcGFRVlEYNxt/image.png)

**Create New Plan**

<div data-full-width="true"><img src="https://924165660-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F1uv6074cgUfxr5s1gsAU%2Fuploads%2F1w19sS3RWXMbk5guWC98%2FMicrosoftTeams-image%20(3).png?alt=media&amp;token=d9429b79-1320-45cc-8889-97ca217f6c7d" alt="Fig. 2: Create New Plan" width="375"></div>

The following are the definitions of the fields in the Create New Plan Form:

**Name** => Name of the plan

**vCPU** => Number of vCPUs to be allotted by this plan.

**GPU** => Number of GPUs to be allotted by this plan.

**Worker Nodes** => Number of worker nodes (Used for High Performance Computing).

**Public Access to the Plan** => Toggle to make it available to the public or not.

**Slurm – enabled** => Toggle to make this plan available for HPC (High Performance Computing).

**Memory (GBs)** => RAM to be made available by this plan.

**Storage (GBs)** => Storage to be made available by this plan.

**Select Plan Type** => There are 3 categories available right now:

\-          Ai- WorkStation

\-          MicroService

\-          Ai-API

\-          Orchestration Add-on

**Data Center** => Dropdown list of datacenters available in the Ai-MicroCloud where the resources can be allotted by this plan.

{% hint style="info" %}
**Non Auto-scaling** and **Auto-scaling** option on the top of plan creation form are to be only used when "**Select Plan Type**" drop-down is selected as Orchestration Add-on.
{% endhint %}


# NameSpaces

Resource Segregated Spaces

As the name suggests, these are segregated spaces for organization’s activities where the superadmin decides or even the organization admin decides the members of the namespace under which those users can spawn an Ai-WorkStation, MicroService or an Ai-API.

![Fig. 1: List of NameSpaces](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/gA07JJg6UwUKh5G8XTPP/image.png)

**Create NameSpace**

![Fig.2 : Create NameSpace](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/xd5xz2wK7czuuRroc4DY/image.png)

Two new namespaces with suffix **private** and **public** are created whenever a new organization is created for the users. Also, the users have to be added by the superAdmin or an OrgAdmin for the users to be able to spawn their resources.


# DataCenters

Dedicated space for workload deployments and development

This section lists the datacenters added in the Ai-MicroCloud which ultimately come as an option attached with the plan as shown in our [**Step 4 in Spawn an Ai-WorkStation Guide**](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation#step-4-beta-user).

![Fig. 1: List of DataCenters](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/Osg6rIoG5BEfnA0XEGoL/image.png)

**Add new DataCenter**

Adding a new Datacenter is a two-step process:

·         Filling up the form as shown in the below mentioned image.

![Fig. 2: Form for Adding DataCenter](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/pSwM9gZJwqNMI0tldqRo/image.png)

• Approval of the datacenter by the superAdmin.


# MicroServices

Standalone containers and interconnected ecosystem of containers

This section shows a list of **microservices** which have already been brought to the Ai-MicroCloud and are ready to be spawned by the user using the steps mentioned in [**Spawn a MicroService Guide**](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-microservice) under our Quick Start Section of the documentation.

![Fig.1: List of MicroServices ](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/naJXScJ06GvSCBM7Yv7R/image.png)

**Add MicroService**

![Fig. 2: Add MicroService](https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/kzv7NTldX7QCHc8aZREb/image.png)

The following are the definitions for the fields shown in the **Create MicroService** form.

**Resource Name** => The name of the WorkStation you would like to give.

**Image Tag** => The Image Name along with tag of the docker container.

**Select Compatible Plan** => This is a multi-select dropdown of the available plans and you have to select the ones suitable for this container.

**Select Default Plan** => This is a dropdown among all the plans chosen in the previous field to choose one of them as the default plan/ recommendation.

**Public Access to MicroService** => Disabling it will only let the superadmin view this container for spawning.

**Description Box** => Provide a suitable description for this WorkStation for the users to understand the capabilities of this microservice.

**Internal Ports** => List of port numbers with their protocol which are required for this microservice to work.

**Upload Image** => Upload an image for this container as a thumbnail.

The below tutorial contains all the detailed steps for onboarding a simple microservice and how to spawned the onboarded microservice into the platform.

{% file src="/files/D2RoVqle3xJTTr2HuUYc" %}


# Customised Workstations

Containerization of the Third Party Algorithm

### Objective

Containerizing third party algorithms and using Zeblok's Ai-MicroCloud™ to provide access to more audiences.

### **Steps to follow**

Zeblok offers a basic minimal notebook with pre-installed CUDA Libraries and the associated Docker Hub URL and Dockerfile Urls are given below.

<https://hub.docker.com/u/zeblok> (Docker hub) <https://github.com/zeblok/dockerImagesFiles> (Dockerfiles on github)

* Developers can use one of the Zeblok’s ready to use Docker Images as a base Image in his/her Dockerfile.
* Developers can write the instructions to install dependencies that are required by the Algorithm. (For Instance, if a user’s Algorithm requires BlazingSQL and Rapids AI as dependency, the user can take the Minimal notebook as base and install the dependencies on top of that base in a new Dockerfile as shown below).

```
ARG BASE_CONTAINER=zeblok/minimal-notebook:v0.0.7
FROM $BASE_CONTAINER
USER $NB_UID
RUN pip install -q --pre bentoml
RUN pip install 'scikit-learn>=0.23.2' 'pandas>=1.1.1'
USER $NB_UID
```

* After writing the Instructions for installing the dependencies, the developer needs to build the Image from the Dockerfile using the command \`**docker build -t ‘ALGO\_NAME:VERSION**’ .
* After Building the image user can push the image to dockerHub using the command&#x20;

  \`**docker push dockerUsername/ALGO\_NAME:VERSION**\`.
* After successfully pushing the Docker Image developer will share the docker image Tag, short description, and an Image (400x220px) to <akash.sengar@zeblok.com>.

  <br>


# Resource Manager

This feature allows the admin to have an overall view of the all the Workstations, Microservices and AI-APIs that are spawned into an account of that particular organization on our platform

The resources can be categorized according to the following filter as shown below.

* Resource Type&#x20;
* Organization
* User
* Status

The admin can easily set the values for all the above given fields and check the resources spawned accordingly.

To reach the resource manager tab we just need to login into our Micro-cloud platform and select the "Resource Manager" tab on the left hand list(Shown in below picture).&#x20;

<figure><img src="https://content.gitbook.com/content/1uv6074cgUfxr5s1gsAU/blobs/ENLFixINcAHrZfBxJIdz/Capture.PNG" alt=""><figcaption></figcaption></figure>


# Release notes

ZEBLOK COMPUTATIONAL AI-MICROCLOUD RELEASE NOTES

**Version 1.2.6 (December 2023)**

{% hint style="info" %}
All the below mentioned updates have been integrated into the major release version of AI-Microcloud 1.2.6 from the earlier version in user i.e. AI-Microcloud 1.2.5
{% endhint %}

**SaaS**

*Model Serving of Large Language models*

* LAMACPPserves quantized models
* Facebook 125M model using vLLM serving
  * Served using command line interface as an API

**PaaS**

*ZBL CLI*

* vLLM serving of models as APIs
* LLAMA CPP serving of models as APIs
* Capability of multipart upload of larger model sizes

*COMP APP*

* Refactoring of the whole code base in comp-app in order to reduce SDK communication crashing and improve Error Handling and API interaction handling
* IAM roles and privileges updated for more User privilege and easy segregation of access in organisation's System admins
* Generic Image for Enterprise edition which allows the use of a single image that would be compatible with all our environments.

*UI Improvements for AI-Microcloud*

* [In](http://1.in/) the comp app  updated the profile page design&#x20;
* The support button alignment has been updated
* Once the secret keys are generated they're always available in the session for the user.
* Copy button has been added for the keys
* View password has been also added in the profile page and login page has context menu
* Microservice and Workstations card alignment.
* Removal of the Zeblok Ai-WorkSpace text
* Segregation of Manage account page
* User role should also get displayed on Manage your account page.
* Rename get data-lake key and get api credentials button to Generate Datalake key and Generate API credentials.
* View password button in the register page
* Padding fixes in the UI
* Role table fixes

*COMP AUTH*

* Complete code refactoring for making the app more resilient and avoid server crashing
* Client libraries for object storage(minIO) have been updated which allow on the fly bucket creation and policy creation on minIO simultaneously on user registration.

*Microservices and Workstations*

* Introduction of new and updated microservices and workstations into the Microcloud for more dynamic and extensive usability e.g. StreamLIT UI, Sceenscape, ChromaDB, etc.
* The new versions for docker images have been provided on the seeding part of AI-MicroCloud.

*Monitoring*

* Event Exporter: Dependency on the third party Kubernetes event exporter has been removed and usage of Kube-API is introduced, this has improved event caching and improved reliability, ensuring we are not missing out on released events

*CaaS*

* CaaS is made available for concurrent users by the help of kubernetes jobs in return with no wait time for any user .
* The containerization as a service has been totally redesigned to help improve the usability and to enhance the user experience.The user can have the CaaS service invoked with custom plans as required according to them and also be able to see the logs for the whole process.
* Improvements
  * Big chunks of data is now being able to be fed and processed while model serving .
  * Any size of models can be served and packaged as an API using our CaaS service

**SDK**

* Refactoring of the whole code base for validation processes and changes authentication mechanism and packaging for seamless user experience.

**IaaS**

*Hardware*

* Intel AMX support now available with Basic and Enterprise SKU of AI-Microcloud&#x20;

*Basic Baremetal Launcher*

* Our basic launcher now provides the user to create AI platform into the Bare-metal environment automatically within few minutes by using the launcher filling up some details and providing access credentials(For Bare-Metal connectivity) which are taken in as encrypted data, With all the information taken the scripts to run in the background and providing the URL in the Launcher to access the AI-Microcloud all deployed and ready to use.

*Enterprise Azure Launcher*

* The enterprise launcher allows the user to connect their 3 hubs with any amount of bare metal servers and the user can easily establish the environment automatically within a few minutes by using the launcher filling up some details.

*Platform upgrade*

* Our Applications(MicroCLoud, Launcher and OTF) are now compatible for the MONGO Atlas integration, it’s been tested and ready for use

**Website**

*Playground*

* New Addition to our Zeblok website [www.zeblok.com](http://www.zeblok.com) is the feature of our playground button which enables any interested user to try out our Microcloud free for 21 days by just clicking on the “playground” button and registering on the following forms which will grant him direct accessibility to our playground feature

**Fixes and Improvements**

*Enterprise Launcher fixes*

* Bugs on User Interface now resolved
* Removed the cross symbol from the success message. Instead display a message on new window
* User will land on Marketplace tab when log inside the AI-Microcloud
* Launcher script-Token fixed inside the script
* Hash is now being received on email
* User input are taken interactively while running the script
* Launcher user registration email verification is now enabled
* The instance type in the form t2xlarge is fixed
* Masters name removed
* User now lands on Request page on launcher once he logs in

**Version 1.2.5 (September 2023)**

{% tabs %}
{% tab title="IaaS Updates" %}

**Hardware:**

* AIM now runs on Intel Sapphire-Rapid Processor

**BASIC:**

* Storage for Azure Cloud: AZURE Blob storage from UI for uploading viewing and download of datasets
* AZURE Basic version integrated with Orchestration addon as a usability(Ray usability) which enable the user to use the HPC usability of the platform for training and developing complex models and running immense computations.
* Multi-master cluster on Bare Metal servers supported
  {% endtab %}

{% tab title="PaaS Updates" %}

**SDK usability now supports the following components:**

* Plans
* Orchestration addon
* Namespaces
* Microservices

**CLI:**

* Snapshot of Workstations for creating images of build workstations CLI
* AWS S3 storage has been integrated with the CLI so that the user can easily use the terminal for upload, download, view their dataset
* AZURE Blob storage has also been integrated same as the AWS S3 functionality with the CLI which enables the users perform the similar dataset actions seamlessly on both cloud platforms
  {% endtab %}

{% tab title="SaaS Updates" %}
**Launchers:**

* Basic:
  * Updated UI and integrated with Order to fulfillment (For AWS launcher)
    * User Interface is revamped ,&#x20;
    * Eks form is updated with the feature of adding desired nod pool and is implemented in both EKS and AKS .
    * The form to create the launcher and complete requests is made user-friendly
    * Integration of azure AKS to establish Basic microcloud
* Enterprise:
  * Updated UI and integrated with Order to fulfillment
  * User can install the Launcher himself
  * Integration Of Azure platform to launch enterprise edition
  * The user interface and form to establish AI-Microcloud is made consistent with the basic launcher and more user-friendly .

**ISV:**

* Users can deploy intel screenscape using AIM. Intel® SceneScape is the software base to get your custom tracking solutions up and running fast. Intel® SceneScape enables improved decision-making by giving users the near real-time tracking and monitoring data they need to assess the people and objects within their spaces and enterprise environments such as airports, hospitals, retail stores, factories, and warehouses. Intel® SceneScape is also compatible with the Intel® GetiTM platform so that you can create and train custom AI models that enable better monitoring of people, high-value assets, and important areas within your space.
  {% endtab %}

{% tab title="AWS Marketplace" %}

**AWS Marketplace:**

Zeblok's SaaS product, "AI-MicroCloud," with AWS Marketplace to enable customer onboarding, metering, billing, and vendor-metered tagging functionalities. The integration offers a seamless subscription experience for customers accessing the product on AWS Marketplace, along with accurate billing based on metering records.

**Basic:**

* Small Flavor:
  * Instance Type: t3.medium
  * CPU Model: Intel(R) Xeon(R) Platinum 8259CL CPU @ 2  .50GHz
  * CPU Family: Cascade Lake
  * vCPUs: 2 per instance
  * Memory: 4GiB per instance
  * Total Nodes: 3
  * Overall Resources: 6vCPUs and 12GiB Memory
* Large Flavor:&#x20;
  * Instance Type: g2.2xlarge
  * CPU Model: Intel(R) Xeon(R) CPU E5-2650 v2 @ 2.60GHz
  * CPU Family: IVY Bridge EP
  * vCPUs: 8 per instance
  * Memory: 15GiB per instance
  * GPU: 1 Nvidia GPU 4GiB (Model: K520) per instance
  * Total Nodes: 3
  * Overall Resources: 24vCPUs, 45GiB Memory, and 1 GPU per node
  * K520 4 GB GPU support on AWS Basic version on large flavors type

**Enterprise:**&#x20;

* 3 servers in HUB of any AWS provided flavor that are enlisted into the Launcher App which the user can select while configuring their Microcloud.
* The User gets connect up to 5 Bare-metal edge nodes into the environment selecting them through Launcher among the certified hardware provided by Zeblok:
  * Intel® Xeon® Platinum, Gold, Silver or Bronze Processor
  * Intel® Xeon® Processor D-1747NTE, CPU TDP 80W&#x20;
    {% endtab %}
    {% endtabs %}

**Version 1.2.4 (June 2023)**

{% tabs %}
{% tab title="IaaS Update" %}
**Enterprise version:**

* **Software Updates:** All the software packages are updated to latest version which covers bug fixes and security updates.&#x20;
* **Security**:&#x20;
  * User can select and implement the Minimum base line security standard(MBSS) over edge server using UI of Enterprise launcher.&#x20;
  * User can restrict the SSH access to the edge server using UI of Enterprise launcher.
* **Hardware**:&#x20;
  * Supermicro IoT SuperServer SYS-510D-10C-FN6P is certified for use as edge server.
  * Supermicro IoT SuperServer SYS-110D-20C-FRAN8TP is certified for use as Hub and edge server.
  * Intel® Data Center GPU Flex 140 is tested and certified for use at Hub and edge server
* **Monitoring**: User can view the edge nodes attached to the cluster and check their online status whether active or not.

**Basic version:**&#x20;

* **Auto scaling plans on AWS**: Users can now define auto-scaling plans in Ai-MicroCloud® which makes the platform capable to scale the infrastructure as the need of resource increases while running the AI workloads. &#x20;
* **Storage**: Ai-MicroCloud® datalake now uses S3 as backend in AWS environment.&#x20;
* **Security**: Encryption layer provided onto the *Basic Launcher* while taking in sensitive data from the user which allows the system to be more secured from foreign attack
* **HPC**: Users can spawn Ray clusters using orchestration add-on feature of Ai-MicroCloud® which will enable them to train and develop models with speed.  &#x20;
  {% endtab %}

{% tab title="PaaS Update" %}

* **Datasets**: Now users are able to delete the datasets created before using GUI from the micro-cloud itself.
* **Bucket Creation**: Now any user when onboarding the Micro-cloud will be getting an personal bucket automatically created as soon as they will sigh-up and log-in into the platform.
* **Orchestration Add-on**: In our platform GUI the orchestration button is added which will enable our users to spawn an Ray cluster and utilize it easily.
* **IAM roles**: Now our platform will be providing pre defined roles when our micro-cloud is spawned which can then me distributed by the admin role person to the other user in their organization through the utilization of user groups.
* **Logs**: Logs now enable our users to check the login details of their workstations, Micro-services and AI-APIs and in addition our logs have been increased to contain information for past 30 days which will be handy for troubleshooting.
* **CLI**: ML-flow integration done which allows users to upload and serve their models easily and efficiently into the platform and use it for training and utility purpose.
  {% endtab %}

{% tab title="SaaS Updates" %}

* **Basic Launcher**: Our basic launcher now provides the user to create AI platform into the AWS environment automatically within few minutes by using the launcher filling up some details and providing access credentials which are taken in as encrypted data, With all the information taken the scripts to run in the background and providing the URL in the Launcher to access the AI-Microcloud all deployed and ready to use.
* &#x20;**Flexible Environment**: On collaboration with the fortune 500 goliath we have adjusted our platform to work under 3rd party network norms in which we will provide only necessary communication of our platform to be allowed and provide that detail to organizations which can be fed on their private network layers and allow the usage of the Microcloud in a more flexible and secure method.
  {% endtab %}
  {% endtabs %}

**BUG FIXES:**

* Removal of the Datalake button on the user interface
* Flickering of the Ai-MicroCloud® login page
* Error handling, error message will be shown at the bottom of the webpage
* Support button fixed with proper ticket creation
* Alerting integrated into the platform to know the status of the environment in case of downtime
* CROSS cloud integration resolved
* Automatic redirection to the next/previous page once action completed on current
* All mandatory fields highlighted in forms for the users
* ML-flow integration on the ZBL CLI

**Version 1.2.2 (JANUARY 2023)**

{% tabs %}
{% tab title="IaaS Updates" %}
Edge Monitoring:

* SuperAdmin can monitor CPU and Memory for edge servers and deployed microservices with a more detailed overview which allows them to gather detailed information about individual Edge servers or particular microservices.
* Detailed Graphical representation of the utilization of server resources.

<br>

CICD:

* Automatic cyclic updation without taking down the whole environment i.e. only changing the git version which will directly incorporate changes into a pre-deployed AI-M ecosystem
* Automated deployment of the whole ecosystem from a single point of contact just by using variables that are collected from the user irrespective of the platform/environment to be deployed upon.

<br>

Edge Security:

* Minimum Baseline security(MBSS) has been incorporated into our ecosystem for providing standardized security according to the global regulations which makes the whole platform very secure to outside attacks.&#x20;
* Access control on Edge provides SSH and BMC console only from specific subnets and on specific interfaces.
* Data encryption on local storage is incorporated into the system to make it more secure.
  {% endtab %}

{% tab title="PaaS Updated" %}
Order Fulfillment System:

* The new addition to our whole micro-cloud makes the interaction between user from buying the product to login into the micro-cloud really streamline by providing a one stop solution for the organization to place an order and setting up the microcloud.

<br>

Launcher:

* “Basic launcher” deployment on cloud platform(AWS)
* “Enterprise launcher” inclusive of the previous launcher version released in the last quarter along with the option to have HUB in either Public cloud or Bare-metal and attachment of multiple Edge nodes irrespective of the placement of HUB
* GUI enhancement from the previous CLI only useability to deploy your Ai-Models to multiple edge nodes simultaneously in an Edge Datacenter as an Ai-API.

<br>

Datasets:

A machine learning dataset is a collection of data that is used to train the model. A dataset acts as an example to teach the machine learning algorithm how to make predictions, Now our users can easily onboard their data onto the platform using few simple steps which can be utilized by any Micro-service/workstations that are spawned on the platform <br>
{% endtab %}
{% endtabs %}

**Version 1.2.1 (SEPTEMBER 2022)**

{% tabs %}
{% tab title="SaaS Updates" %}

* **Improved Microservice Configuration:** Spawning MicroService workflow now has a more flexible and dynamic configuration system for environment variables, arguments, ports, etc.
* **Simultaneous EDGE deployments** of AI-API and MicroServices.
* **Zeblok Cli**: Zeblok Cli now provides an option to deploy your Ai-Models to multiple edge nodes simultaneously in an Edge Datacenter as an Ai-API.
* **Dynamic plans (CPU and Memory)**: Spawning Ai-WorkStation, MicroService and Ai-API workflows have been added with an option to **attach customized plans** (CPU and RAM according to user’s needs) where the resources will be within the limits set by the **real-time resource metrics** **recommendation** system.
* **Resource manager with monitoring**: Resource Manager Tab in Ai-MicroCloud now gives the superadmin and admins an **ability to view the monitoring graphs** of each resource like Ai-API, Ai-Workstation and MicroServices.
* **Crosscloud integration:** Ai-Models and Ai-Pipelines have been enabled to show their **security scan logs** along with previously enabled Ai-WorkStations and MicroServices which gives the users a better understanding of vulnerabilities in their images.

**LAUNCHER APP(Edge):**

* New GUI for easy and efficient setup of the **Microcloud on bare metal servers**
* **Zeblok Launcher App** is the newest member in the Ai-MicroCloud installation ecosystem. This feature  seamlessly installs the whole Ai-MicroCloud edge ecosystem from scratch in a bare-metal environment efficiently.
  {% endtab %}

{% tab title="PaaS Updates" %}

* **Zeblok CLI** is available at - <https://www.npmjs.com/package/zbl-cli> can be installed using **\`npm i -g zbl-cli\`.**
* **SDK** is available at <https://pypi.org/project/zeblok-py/> can be installed using `pip install zeblok-py`
* **SDK:** SDK now enables users to simultaneously deploy **Ai-Pipelines in multiple enterprise datacenters** and collate results (Ai-Runs) in a single endpoint of your choic&#x65;**.**
* **Minikube setup enabled**: The Ai-MicroCloud ecosystem has been upgraded to **work in an isolated environment** (like minikube) without any access to outside networks with the help of our private image repository.

**NEW WEBSITE**

* **Zeblok.com is live with a new look and updated content** for the users to get more insight into our concept and know us better. We would really like you to **visit us at:** [**https://www.zeblok.com/**](https://computational.zeblok.com/)&#x20;
  {% endtab %}

{% tab title="IaaS Updates" %}

### **EDGE**

* **Monitoring:** SuperAdmin can **monitor CPU and Memory for edge servers** and deployed microservices.
* **Storage:** Block storage solution which takes **care of data replication across** hub servers available for all users. This protects data loss if one of the hub servers goes dow&#x6E;**.**
* &#x20;**Data handling on edge servers:** ISVs can use command line to **push the data from edge servers** (either from hosts or microservices) to custom storage buckets located in the Hub for further use(eg. Model training). For more information, refer the ISV onboarding document [**ISV Onboarding User Guide\_v1.0\_01092022.docx**](https://docs.google.com/document/d/1Bvn-wIgRVxOePRZTQPsnZd3LTHZNlfNU/edit?usp=sharing\&ouid=110761061358716077052\&rtpof=true\&sd=true)
* **Image Registry & Security:** Users can store docker images on the on-prem image registry located at the Hub. Most importantly, **security scans** can be performed on docker images for vulnerabilitie&#x73;**.**
* **Scale: 1000 edge servers connected** in a single cluster tested in the lab

### **Enterprise and Edge**

* **“kubectl” access can be provided to ISVs** admin users for specific namespace to spawn multiple microservices via Zeblok’s “ISV Management” microservice. For more information, refer the ISV onboarding document [**ISV Onboarding User Guide\_v1.0\_01092022.docx**](https://docs.google.com/document/d/1Bvn-wIgRVxOePRZTQPsnZd3LTHZNlfNU/edit?usp=sharing\&ouid=110761061358716077052\&rtpof=true\&sd=true)
  {% endtab %}
  {% endtabs %}

**Version 1.2.0 (JUNE 2022)**

{% tabs %}
{% tab title="SaaS Updates" %}
Zeblok Python SDK now has the feature to **deploy simultaneous multi-datacenter Ai-Pipelines** with also the ability to integrate the Ai-Runs output with open source tools.
{% endtab %}

{% tab title="PaaS Updates" %}

* Dashboard now has the ability of **one click export users’ data** table as CSV for super admin and admins.
* Every user will now get a **weekly mail** regarding his/ her usage details over the week.
* **Private Docker Image repository support** has been enabled for both Ai-WorkStations as well as MicroServices, giving users the privilege to pull images from their private repositories.
* Users can now **select from multiple versions** of an Ai-WorkStation or MicroService while spawning (latest or a previous version).
* **Single click social media sign in** has been enabled via google.
* Google Authenticator Process has been enabled for a strong **multi layered security process**.
* MicroService spawning and Ai-API spawning process now have a configuration of plans attached which will  also be reflected in the monitoring graphs of the same.
* MicroServices are now flexible to **support multiple protocols** which can be exposed publicly or can be interconnected to other **microservices as an ecosystem**.
* Spawning process has been made more error resistant, optimized and also intelligent with zeblok **cli auto configuration** process while spawning.
* Ai-WorkStation spawning workflow now gives you a choice to **mount your S3 bucket** from our Ai-DataLake.
* A **new MLOps Workflow** has been introduced for simultaneous multi-datacenter **Ai-Pipeline, Runs and experiments** with seamless integration with open source tools, which can be initiated using the zeblok cli.
  {% endtab %}

{% tab title="IaaS Updates" %}

* **Zeblok Private Image Repository** is the newest member in our Zeblok Infrastructure Ecosystem for real time security scans of the images as well as providing the security scan logs along with the severity of risks.  This increases overall security as well as the image pull limit becomes a thing of the past.
* Zeblok Containerization Service has been upgraded for **containerizing the Ai-Pipelines** images as well as for the auto deployment of the same.
  {% endtab %}
  {% endtabs %}

**Version 1.1.0 (MARCH 2022)**

{% tabs %}
{% tab title="SaaS Updates" %}

* Openvino Model Serving capabilities are now supported in the Ai-API Engine.&#x20;
* Openvino toolkit distribution has been upgraded to version 2022.4.1&#x20;
* Ai-WorkStations have been upgraded with Nvidia Cuda Version 11.4&#x20;
* JupyterLab has been upgraded to the latest version along with Python v3.9.
  {% endtab %}

{% tab title="PaaS Updates" %}

* New IAM (Identity Access Management) has been developed giving users and admins access to modify roles and permissions in a dynamic way giving more flexibility and ownership to the authorized users.&#x20;
* Username of the authorized user has been mapped to jupyterlab notebook spawning process giving more insight to security and tracking of activities.&#x20;
* Zbl Cli has been upgraded for the openvino packaging process of the IR models generated by Openvino notebook giving users more freedom on the Model Serving process.&#x20;
* Zbl Cli now has a new option/ feature for automating the Ai-API Deployment process using which users can predetermine their choices/ parameters for their deployment.&#x20;
* A new cross cloud service has been established where the packaged models from the cli are uploaded and image building and pushing to hub steps have been undertaken by the cross cloud service. A mail is sent to the users after the models become ready for deployment via Ai-API Engine.&#x20;
* Ai-API deployment now supports GRPC protocol where, on using a suitable GRPC client, users can interact with the trained models in a deployed state.&#x20;
* Zeblok Ai-DataLake has been upgraded and a one click auto account setup system has been introduced for the users along with RBAC security policies.&#x20;
* Resource Manager has been re-introduced now extending its capabilities for an organization admin too, where the administrator now has full control and insight over the resource consumption and Spawned Resource activities of the members of the Organizational Unit.&#x20;
* Auto backup of the MongoDB is enabled every 6 hours in all the environments.&#x20;
* Seamless Database seeding is enabled for quickly restoring the database from the backup.
  {% endtab %}
  {% endtabs %}

**Version 1.0.0 (DECEMBER 2021)**

{% tabs %}
{% tab title="IaaS Updates" %}

* Zeblok Ai-MicroCloud is now available at Azure Cloud Environment with all the latest features and power giving the same experience of Zeblok AI-MicroCloud on the Azure Platform.&#x20;
* Zeblok has established Ai-MicroClouds for two private baremetal turned cloud environments: Advantech Labs and Intel Dev Cloud.
  {% endtab %}

{% tab title="PaaS Updates" %}

* Notebook creation workflow has a new field added now for specifying run commands as a post workstation creation lifecycle which comes as a configuration flexibility for the Notebooks’ running.&#x20;
* DataCenter (only edge categories) have now an option for adding kiosks to them which can be selected for deploying your microservices and Ai-API on a specific kiosk.&#x20;
* Ai-API workflow has a new step added now for the selection of kiosks while selecting an On-Premise DataCenter.&#x20;
* Microservices also have a new step added now for the selection of kiosks while selecting an On-Premise DataCenter.&#x20;
* A new section in the menu has been added for Virtual Machines where you can get the shell access to a kiosk which is available as a node on the on-premise DataCenter.&#x20;
* Datacenter Monitoring page has been added for getting a status of the performance of all the nodes in the datacenter cluster along with a provision to view the monitoring logs and graphs of a specific node too.&#x20;
* A button to view the Ai-WorkStation or the MicroService pod logs has been given to view logs while the spawned resource is in running mode.&#x20;
* Session monitoring of all aiws,microservices and aiapi has been enabled for all the users so that the users can monitor the workloads and resources being consumed by their spawned resources and also decide if they need to upgrade to another plan.&#x20;
* A brand New user interface has been released giving a rich and smoother experience of the whole Ai-MicroCloud.
  {% endtab %}
  {% endtabs %}

**Version 0.0.9 (SEPTEMBER 2021)**

**PaaS Updates:**

* Admin analytics dashboard has been updated with more precise and accurate data along with bug fixes providing a more precise idea of the usage by the users.&#x20;
* Zeblok Authentication MicroService has been updated with more secure tokens and authorization logics while making the user’s authentication and signup process easier than before.&#x20;
* Zeblok Ai-MicroCloud introduces a brand new workflow for microservices where you can run pre-uploaded and modified images in an isolated and an independent environment in just a few clicks like MongoDB, Intel DLWorkBench, etc.&#x20;
* Session page now also handles metrics for spawned microservices along with Ai-WorkStations.&#x20;
* User’s profile has two new tabs for Spawned MicroServices and one for their total runtime consumptions, both of which can be accessed by the SuperAdmin and the Organization’s Admin.&#x20;
* Periodic Backup in every 6 hours has been established in aws s3 buckets as a disaster management measure.&#x20;
* Superadmin now gets a new tab in their menu called “Resource Manager” where you can have a look at all and every kind of resource in the Ai-MicroCloud like Ai-WorkStation, MicroServices and Ai-API and also control them if required.

**Version 0.0.8 (JUNE 2021)**

Infrastructure Re-Architecture is done for better performance.

* Jupyterhub is taken out and Kuberntetes APIs are Introduced for Orchestration giving a more stable infrastructure and debugging system.&#x20;
* This new Architecture allows more control over resources and gives a faster experience so that the users don’t have to wait for the spawning process for too long.&#x20;
* Dynamic Plans can be introduced now giving full access to the power of the infrastructure.&#x20;
* Istio Mesh Networking is introduced for Load Balancing and Networking among the pods for better connectivity along with a better security.

**PaaS Updates:**

* Login and Signup pages have a new UI now which is also mobile responsive.&#x20;
* Update has been rolled out for the new Admin analytics dashboard with more analytical metrics for viewing the activities of specific users in an organization.&#x20;
* Session page has more attributes added for more in depth metering and analysis.&#x20;
* User’s profile has a new tab for durations of the Ai-WorkStations now.&#x20;
* The Organizations table has a new View button for viewing the users and their duration of work in the Ai-Workstations.&#x20;
* Server Side pagination is implemented for reducing the bandwidth usage for users.&#x20;
* We now introduce a new workflow in our Ai-MicroCloud called Ai-API Engine which can be accessed by going to the Ai-Api section in the menu and clicking on the Create Ai-API button. For more information, you can visit <https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/introduction&#x20>;
* A new separate Zeblok Authentication microservice has been added exclusively for enhanced Authentication Processes and validation and also giving users the ability to secure their account using 2 factor authentication.&#x20;
* The Login Method has been improved with the addition of Refresh Tokens and JWT Token for a better and new level of security.

**Version 0.0.7 (MARCH 2021)**

{% tabs %}
{% tab title="IaaS Updates" %}
**All the Zeblok benefits, now in AWS:**

Automated/scripted the deployment of the Zeblok platform within AWS, which will help us serve our customers better. How?

* They don’t have to move their data across datacenter or platforms, reducing a large amount of effort and billing, as they don’t have to engineer the data movement in and out of AWS, which also impacts data security. Less movement of data in and out of AWS saves bandwidth cost.
* Usage can be customized as per individual organization needs. Doesn’t matter if the requirement is of 1 GPU or 10 or 100, the system can easily be scaled as and when required. Increasing impact or ROI and decreasing un-utilized cost.

To learn more about our AWS Deployment. Visit [here](https://docs.google.com/document/d/1UPAoEAeZ0rn3w8mWLCyAFludqEGdMNajoGlYmMfKo4c/edit?usp=sharing).
{% endtab %}

{% tab title="PaaS Updates" %}

* Admin can now view stats such as how many users per day, per week have onboarded.&#x20;
* Admin can sort by Each organization and view how many notebooks and users.&#x20;
* New menu called Activity Monitor is added. All data aggregation happens here.&#x20;
* Which user has access to what type of notebooks&#x20;
* Activity Report is now available.&#x20;
* Usage statistics are now available - by organization, user group, plan&#x20;
* Updated Menu Hierarchy and rearranged icons for enhanced user experience&#x20;
* Successfully implemented and deployed PaaS Foundational components and AI data lake in the AWS environmen&#x74;**.**
  {% endtab %}

{% tab title="SaaS Updates" %}

* Documentation for AI-Rover is now available.&#x20;
* Recently collaborated and acquired new video analytics algorithms for edge IoT applications&#x20;
* Custom AI-rover development workstations are available for the fintech use-cases
* Data Scientists and ML developers can now containerize and deploy their own algorithm workstations in the Zeblok Intelligence Marketplace. The user guide for containerizing of algorithms is available [here](https://drive.google.com/file/d/1ZsuIa5D41h4KStbW7s3dayhrJZdkliQu/view?usp=sharing).
  {% endtab %}
  {% endtabs %}

**Version 0.0.6 (DECEMBER 2020)**

{% tabs %}
{% tab title="ZEBLOK SUPERADMIN" %}

* A new button of DATA LAKE is added besides the create workstation button where users can experience object storage provided via zeblok for storing their necessary files for their Ai-WorkStation.
* Session Icon (Time Watch) is added to the listed spawned workstation (Active) on the landing page , where you can see your sessions.
* **Activity Logs**
  1. A new tab is added in the profile section where you can see all your activities and the resources which you have visited.
* **DashBoard**

  1. All users display more information like Allowed Notebook , Last Active etc are visible.
  2. A new Section in View Button of Users is added to Activity Logs , where Super Admin can monitor users activities.
  3. A quick summary of users is displayed and a “View More analytics” button is added for further resources monitoring page.
  4. Users Section - In the users information display , on clicking “View” for a particular user , 2 new tabs of activities and spawnedImages are created to show its activities log and spawned Workstation by use&#x72;**.**

  **Resources Monitoring**
* Super Admin can see following data
  * Total number of resources created like Workstations ,User Groups,Roles, Organizations,Plans etc.&#x20;
  * Further re-distribution pie charts of various different sub categories of resource like -&#x20;
    * Workstations : Data Science , Algorithms , Hyperconvergence .&#x20;
    * Plans : CPU , GPU , Both&#x20;
    * Data Center : Public , Private&#x20;
  * A User Statistics Bar graph showing all new Users , all new Beta Users , all new Non Beta Users created along with that all active users , all active Beta users , all active non Beta users.&#x20;
  * A Stacked Graph of users created each day is shown with categories of Beta and Non Beta User.&#x20;
  * A pie chart showing Spawned Images data of users along with a table of further different categories of data.&#x20;
  * Stacked Bar Graphs showing Workstations Created Day wise ,Workstation which are currently running as Day wise ,Number of CPU/GPU spawned with the notebooks on the respective date.&#x20;
  * A stacked Bar graph showing the count of All Notebooks spawned with different plans.&#x20;
  * For more detailed information , please refer to <https://docs.google.com/document/d/1sv0aMzLhc63X5HKsAPfSufRn8kz8mH4eXnkTHMcPBEU/edit?usp=sharing&#x20>;
  * All the data can be filtered out between any time intervals. While the data which is related to any organization then it will be updated as per the organization.&#x20;
  * Admin can use filters for both categories like Search by Organization , Search by Duration or Both.
* **Workstation**
  * In the workstation table , a new column of licence is added to put licenses in algorithms and hpc’s.
* **IAM Menu**
  * A new menu of IAM introduced which consists of all access management menus like roles , resources , menu and user groups from where superadmin can give or modify access for a specific role in the Ai-MicroCloud.
  * This helps to customize the side navigation menu also.
    {% endtab %}

{% tab title="Enterprise Admin" %}

* **Landing Page**
  * &#x20;A new button of DATA LAKE is added besides the create workstation button.
* **Session Icon (Time Watch)** is added to listed spawned Images (Active) on the landing page , where you can see your sessions.
* **Activity Logs**
  * A new tab is added in the profile section where you can see all your activities and the resources which you have visited.
* **DashBoard**
  * All users display more information like Allowed Notebook , Last Active etc are visible.
  * A new Section in View Button of Users is added to Activity Logs, where Super Admin can monitor users activities.
  * A quick summary of users is displayed and a “View More analytics” button is added for further resources monitoring page
  * **Users Section**
    * In the users information display , on clicking “View” for a particular user , 2 new tabs of activities and spawnedImages are created to show its activities log and spawned images by user.
* **Resources Monitoring**
  * A User Statistics Bar graph showing all new Users , all new Beta Users , all new Non Beta Users created along with that all active users , all active Beta users , all active non Beta users.
  * A Stacked Graph of users onboarded each day is shown with categories of Beta and Non Beta User.
  * A pie chart showing Spawned Images data of users along with a table of further different categories of data.
  * Stacked Bar Graphs showing Workstations Created Day wise ,Workstation which are currently running as Day wise ,Number of CPU/GPU spawned with the notebooks on the respective date.
  * A stacked Bar graph showing the count of All Notebooks spawned with different plans.
  * For more detailed information , please refer to [**https://docs.google.com/document/d/1sv0aMzLhc63X5HKsAPfSufRn8kz8mH4eXnkTHMcPBEU/edit?usp=sharing**](https://docs.google.com/document/d/1sv0aMzLhc63X5HKsAPfSufRn8kz8mH4eXnkTHMcPBEU/edit?usp=sharing) (Organization Admin section)
  * All the data can be filtered out between any time intervals. By default , data of the last 6 months is displayed.
    {% endtab %}

{% tab title="Enterprise User" %}

* **Activity Logs**
  * A new tab is added in the profile section where you can see all your activities and the resources which you have visited.
* **Landing Page**
  * A new button of DATA LAKE is added besides the create workstation button.
* **Session Icon (Time Watch)** is added to listed spawned Images (Active) on the landing page , where you can see your sessions.
  {% endtab %}

{% tab title="Individual Users" %}

* **Activity Logs**
  * A new tab is added in the profile section where you can see all your activities and the resources which you have visited.
* **Landing Page**
  * A new button of DATA LAKE is added besides the create workstation button.
* **Session Icon (Time Watch)** is added to listed spawned Images (Active) on the landing page, where you can see your sessions.
  {% endtab %}
  {% endtabs %}

**Version 0.0.5 (SEPTEMBER 2020)**

* An AlgoStore is now made available for the users to go and get detailed information about all the containers giving knowledge and also making the selection easier according to the needs.
* Read More button on each algorithm provides information on capabilities, a youtube video link and links to other sources for more information.
* Join Slack option provided for all users to join our dedicated Slack channel for any kind of clarification, bug posting and discussion with our team.
* Documentation link is provided at the navbar to read and understand the design and workflows of the Ai-MicroCloud for a non ambiguous experience.

{% tabs %}
{% tab title="ZEBLOK SUPERADMIN" %}

* **Dashboard**&#x20;
  1. Can view all the users present on the platform segregated according to their roles, organizations for getting a view of the whole microcloud users.&#x20;
  2. Each user is categorized into a beta and non-beta user. Admin can update the user as beta or non-beta. Beta users have many more features unlocked for them than a non beta user.&#x20;
  3. Each user has a no. of allowed notebooks assigned to him. The user can only spawn that many number of notebooks if he is a beta user which depends on his subscriptions and resource management rules.
  4. Beta users are the ones who are already present in the computational-beta environment. For these users they do not have to buy plans. Their billing would continue as it was happening before. They can spawn a limited number of notebooks as given access by the Zeblok Admin.
* **Workstations**
  1. All notebook containers are displayed here as a list in a table where the superadmin can perform CRUD operations on the notebooks.&#x20;
  2. Superadmin can edit the notebook image, name, description, restrict public access, add video hyperlink and other sources, and can add the stripe product ID for charging this workstation.&#x20;
  3. Superadmin can set the related plan and default plan for the container.
* **Spawned Images**
  1. Workstations spawned by the users are shown in Ai-WorkSpace along with the current status of their workstations and corresponding sessions.&#x20;
  2. All the activities of each workstation can be listed by clicking on their respective sessions icon giving a full in-depth overview of the activities done on the Ai-WorkStation.
* **Roles**
  1. Orgadmin role added giving full access to the organizational unit which consists of an orgadmin and all org users.&#x20;
  2. Orguser Role added as the role given to the users who are invited to the Ai-MicroCloud via an invite sent out by the OrgAdmin from the dashboard.
* **Plans**
  1. Plans can now be edited and deleted by the zeblok superadmin giving a more dynamic resource allocation system for the Ai-WorkStations.
* **Data Center**
  1. Data center requests can be seen here (Requests are by default given a Pending status).&#x20;
  2. It is the responsibility of zeblok admin to check and approve those data center requests and make them active.&#x20;
  3. Once approved these data centers would be visible to the users while creating workstations. (shown on the world map)
     {% endtab %}

{% tab title="Enterprise Admin" %}

* **Dashboard**
  1. Enterprise Admin can invite users to be a part of his enterprise. He/She will be able to send out the mail to the users he wants to invite.&#x20;
  2. Can view all the users of his enterprise and according to their roles and beta users.
* **Other accessibility**
  1. The enterprise admin can use the zeblok platform the same way a normal user (spawning workstations, use data lake etc.)
     {% endtab %}

{% tab title="Enterprise User" %}

* **SignUp**
  1. Enterprise users are invited by enterprise admins to join the zeblok platform under the enterprise.&#x20;
  2. Once invited, enterprise users will receive a mail to signup to zeblok platform under their respective enterprise.
     {% endtab %}

{% tab title="Individual Users" %}

* **Create Workstation**
  1. **Select Your Plan**

     * Available Plans now show all data center locations on map.
     * Plan details (vCPU, GPU, RAM and storage) displayed by hovering mouse over the specific plan card with Buy Plan Button if subscribed and select plan if not subscribed.

     **Reference Link :** [**https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation**](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation)
* **Computational App non-HPC**
  1. Zeblok Admin Role enhancements with permissions and access&#x20;
  2. Enterprise Admin Role enhancements with permissions and access
* **Computational App HPC**
  1. Slurm Workers support for Conda&#x20;
  2. Slurm Workers support for MPI
* **Computational Algo Store**
  1. HPC Notebook showing Distributed Tensor flow (CPU only)
* **Infrastructure**
  1. Full featured TEST environment&#x20;
  2. HPC file system with LUSTER.&#x20;
  3. Storage Virtualization re-architecture with CEPH block store
* **Encryption in Transit**
  1. VPN based for kube traffic
     {% endtab %}
     {% endtabs %}

**Version 0.0.4 (JUNE 2020)**

* Each Notebook has some predefined plans by the admin, and among them is a default plan which is recommended by us for the selected workstation to run without any resource limitations.&#x20;
* Organization Admin Role Added for better handling of access control within the organization so that the onboarded users can make the microcloud their own.&#x20;
* Organization Admin has been given the access to view/edit/update/delete all the users under his organization.

**Version 0.0.3 (MARCH 2020)**

* The better, fresh and responsive user interface is now available.
* Jupyterlab and Notebooks are updated to their latest Versions.
* Each user will now have access to a dedicated GPU and from 4GB to 8GB of memory.&#x20;
* Each user will be able to spawn one server at a time.
* Cull feature is now introduced. If a workstation is not utilized by users for two hours then it is automatically culled and resources released, if the browser session is killed. JupyterHub will run the culling process every ten minutes and will cull any user pods that have been inactive for more than one hour.&#x20;
* A license agreement is now required on signUp which is stored in the Database.&#x20;
* Zeblok Readme Notebook is now available in the environment showing tutorial instructions on retrieving compute, datalake and other platform features.&#x20;
* Nvidia Rapids example Notebooks are available on spawning the server using Nvidia Rapids Image.&#x20;
* Now the infrastructure has been moved within a VPN, making it more secure and easy to expand the infrastructure.&#x20;
* Slack community is added.

**Version 0.0.2 (DECEMBER 2019)**

* A wide range of Ai-ML and DataScience Notebooks is added now as a library of notebooks giving users multiple options to spawn in JupyterHub like PySpark, TensorFlow and many more.
* Ai-AppStore now includes trademarked notebooks and available for use upon agreeing the license agreement for Terms and usage. For example: Explainable AI by Akai Kaeru.
* Notebooks have been CUDA optimized for the NVIDIA GPU with SLI support.

**Version 0.0.1 (SEPTEMBER 2019)**

* Users are now able to spawn JupyterHub based notebooks as Ai-Workstation within CEWIT (Center of Excellence in Wireless and Information Technology) Datacenter cluster.
* Users are now allowed to spawn basic minimal notebooks with cuda optimization for NVIDIA GPU cards (RTX6000) saving enormous time for users.
* JWT Authentication layer is now available on top of our JupyterHub that authenticates only the valid users to spawn in a secure manner.


# Known Issues


# Common Errors


# Support Emails

For custom node configurations or modifications and any other queries, feel free to contact our support team. We're here to cater to your specific requirements.

<table><thead><tr><th width="378" align="center">Team</th><th align="center">Email</th></tr></thead><tbody><tr><td align="center">Technical Team</td><td align="center">support@zeblok.com</td></tr><tr><td align="center">Sales Team</td><td align="center">sales@zeblok.com</td></tr><tr><td align="center"></td><td align="center"></td></tr></tbody></table>


# About Zeblok Computational

The Zeblok Ai-WorkStation provides a single unified pre-configured environment for data scientists to access datasets, GPU-powered AI/ML frameworks, languages, and tools, with AI algorithms available from our Intelligence Marketplace. The Ai-WorkStation includes one GPU, one vCPU and 64 GB of storage, but scales easily as required. For more demanding workloads, the Zeblok Ai-HPC-WorkStation adds Slurm-as-a-Service and parallel processing, using worker nodes, by enabling the deployment of 4 or more GPUs.

The Zeblok Ai-WorkStation is built upon a Jupyter notebook, an interactive coding environment that lets you combine code with equations, visualisations, rich text, and other media. We make it easy to explore data and coding concepts and collaborate with other people on data science projects.


# Core Concepts

### Ai-MicroCloud™

Ai-MicroCloud™ provides a single, cohesive, turnkey, cloud native AI environment for development, testing, training and deployment of an end-to-end AI/ML solution to production from Core to Edge.

It saves 12-18 months of engineering effort to integrate the multitude of technologies, countless hours of business effort to establish a compatible and collaborative AI ecosystem, and reduces GTM for ISVs by 8-12 months.

[Learn More...](https://www.computational.zeblok.com/ai-microcloud)

### JupyterLab: Jupyter’s Next-Generation Notebook Interface

JupyterLab is a web-based interactive development environment for Jupyter notebooks, code, and data. JupyterLab is flexible: configure and arrange the user interface to support a wide range of workflows in data science, scientific computing, and machine learning. JupyterLab is extensible and modular: write plugins that add new components and integrate with existing ones.

### The Jupyter Notebook

The Jupyter Notebook is an open-source web application that allows you to create and share documents that contain live code, equations, visualizations and narrative text. Uses include: data cleaning and transformation, numerical simulation, statistical modeling, data visualization, machine learning, and much more.

### Ai- WorkStation

The Zeblok Ai-WorkStation provides a single unified environment, which seamlessly orchestrates infrastructure, open source AI/ML frameworks and proven, original AI algorithms. An intuitive and simple user interface enables a data scientist, data engineer, or AI engineer to access petaFLOPS of computing power, efficiently develop and train new AI models and take them to production in a runtime environment on the same platform, with consummate ease.

[Learn More...](https://www.computational.zeblok.com/aiworkstation)

### Intelligence Marketplace

Zeblok’s Intelligence Marketplace provides easy access to a growing library of proven, original AI algorithms. Quality is ensured by our curation process, including closed loop validation, providing algorithm creators with a means of commercialization not previously available. We ensure that algorithms are easy to read, easy to use and easy to share. These include:

* Ai-Rover™ Notebook: Data Comprehension/Visualization Tool
* Ai-Rover™ Notebook For Time Series Data: Automated Predictive Model Builder&#x20;

[Learn More...](https://computationaldocs.zeblok.com/zeblok-computational-1/marketplace/intelligence-marketplace)

### Ai-HPC-WorkStation

Zeblok enables you to seamlessly scale to high-performance computing (HPC). Access HPC resources via a Jupyter Notebook.

One-click scalability for AI workloads.

### Ai-Data Lake

A data lake is a centralized repository that allows you to store all your structured and unstructured data at any scale. Zeblok Ai-Data Lake is a high-performance data-store that allows you to import, filter, and instantly analyze objects. Our solution is designed for performance, scales up with your data, and can provide industry-grade SSL security and data-redundancy for high availability of data at SSD speeds.

[Learn More...](https://computationaldocs.zeblok.com/zeblok-computational-1/data-and-metrics/datalake)

### Ai-APIᵀᴹ

Getting machine learning models into production is hard. Data scientists are not experts in building production services and DevOps best practices. The trained models produced by a data science team are hard to test and hard to deploy. This often leads to a time consuming and error-prone workflow, where a pickled model or weights file is handed over to a software engineering team.

Zeblok’s Ai-API™ Engine resides within Zeblok’s Ai-MicroCloud™ to facilitate deploying trained machine learning models anywhere. It bridges the gap between data science and DevOps, enabling teams to deliver AI inferences in a fast, repeatable and scalable way.&#x20;

[Learn More...](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/introduction)

### Ai-MicroCloudᵀᴹ Manager

Ai-MicroCloud™ Manager is the centralized management utility for Ai-MicroCloud™ and is used to manage and orchestrate all dependent components for Ai-WorkStation, Ai-HPC-WorkStation, Ai-Data Lake, Intelligence Maketplace and the Ai-API™ Engine.&#x20;

The Ai-MicroCloud™ Manager enables the enterprise administrator to define role-based access control, infrastructure plans (vCPUs, GPUs, memory, storage), define Namespaces and add accessible data centers, and provides metering information for resource utilization monitoring, billing or charge back purposes.<br>


# Create an Account


# Individual User

Individual User Signup Process

Click on this link <https://app.zbl-aws.zeblok.com/signup> to create an account with Zeblok Computational. You will be redirected to the Zeblok Computational Individual Signup page.

![Individual Signup Page](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/Gdij1ZGmBqlzUFTDBfYH/image.png)

Enter the required details and follow the further instructions which will be sent to your e-mail after signup details' validity processing.

After entering all the credentials as shown below . click on signup button and you will see this notification on the top . **Welcome to the Zeblok Computational AI Platform. Please check your email for an account activation link to complete your registration.**

![Fill all the Credentials](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/urUrQO5ZgFItfYlyTz2t/image.png)

After that go to the registered email id used while signing up and click on the link which is send to your registered email id

![Click on Link button ](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/vr4Iy3yin0gm4SbLMa80/image.png)

After Clicking on the **Link** button  you will be redirected to a page as shown below and then again click on login button as per the instructions on the page.

![](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/kpJCiE5YYgMtVVDZWXKJ/image.png)

After clicking on the login button as shown above you will be redirected to a page where you will have to enter your login credentials those credentials should match the ones which you entered while registering yourself.

![Click on Sign In after filling the detail](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/hoGrmHbjc8i4nuAgyofX/image.png)

After you Sign In  successfully you will be redirected to the dashboard.

![](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/PzQmxHpZQnXIC8AhRkHB/image.png)


# Sign In

Create free account here

Click on this link <https://app.zbl-aws.zeblok.com/> to Sign In  with your **Zeblok** Computational account.

![Sign In page ](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/fObKVPcZp5CqLHVthnuX/image.png)

Enter the required details and you will be redirected to the **Zeblok** dashboard page.


# Spawn Ai-WorkStation

Step By Step Guide for Spawning an Ai-WorkStation

### Overview&#x20;

Once you logged into the Zeblok Computational Application, you will get an option for **Spawn Ai-Workstation** as shown in the screenshot below.

![Figure 1: Dashboard](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/2UtgeRJdgCxeJhS2dWrw/image.png)

#### **Step 1**

Click on "Spawn Ai-Workstation", you will be redirected to a page as shown below.

![Figure 2: Spawn Ai-WorkStation](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/TIc4OqlJSzDgg2j3xXYW/image.png)

#### &#x20;**Step 2**

Select the Notebook which you want to use, whether it can be an Ai-WorkStations, Intelligence Marketplace, or Ai-HPC-WorkStations as shown below.

![Figure 3: 3 Types of Notebooks](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/TIc4OqlJSzDgg2j3xXYW/image.png)

#### **Step 3**

Depending on whether you are a beta user or not, all the plans will be unlocked for you and ready to use if you are a Beta User. Currently, everyone is given **BETA Access**.

#### **Step 4 (Beta User)**

Select the Plan which fulfills your requirements in terms of resources provided by clicking on the **Select Plan** button.&#x20;

![Figure 4: Select Plan for Beta User](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/pL7Sezuik8LBTq73O5Rs/image.png)

#### Step 5

Select the namespace in which you would like to deploy your Ai-WorkStation.

{% hint style="info" %}
**Note:** You have to be a member of a namespace to get the option to select a namespace.

Contact your OrgAdmin to add you in a namespace or, if you are an OrgAdmin, you can go to the namespace section and add the desired person as a member to a namespace.
{% endhint %}

![Figure 5: Select a Namespace](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/qj3EDHruY6d1iTGUyATN/image.png)

#### Step 6

Choose whether you want to mount your S3 bucket from our Ai-DataLake or not.

If yes, then select your bucketname from the dropdown.

![Fig. 6: Mount your S3 Bucket](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/L7aJSZZeYHqdxjRaRL0K/image.png)

#### **Step 7**

Enter the Notebook Name and finally spawn it as shown below. After successful creation, you will get your Notebook.

![Fig. 7: Name of Ai-WorkStation](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/tpjouIvJJgg9boSZfMXf/image.png)


# Spawn MicroService

Step By Step Guide for Spawning a MicroService

### Overview&#x20;

Once you logged into the Zeblok Computational Application, you will get an option for **Spawn MicroService** as shown in the screenshot below.

![Figure 1: Dashboard](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/2UtgeRJdgCxeJhS2dWrw/image.png)

#### **Step 1**

Click on "Spawn MicroService", you will be redirected to a page as shown below.

![Figure 2: Spawn MicroService](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/BbrA988Pqf1COfO2nca3/image.png)

#### &#x20;**Step 2**

Select the MicroService which you want to use, as shown below.

![Figure 3: MicroServices](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/BbrA988Pqf1COfO2nca3/image.png)

#### **Step 3**

Select the datacenter where you want to deploy it.

![Figure 4: Select DataCenter](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/XZA4blA3lbn4V6kvmjAN/image.png)

#### **Step 4**&#x20;

If you selected an Edge Datacenter in the previous step, you have an additional step where you are given an option to choose whether you want your deployment to be created on the **HUB** or any **SATELLITE** Node.

![Figure 5: Select HUB or SATELLITE NODE](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/wiy8fUWj2M9mHREC7K0k/image.png)

Select a Plan for your deployment. This step is common for both kinds of datacenters (EDGE and ENTERPRISE).

![Figure 6: Select Plan](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/ypd0KpF2SIBsocQ2dSbC/image.png)

#### Step 5

Select the namespace in which you would like to deploy your Ai-WorkStation.

{% hint style="info" %}
**Note:** You have to be a member of a namespace to get the option to select a namespace.

Contact your OrgAdmin to add you in a namespace or, if you are an OrgAdmin, you can go to the namespace section and add the desired person as a member to a namespace.
{% endhint %}

![Figure 7: Select a Namespace](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/imyOR43maM5BUsmrEqA2/image.png)

#### Step 6

This is a step given to you for configuring your microservice as you like.

**Ports:** The list of ports to be opened.

**Environment Variables:** Environment variables to be passed to the microservice container while starting.

**Arguments:** Arguments to be passed for the command parameter.

**Command:** Command to be passed to the microservice container.

![Figure 8: Configure your MicroService](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/Eb2KFlzS7vyC22P0ZmS1/image.png)

#### **Step 7**

Enter the MicroService Name and finally spawn it as shown below. After successful creation, you will be redirected to the Ai-WorkSpace and with your Spawned MicroService.

![Figure 9: Name your MicroService](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/9YPu2fFL4enQqPEyV3qK/image.png)


# Video Tutorial

The below tutorial walks you through all the detailed steps that are required for the spawning of any workstation or microservice into our MicroCloud

{% file src="/files/E4kEBGPWHO9wsf3mNBFd" %}


# FAQS


# Introduction

Introduction to Ai-APIᵀᴹ

### Overview

Ai-API™ makes moving trained ML models to production easy:

* Package models trained with ML framework and then containerize the model server for production deployment&#x20;
* Deploy anywhere for online API serving endpoints or offline batch inference jobs
* High-Performance API model server with adaptive micro-batching support
* Ai-API™ server is able to handle high-volume without crashing, supports multi-model inference, API server Dockerization, Built-in Prometheus metric endpoint, Swagger/Open API endpoint for API Client library generation, serverless endpoint deployment etc.
* Central hub for managing models and deployment process via web UI and APIs
* Supports various ML frameworks including:

Scikit-Learn, PyTorch, TensorFlow 2.0, Keras, FastAI v1 & v2, XGBoost, H2O, ONNX, Gluon and more

* Supports API input data types including:&#x20;

DataframeInput, JsonInput, TfTensorflowInput, ImageInput, FileInput, MultifileInput, StringInput, AnnotatedImageInput and more

* Supports API output Adapters including:&#x20;

BaseOutputAdapter, DefaultOutput, DataframeOutput, TfTensorOutput and JsonOutput

### Easy steps to Ai-AP&#x49;**™** Deployment

1. [Select your notebook](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/notebooks)
2. [Build Model](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/build-models)
3. [Deploy](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/deploy)

###


# ZBL Command Line Interface

## Install and Configure ZBL-cli in Jupyter notebook

Spawn a [Jupyterlab notebook](/info/1.2.5/spawn-workstation) and open it in the browser

Open the Terminal and perform the below procedures that are mentioned:

{% hint style="info" %}
Zeblok cli is used in the workstation to interact with AI-Microcloud for the purpose of model serving , pipeline and snapshot
{% endhint %}

#### Configure the command line interface with Zeblok account

```
zeblok configure <platformUrl> <datalake url> <datalakeSecret> <username>
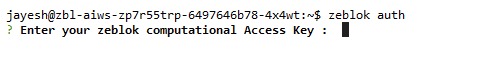
```

**Platform URL**: Please refer to the image attached ![](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/e3ThQD7z3cGM2OSSN9vb/WhatsApp%20Image%202023-07-26%20at%2019.27.55.jpg)

**Datalake URL**: Please contact the Zeblok Admin for this information.

**Datalake Secret:** Select the Kebab menu and go to the "Manage your Zeblok Account", then Click on the "Get Secret Key" Button and you can copy the alpha-numerical key under the "Ai-DataLake Secret Key" ![](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/3phNLrm1Wjk5mZ4LJD7k/WhatsApp%20Image%202023-07-26%20at%2019.41.07.jpg) ![](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/PIzKhCWyvTd7JmTGxEgY/WhatsApp%20Image%202023-07-26%20at%2019.47.09.jpg)

**Username**: You can copy your user name from the same page you got your Datalake Secret from, Please follow the below picture ![](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/uFjEVKgXTW5FfNqiceQS/WhatsApp%20Image%202023-07-26%20at%2019.54.14.jpg)

{% hint style="info" %}
When workstation is spawned this command is pre configured into your notebook with all configurations
{% endhint %}

#### Authentication of the Microcloud with the CLI

```
zeblok auth
```

<figure><img src="https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/kX2XxpAAuEKWmW7BsVjD/WhatsApp%20Image%202023-07-26%20at%2020.00.41.jpg" alt=""><figcaption><p>Once you enter the above command the cli will prompt for Access Key and Secret Key</p></figcaption></figure>

You can get both the credentials from the "Manage you Zeblok Account" option. Click on the "Get API Credential" button to reveal both the keys and the you can copy paste there from there.&#x20;

![](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/UhaTepv3m2hGMK6tiU5k/WhatsApp%20Image%202023-07-26%20at%2019.41.07.jpg) ![](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/kij6LgnW8sYtXKn7OBc0/WhatsApp%20Image%202023-07-26%20at%2020.12.42.jpg)

After you have entered both the keys into the CLI after then you can easily use the CLI to Build you own Models or to serve pre installed models using the Zeblok command line.

Run the below command to check if the ZBL-CLI working

```
zeblok
```

<figure><img src="https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/6CMzy9K0IHrBv49MIEPr/Screenshot%202023-07-26%20205038.jpg" alt=""><figcaption></figcaption></figure>

> Once the initiation of any services like model serving is initiated try not to regenerate the access key and secret key again in profile tab to avoid failure in updates to app .


# How to use the CLI

This document will guide you through the usage of Zeblok cli

## CLI Usability and commands.

### Show-URL <a href="#showurl" id="showurl"></a>

This command just outputs the `APP URL` and `datalake Url` configured in zeblok configure command

```
zeblok showUrl
```

### Snapshot <a href="#snapshot" id="snapshot"></a>

This command is used to create snapshot of your workstation on which it creates a docker image whose tag is emailed to the user on which that tag can be used to create a new workstation with current configuration

```
zeblok snapshot
? Enter the name for docker file getting generated : <Docker Image Name>
? Select your DataLake Bucket to Deploy (Use arrow keys) <Minio Bucket Selection>
```

#### Brief <a href="#brief" id="brief"></a>

Snapshot command copy all the files from your notebook with the same structure as in current one with that it also creates requirments.txt with all the installed packages in your current notebook and installs it when you spawn the new workstation with that docker image to have same configuration as you have currently .

> requirments.txt is generated automatically with `pip list --format=freeze`
>
> Base image for workstation used is `minimal-notebook:2023.09.20`

#### Components <a href="#components.2" id="components.2"></a>

1. `Docker Image Name`- The image name you want the docker to have
2. `Minio Bucket Selection` - Select the bucket where you want to store all the data of your notebook

### Openvino <a href="#openvino" id="openvino"></a>

This command is used to serve model using openvino

```
zeblok openvino
? Enter the path for generated IR model (without / at the end): <IR_OUTPUT_PATH>
? Enter the IR output name : <IR_OUTPUT_NAME>
? Select your DataLake Bucket to Deploy : <BUCKET_NAME>
? Do you want to auto-deploy? : <AUTO_DEPLOY>
? Select your namespace: <NAMESPACE>
? Select your DataCenter: <DATACENTER>
? Select your Kiosk: <KISOK>
? Select your Plan: <PLAN>
? Name of your Deployment: <DEPLOYMENT_NAME>
```

#### Components <a href="#components.3" id="components.3"></a>

1. `IR_OUTPUT_PATH` - Folder containing the \<IR\_OUTPUT\_NAME>.xml and the \<IR\_OUTPUT\_NAME>.bin
2. `IR_OUTPUT_NAME` - IR output name which is same for both .xml and .bin file in the `IR_OUTPUT_PATH`
3. `BUCKET_NAME` - Select the bucket where you want to store the model files
4. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
5. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
9. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

#### Ideal File Structure <a href="#ideal-file-structure" id="ideal-file-structure"></a>

![](https://3736424493-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FIaoQJiVgSMA5A1OImI99%2Fuploads%2F3ZyPif7g1wHtTByZFIf4%2Fimage-20231101-153215.png?alt=media\&token=cf658355-58b2-4059-9a60-c24ef55bd8b1)

> For openvino model serving to work the output path must contain 2 files with same name with extensions \*.xml and \*.bin

### Bentoml <a href="#bentoml" id="bentoml"></a>

Bentolml model serving serves a bentoml model served built using `bentoml build` command . It fetches the model with `bentoml list  --output json` command and lists one which you want to serve .

```
zeblok bentoml
? Select your Model to Deploy: <MODEL_NAME>
? Select your DataLake Bucket to Deploy : <BUCKET_NAME>
? Do you want to auto-deploy? : <AUTO_DEPLOY>
? Select your namespace: <NAMESPACE>
? Select your DataCenter: <DATACENTER>
? Select your Kiosk: <KISOK>
? Select your Plan: <PLAN>
? Name of your Deployment: <DEPLOYMENT_NAME>
```

#### Components <a href="#components.4" id="components.4"></a>

1. `MODEL_NAME` - Select the model built using the bentoml build command `bentoml build`
2. `BUCKET_NAME` - Select the bucket where you want to store the model files
3. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
4. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
5. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

> The model serving of bentoml needs bentoml installed on your workstation
>
> If there is no model to select in first question then try running `bentoml build` in the model creation .

### Mlflow <a href="#mlflow" id="mlflow"></a>

Mlflow model serving uses two process to serve a model first is to get model into your directory and second one is to serve that model

#### Commands <a href="#commands" id="commands"></a>

**1. Get model**

To get a model from mlflow register use command

```
zeblok mlflow
? Enter the mlflow url for model : <MLFLOW_TRACKING_URL>
? Enter the runId for model : <RUN_ID>
```

**Components**

1. `MLFLOW_TRACKING_URL` - Mlflow tracking URL where your model is stored to .
2. `RUN_ID` - Run id of the model you are willing to serve

To create a new mlflow microservice please refer to documentation of AI-Microcloud .

**2. Serve Model**

Once the command To get the model is done you will need to run modelserve command to serve model

```
zeblok modelserve
? Enter the rootPath for model in directory : <DOWNLOADED_MODEL_PATH>
? Enter the IR output name : <IR_OUTPUT_NAME>
? Select your DataLake Bucket to Deploy : <BUCKET_NAME>
? Do you want to auto-deploy? : <AUTO_DEPLOY>
? Select your namespace: <NAMESPACE>
? Select your DataCenter: <DATACENTER>
? Select your Kiosk: <KISOK>
? Select your Plan: <PLAN>
? Name of your Deployment: <DEPLOYMENT_NAME>
```

**Components**

1. `DOWNLOADED_MODEL_PATH`- Enter folder name where your model is stored .
2. `IR_OUTPUT_NAME`- Enter any name that you want to put for model .
3. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
4. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
5. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

{% hint style="info" %}
The model serving of mlflow needs mlflow installed on your workstation
{% endhint %}

### LLAMA <a href="#llama" id="llama"></a>

This command serves LLAMA model with CPP serving .

```
zeblok llamacpp
? Enter the path for generated IR model (without / at the end): <IR_OUTPUT_PATH>
? Enter the IR output name with its extention : <IR_OUTPUT_NAME>
? Select your DataLake Bucket to Deploy : <BUCKET_NAME>
? Do you want to auto-deploy? : <AUTO_DEPLOY>
? Select your namespace: <NAMESPACE>
? Select your DataCenter: <DATACENTER>
? Select your Kiosk: <KISOK>
? Select your Plan: <PLAN> 
? Name of your Deployment: <DEPLOYMENT_NAME>
```

#### Components <a href="#components.7" id="components.7"></a>

1. `IR_OUTPUT_PATH`- Enter the path where your model and `requirements.txt` file is situated .
2. `IR_OUTPUT_NAME` - Enter the model name with its extension whether its .gguml or .gguf
3. `BUCKET_NAME` - Select the bucket where you want to store the model files
4. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
5. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
9. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

> `IR_OUTPUT_PATH` must contain the model and `requirements.txt` file to work
>
> Make sure you enter `IR_OUTPUT_NAME` with its extension .
>
> Depending on the size of model it will take time around 2 to 3 hours

### VLLM <a href="#vllm" id="vllm"></a>

This command serves model with Vllm model serving .

```
zeblok vllm 
? Enter the directory name containing your model : <MODEL_DIRECTORY> 
? Select your DataLake Bucket to Deploy : <BUCKET_NAME> 
? Do you want to auto-deploy? : <AUTO_DEPLOY> 
? Select your namespace: <NAMESPACE> 
? Select your DataCenter: <DATACENTER> 
? Select your Kiosk: <KISOK> 
? Select your Plan: <PLAN> 
? Name of your Deployment: <DEPLOYMENT_NAME>
```

#### Components <a href="#components.8" id="components.8"></a>

1. `MODEL_DIRECTORY`- Enter the folder name where your model and files are situated inside the workstation .
2. `BUCKET_NAME` - Select the bucket where you want to store the model files
3. `AUTO_DEPLOY` - This is Boolean Input which defines if you want to deploy the model directly to AI-API
4. `NAMESPACE` - Namespace where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
5. `DATACENTER` - Datacenter where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
6. `KISOK` - Kisoks where the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
7. `PLAN` - Plan in which the ai api to be deployed and asked if `AUTO_DEPLOY` is marked as `YES`
8. `DEPLOYMENT_NAME` - Name of deployment used to deploy AI-API and asked if `AUTO_DEPLOY` is marked as `YES`

> Make sure `MODEL_DIRECTORY` you enter contains all the files related to model .
>
> Depending on the size of model it will take time around 1 to 2 hours


# Installing different frameworks

All the below commands will be installing the latest versions, for a particular version please follow the below syntax

#### Below Commands are also for utilization with Zeblok CLI

To Install Zeblok MLflow

```
pip install mlflow==2.5.0
```

To install Zeblok BentoML

```
pip install bentoml==1.0.25
```

To install Zeblok OpenVINO

```
pip install openvino==2023.0.0
```

#### Below command are utilized for installing frameworks on Minimal Notebook

To install any other packages

```
pip intsall {package_name}=={Specific version if any}
```

To install any Requirment.TXT

```
pip install -r $PATH/requirment.txt
```

To update any package

```
pip install -U {package_name}=={Specific version if any}
```


# Notebooks

Ai-APIᵀᴹ Engine: Notebooks

### Selecting a Notebook

Here, as an example, we are selecting the BentoML Notebook. You can find it using the search field on the Spawn Ai-WorkStation Page.

{% hint style="info" %}
**Note:**

The full walkthrough of spawning an Ai-WorkStation has been given at our [Spawn WorkStation Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/spawn-workstation) for your convenience.
{% endhint %}

![Figure 1: BentoML Notebook](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/hCjIyu77wZdmR2eSPlcA/image.png)

Taking BentoML as the Notebook and following all the steps from the Spawn Workstation Guide will give you an Ai-WorkStation ready to open.

{% hint style="info" %}
**Note:**

The final result of this example will get us a notebook which can identify the breed of an animal upon uploading the image of an animal.
{% endhint %}

Next Step is to start and open the notebook and run all cells to get a newly trained model.

![Figure 2: Run all Cells](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/VnFL9UAqAt3msD5Lr0rs/image.png)

![Figure 3: Name of newly Trained Model](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/KgcFkPSi5MktZekDJ9SO/image.png)


# Build Models

Ai-APIᵀᴹ Engine: Build Models

### Building Models Guide

Before starting to read this guide, it is recommended for you to read the[ Notebook Section](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/notebooks) of the Ai-API Concept.

After creating a newly trained model, comes the building stage.

For building process, the steps are as following:

* Open the integrated terminal that comes along with the notebook.

![Figure 1: Click on New Launcher](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/RIk704MbEUVfZW5qRRyx/image.png)

![Figure 2: Integrated Terminal](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/UuqDZVKaOkRGzJbJuVDd/image.png)

* Update the Cli ( Command Line Interface) for smooth process running.

```
npm i -g zbl-cli
```

![Figure 3: CLI Update](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/ntMzQ9lCmy6oeEYEZnQj/image.png)

* Configure your zeblok cli

```
zeblok configure
```

![Figure: Zeblok Configure](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/iPWGIra2t3jbXFRS9cZK/image.png)

* Run the command **zeblok auth** and enter your username and password&#x20;

```
zeblok auth
```

![Figure 4: Authentication Command](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/Da6L5oh9reBK1B1ilq2o/image.png)

* After successful authentication, run the command **zeblok runtime** which fetch the latest created by you and give a list of the models from which you can select the model you would like to deploy.

```
zeblok runtime
```

* Select the model and hit enter. The terminal will package your model and upload it to the database. This might take a minute or two.

![Figure 5: Model Selection (Runtime Command)](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/ba8RQqLQNZ3EUlVqsu1l/image.png)


# Deploy

Ai-APIᵀᴹ Engine: Deploy

### Deploying Models Guide

Before starting to read this guide, it is recommended for you to read the[ ](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/notebooks)[Build Models Guide](https://computationaldocs.zeblok.com/zeblok-computational-1/ai-api/build-models) of the Ai-APIᵀᴹ Concept.

After building a newly trained model, comes the deploying stage.

Now this is the part where our Ai-APIᵀᴹ Engine comes into play. The sidebar at the left side of your screen has a menu button of Ai-APIᵀᴹ which will lead you to our Ai-APIᵀᴹ Engine.

![Figure 1: Ai - Apiᵀᴹ Engine](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/9jf27mDVdhW6PL8kY1EG/image.png)

{% hint style="info" %}
**Note:**

The Ai-APIᵀᴹ Engine, on clicking, shows all the previous deployments you have done, or your organization has done (if you are an Organization Admin) after selecting a specific namespace of the deployments.
{% endhint %}

### For deploying process, the steps are as following:

* Click on Create Ai-APIᵀᴹ and then select the model. Here we are selecting the model which we just created in the previous Guide.

![Figure 2: Create Ai-Apiᵀᴹ](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/rivqAw0hK064xa9ikkLv/image.png)

![Figure 3: Select Trained Model](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/QHvKr2M6lqk5g28d8r8l/image.png)

* Then comes the selection of namespace (only if you are a member of one).

![Figure 4: Namespace Selection](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/ZEDfaYpSlLlyIlGVWbVy/image.png)

* Third step is to select the location where you want to deploy it.

![Figure 5: Select DataCenter](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/nzy77Y8wYPo1Gkim2Pir/image.png)

* If you selected an Edge Datacenter in the previous step, you have an additional step where you are given an option to choose whether you want your deployment to be created on the **HUB** or any **SATELLITE** Node.&#x20;

![Select HUB or SATELLITE NODE](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/7UDCurH8QbKJYswv6WBm/image.png)

* Name your Deployment and click on Create.

![Figure 6: Name of Deployment](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/PGF9iZquzb0lqulbX8Sn/image.png)

You will be redirected to our Ai-APIᵀᴹ Engine while the deployment is being done in the background. On successful deployment, the status of the deployment will change to **DEPLOYED.**&#x20;

{% hint style="info" %}
**Note:** On successful deployment, when the status is deployed, you are now given an option to monitor various performance metrics as highlighted in the images below.
{% endhint %}

![Figure 7: Deployment Successful](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/WzeUjvsnJpyuZE3Me1DB/image.png)

![Performance Monitoring](https://content.gitbook.com/content/IaoQJiVgSMA5A1OImI99/blobs/8mZr4yA7eyvCwgllOzXg/image.png)


---

[Next Page](https://computationaldocs.zeblok.com/info/llms-full.txt/1)